Output Length
- Source
- epoch.ai
- Author
- Epoch AI publications
- Date
Context
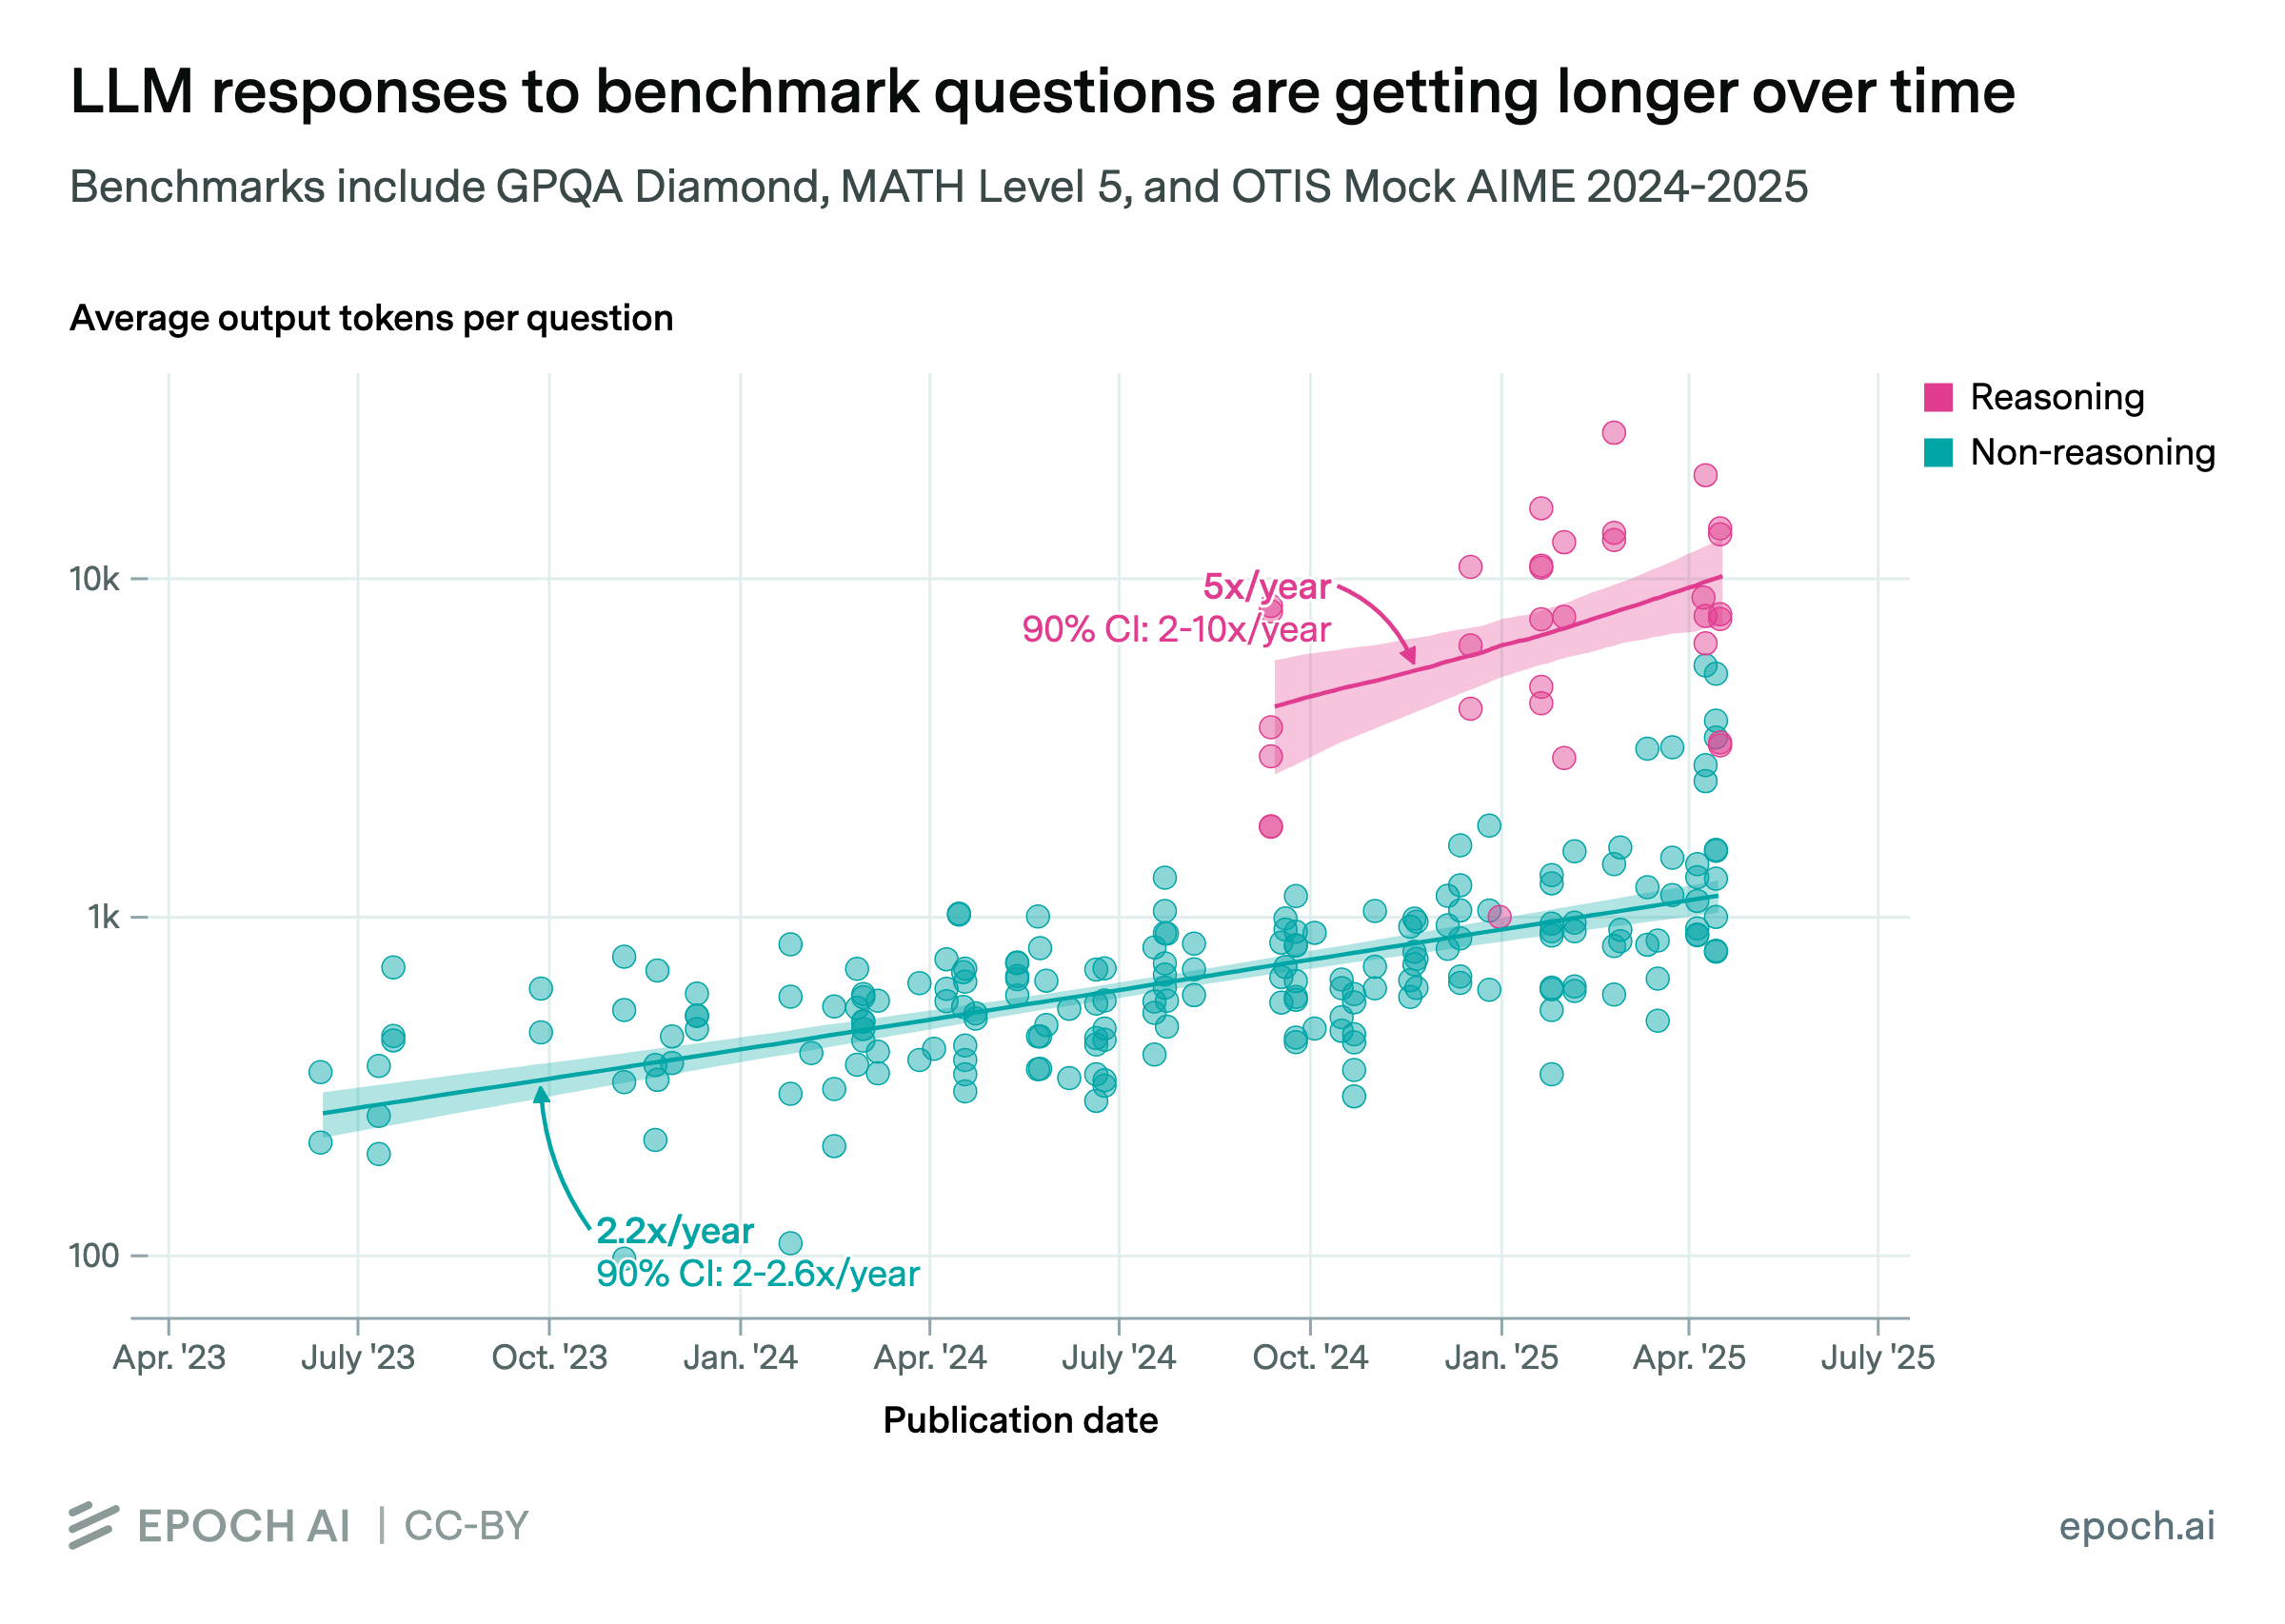
This April 2025 data insight from Epoch AI measures how long language models' answers to questions have become (epoch.ai). Length is counted in output , the word-fragment units a model generates. Reasoning models, which work through a problem in a stretch of thinking text before answering, have their thinking tokens included in the count. According to Epoch's internal benchmarks, reasoning models' responses are growing about 5x per year versus 2.2x per year for non-reasoning models, and reasoning models currently produce around 8x more tokens on average.
The data comes from Epoch's Benchmarking Hub and covers GPQA Diamond, MATH Level 5 and OTIS Mock AIME 2024-2025, chosen because they have the most coverage and draw similar response lengths: 77 models evaluated 235 times, 11 of them reasoning models, 65 not, and Claude 3.7 Sonnet run both ways. Where a model offers effort settings, Epoch used the highest; for OpenAI's reasoning models, moving from medium to high effort raised output by 1.6x. Epoch ties the reasoning-model growth to evidence that models produce more reasoning tokens as reinforcement-learning training is scaled up. For non-reasoning models it calls the cause less clear, suggesting longer windows, human judges preferring longer answers when generating training feedback, or models being trained to absorb step-by-step prompting.
The trend lines are rough. An exponential fit was only weakly, and not statistically significantly, preferred to a straight line, one of the two slopes shifts noticeably when individual models are dropped, and Epoch assumes these three benchmarks represent others. It also expected the clean split between reasoning and non-reasoning models to blur with future releases like GPT-5.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
Checking sign-in…
Loading comments…