Grok 4.7 closes in on Anthropic models on AA's due-diligence benchmark
- Source
- ArtificialAnlys
- Date
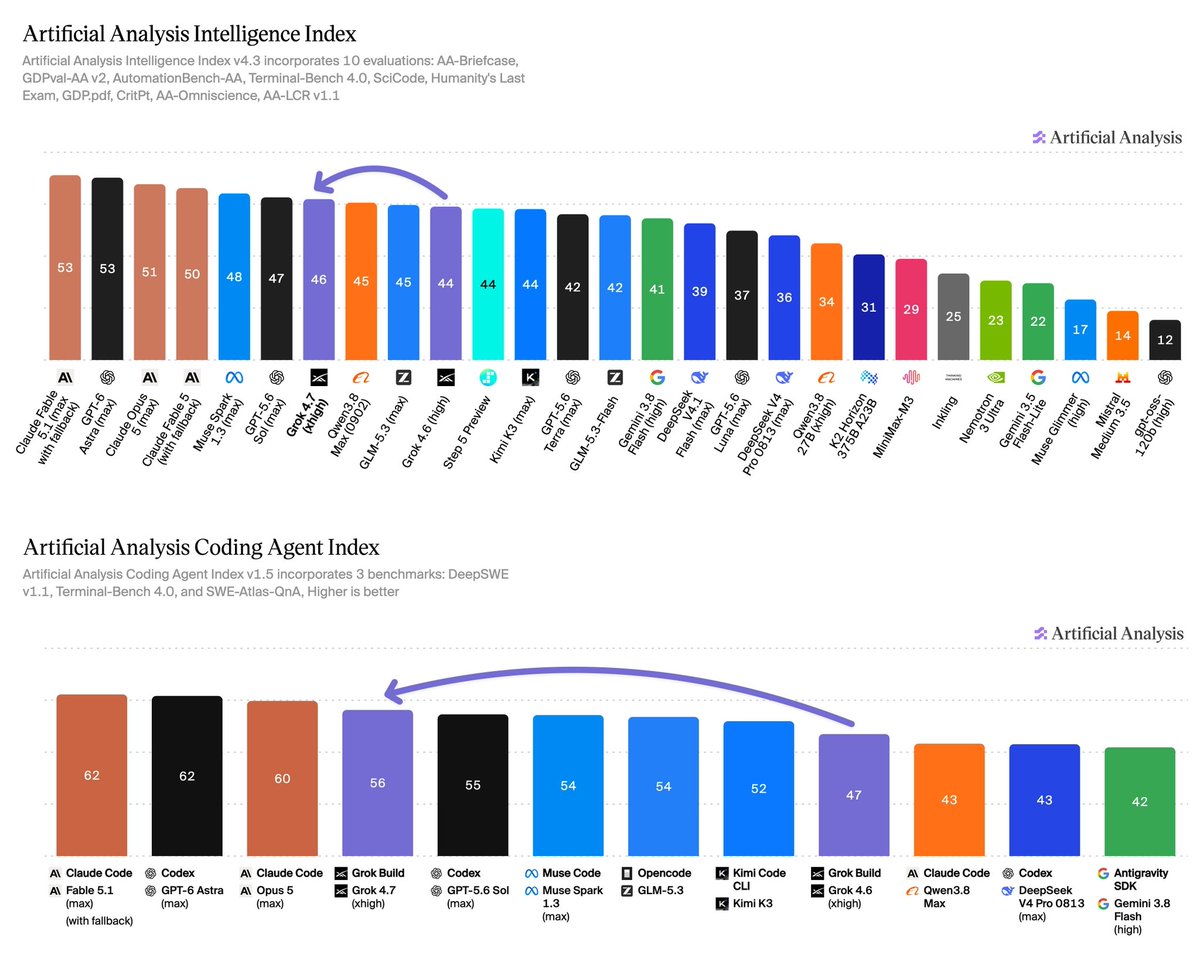
Grok 4.7 is behind only Anthropic models on AA-Briefcase, ranking just behind Opus 5 at ~50% of its Cost per Task Grok 4.7’s improvements over Grok 4.6 are clear in AA-Briefcase-Lite, our public due diligence scenario where models are tasked with building market models and target assessment decks. Grok 4.7 gains significantly in Analytical Quality Elo (1698 → 1994) with a slight regression in Presentation Elo (1531 → 1499). API cost to produce example decks: Grok 4.7 (xhigh) ~$8 vs. Grok 4.6 (xhigh) ~$4.40

Context
On Artificial Analysis's AA-Briefcase-Lite, a public where models build market models and target assessment decks for due-diligence-style work, Grok 4.7 ranks behind only Anthropic's models, just behind Claude Opus 5, at roughly half of Opus 5's measured cost per task.
The gain over the prior version, Grok 4.6, is concentrated in Analytical Quality, where its Elo score climbed nearly 300 points, from 1698 to 1994, with a small decline in Presentation Elo, from 1531 to 1499. Artificial Analysis's example API cost to produce a full deck rose from about $4.40 with Grok 4.6 to about $8 with Grok 4.7 at its highest reasoning setting, so the roughly 2x cost increase should be weighed against the analytical quality gain rather than read as a price cut.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.




Checking sign-in…
Loading comments…