Ling-3.0-flash-VL leads on efficiency, lags on agentic benchmarks, AA finds
- Source
- ArtificialAnlys
- Date

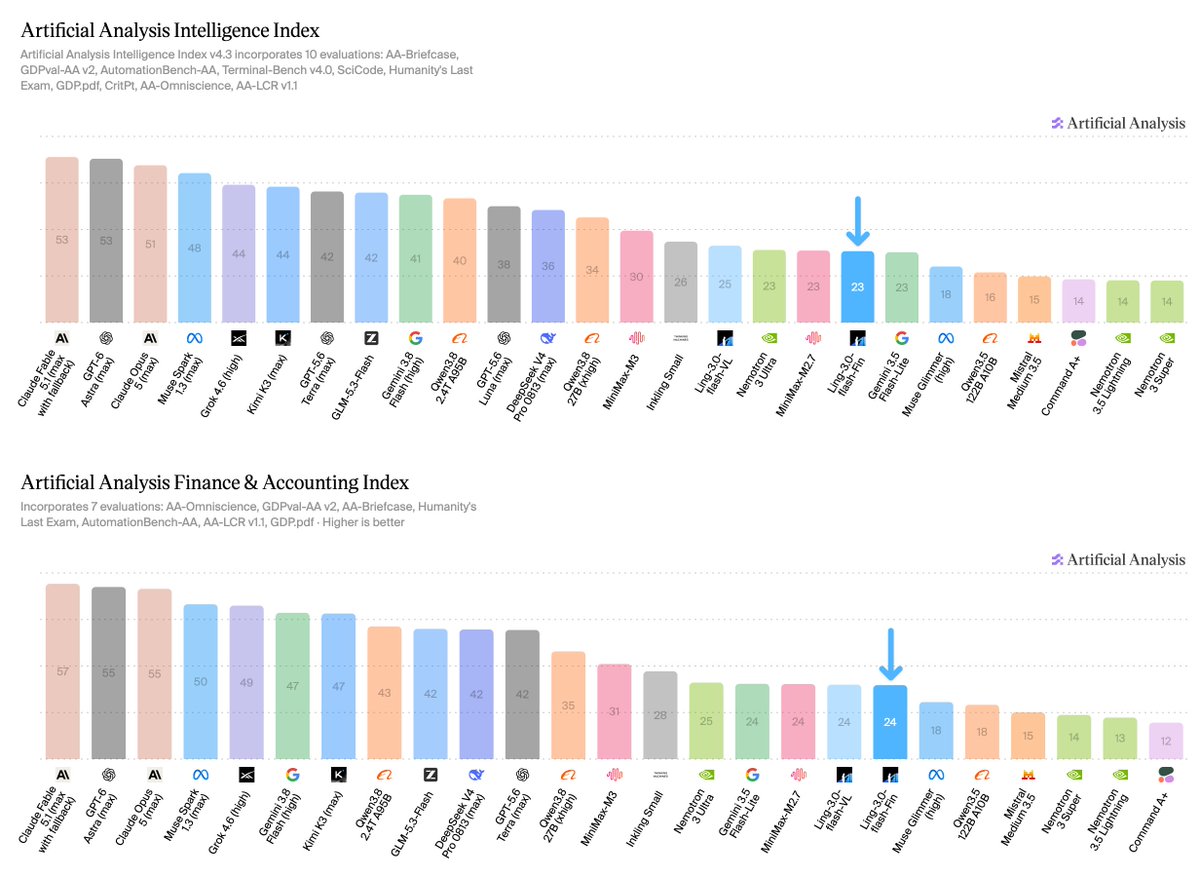
Ling-3.0-flash-VL, Ant Group’s new flash tier open weights model, scores 25 on the Artificial Analysis Intelligence Index. At 124B total parameters 5.5B active parameters, it sits on the Intelligence vs. Active Parameter Pareto Frontier @AntLingAGI has released Ling-3.0-flash-VL, an open weights reasoning model that adds image and video understanding to Ling-3.0-flash. Its mixture-of-experts architecture activates 5.5B of its 124B parameters per token, with support for a 256K token context window. Key results: ➤ Ling-3.0-flash-VL sits on the Pareto Frontier for Intelligence vs. Active Parameters, scoring 25 with 5.5B active parameters. Among models with a similar total size, Qwen3.5 122B A10B (Reasoning) scores 16 and Mistral Medium 3.5 (high) scores 15. ➤ Ling-3.0-flash-VL features lower hallucination rate than comparable models, but with limited factual recall. Ling-3.0-flash-VL scores 14% on AA-Omniscience Accuracy and 22% on Hallucination Rate. Inkling Small answers more questions correctly at 33% Accuracy, but has a much higher Hallucination Rate at 63%. ➤ There remains room for improvement for difficult agentic tasks for Ling-3.0-flash-VL. The model scores 16% on…

Context
Artificial Analysis benchmarked Ant Group's Ling-3.0-flash-VL, a model from InclusionAI with 124B total parameters, 5.5B of them active per , that adds image and video understanding to the earlier Ling-3.0-flash. It scores 25 on Artificial Analysis's Intelligence Index, which the firm says puts it on the Pareto frontier for intelligence relative to active parameter count, ahead of similarly-sized models like Qwen3.5 122B A10B and Mistral Medium 3.5.
That efficiency doesn't carry over to harder agentic tasks: Artificial Analysis measured just 16% on AutomationBench-AA, a business-workflow , and 0% on the harder Terminal-Bench v4.0. The model is also verbose, averaging roughly 50,000 output tokens per Intelligence Index task versus about 30,000 for Inkling Small, a model with a similar overall score, which raises the practical token cost of using it for reasoning-heavy work.
- mixture-of-experts — A model built from many specialist sub-networks where only a few activate per token, giving big-model capability at small-model running cost.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
- LLM — A large language model — the neural network behind tools like Claude and ChatGPT, trained on huge amounts of text to predict what comes next.





Checking sign-in…
Loading comments…