Grok 4.7 benchmarks show gains in agentic coding and knowledge work
- Source
- ArtificialAnlys
- Date
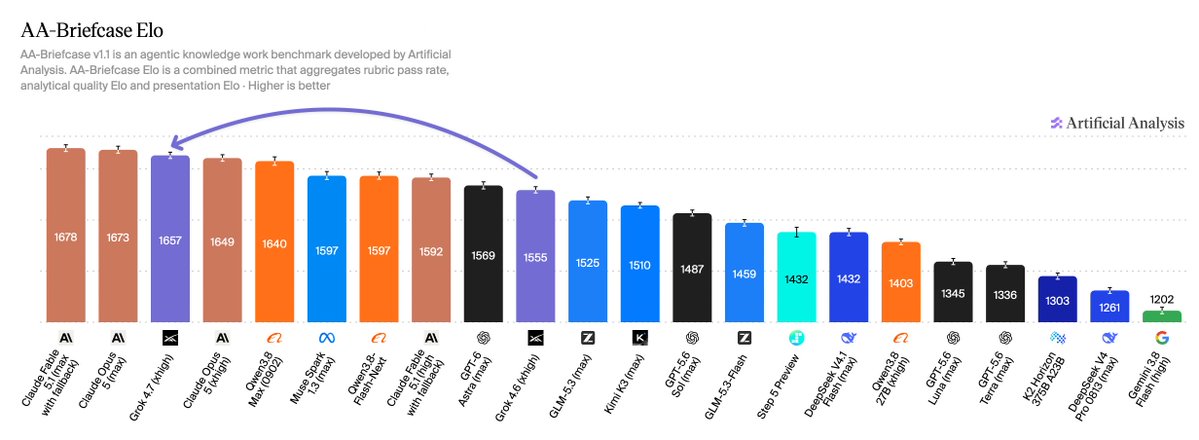
Grok 4.7 scores 46 on the Artificial Analysis Intelligence Index to bring SpaceXAI into the top 4 AI labs. Coding Agent Index performance has also improved, overtaking GPT-5.6 Sol Grok 4.7 scores +2 points over Grok 4.6 on the Intelligence Index, with strong performance on agentic knowledge work tasks. We evaluated the new model at xhigh reasoning effort. Congratulations to @SpaceXAI and @ElonMusk on the release! Key takeaways: ➤ Grok 4.7 joins the frontier of agentic knowledge work: Grok 4.7 gains +111 Elo over Grok 4.6 (high) on AA-Briefcase, our private benchmark for long-horizon agentic knowledge work, scoring 1657 Elo and placing it alongside Claude Opus 5 and Claude Fable 5.1 at the frontier. On GDPval-AA, it scores 1695 Elo, +90 ahead of Grok 4.6 (high). ➤ A leap in coding agent performance: Grok 4.7 (xhigh) with Grok Build scores 56 on the Artificial Analysis Coding Agent Index, up +9 points from Grok 4.6 (xhigh). Among models in their native harnesses, Grok 4.7 + Grok Build now ranks 4th, behind only Claude Fable 5.1, GPT-6 Astra, and Claude Opus 5. ➤ Incremental performance changes elsewhere: Outside of agentic knowledge work, Grok 4.7 broadly matches Grok 4.6…

Context
Artificial Analysis's testing of Grok 4.7, run at its highest reasoning setting, scores it at 46 on the Intelligence Index, two points above Grok 4.6, enough to put xAI among the top four labs by this measure. The clearest gains are in agentic work: +111 Elo on AA-Briefcase, Artificial Analysis's for long, multi-step knowledge work, putting it alongside Claude Opus 5 and Claude Fable 5.1, and +90 Elo on GDPval-AA, its agentic performance benchmark.
Paired with its own Grok Build coding , Grok 4.7 also scores +9 points on Artificial Analysis's Coding Index, now ranking fourth among models tested in their native harnesses, behind Claude Fable 5.1, GPT-6 Astra, and Claude Opus 5. That progress came with a real rise in spend: Grok 4.7 used about 81,000 output tokens per Intelligence Index task at this setting, more than double Grok 4.6's roughly 36,000 and about triple GPT-6 Astra's roughly 27,000, separate from its unchanged headline API pricing.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
- agent harness — The scaffolding around a model that turns it into a working agent — the loop, the tools it can call, and the rules for when to stop.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.




Checking sign-in…
Loading comments…