Intel
Page 25
Artificial Analysis benchmarks Ling 3.1 Flash 1019, a 560B (25B active) MIT-licensed open-weights model with 1M context. It scores 44 on Intelligence Index v4.3, with agentic gains but 145k output tokens per task and $1.49 cost per task.
Why it mattersAn MIT-licensed open-weights reasoning model with a 1M context window and low per-token prices, with measured agentic gains and 40% more output tokens per task. Cost per task matters more than list price.

How Anthropic ships the #1 LLM in the World safely: Separating the Brain from the Hands
Latent Space talks with Anthropic's Katelyn Lesse and Angela Jiang about running the Claude Platform.

How Anthropic ships the #1 LLM in the World — with Katelyn Lesse and Angela Jiang
Latent Space talks with Anthropic's engineering and product heads about Managed Agents design, credential isolation, a Rust rewrite of the Messages API validated with shadow traffic, memory, evals.
Why it mattersExplains how Anthropic decouples an agent's brain from its sandbox so a sandbox failure does not kill the agent, and how credentials are used without entering the sandbox. Useful design patterns for agent builders.
Discovering Vulnerabilities With Claude
Anthropic details five attack chains found by an unreleased internal model, including one-click Chrome RCE with 62 assigned CVEs, a Safari chain, an Android lock screen bypass and zero-click Linux RCE.
Why it mattersA frontier model produced full exploit chains, including sandbox escapes, against heavily hardened software. Defenders should plan for faster vulnerability discovery and shorter patch windows.

Cognition released FrontierCode 2.0, a coding benchmark with maintainer-built tasks, underspecified prompts and a higher mergeability bar. The top model scores 45%. The thread reports price-versus-performance tiers and shows rankings that differ from DeepSWE.
Why it mattersRankings differ from DeepSWE: models that top that benchmark land mid-pack when prompts are underspecified and mergeability is judged. Cost per task is reported, so engineers can weigh score against spend.

LangChain's postmortem on Content Studio, a Slack design agent that makes on-brand videos, graphics and decks. Covers router skills, wiki context, code-enforced gates, async subagents, per-thread sandboxes, two-loop memory, and pruning rules as models improve.
Why it mattersShows how to build a long-running multi-agent harness: encode taste as skills and code-enforced gates, run subagents asynchronously, and delete workaround rules as models improve. Includes cost data and a forkable repo.
Jev Decision Models Ai Agents Cline
Cline walks through TypeSafe AI's Jev, a Decisions model that scores or classifies a state instead of generating tokens.
Why it mattersAgent guardrails like tool-call approval run on every step, so LLM latency and cost add up. A structured decision model used as a before-tool hook offers a faster, cheaper way to classify risk, though the speedup claims are vendor-reported.
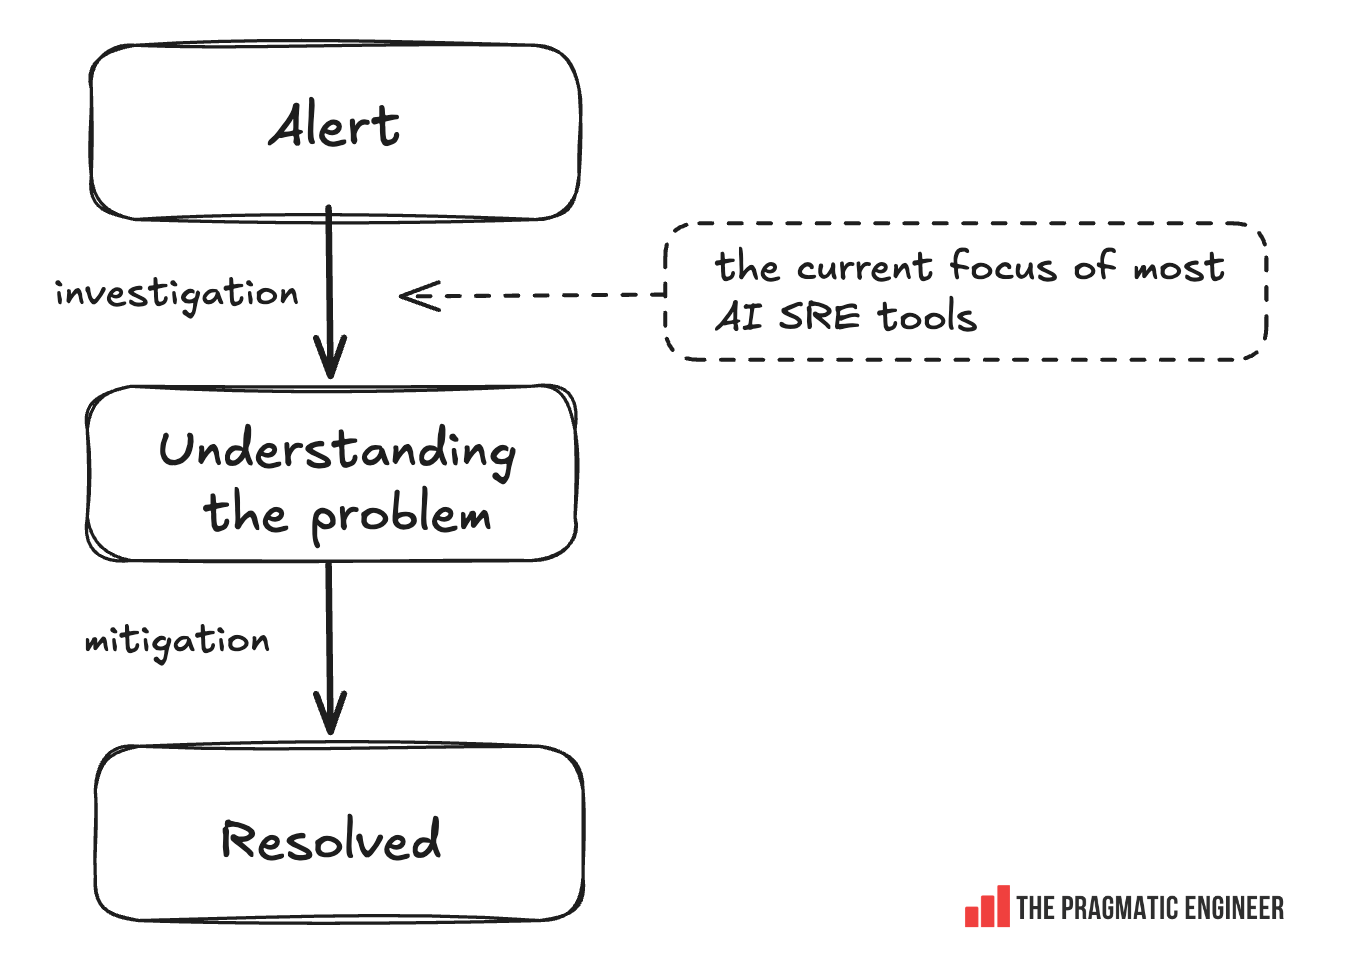
AI SRE: what is it, how could it change on-call – and does it work?
Gergely Orosz examines AI SRE agents, from Microsoft's staged demo to OpenAI's Sevbot and ING's in-house build.
Why it mattersGathers how teams at OpenAI and ING are building AI SRE agents and whether autonomous incident response holds up. Useful for deciding where agents belong in on-call rotations.

Google AI details how Genie 4 works: Gemini translates natural-language requests into actions, plans complex events and tracks the scene while the world runs in real time. The model also adds ambient audio and adaptive dialogue. Release access and benchmarks are not stated.
Why it mattersGenie 4 uses Gemini to turn natural-language requests into actions, plan events and track scene state, adding ambient audio and live dialogue to a real-time world model.
Can we trust LLMs to judge whether a research idea is novel?
Ai2 releases a benchmark, data and code measuring how well LLMs judge the novelty of scientific ideas.
Why it mattersTests whether an LLM novelty judge can be trusted, with released data and code. Anyone building automated research or LLM-as-judge pipelines gets a benchmark to validate judges before relying on them.

Google DeepMind Unveils Genie 4, an Interactive World Model
Google DeepMind introduces Genie 4, a world model that turns prompts or images into explorable, controllable environments in real time.
Why it mattersGenie 4 generates interactive, explorable environments from text or an image and is pitched for simulating scenarios such as robot practice.

Genie 4: A new generation of world simulation
Google DeepMind announces Genie 4, a world model with native audio and real-time text steering, in trusted-tester preview, coming to AI Ultra subscribers and early partners on the Gemini API and AI Studio.
Why it mattersGenie 4 generates interactive, audio-enabled simulations steerable by text. Developers can expect Gemini API and AI Studio early access, and agent builders gain a route to simulated training environments.
Fine-Tuning NVIDIA Nemotron to Know Local Rules, Not Just Local Languages
NVIDIA walks through fine-tuning Nemotron for regional rules.
Why it mattersLays out a reproducible pipeline for adapting an open model to local procedures using synthetic persona conversations and LoRA. The repo includes agent skills so a coding agent can assemble the workflow.
openai-python v3.40.0
openai-python 3.40.0 adds prompt cache breakpoint TTL options to the API surface, alongside CI and dependency maintenance.
Why it mattersYou can now set TTL options on prompt cache breakpoints from the official Python SDK, giving finer control over how long cached prefixes live and what repeated agent calls cost.

What a $900M Bank Error Teaches Us About AI Agents - John Feminella, Two Sigma
Two Sigma's John Feminella uses the 2020 Citibank/Revlon $900M payment error to argue for agent governance.
Why it mattersShows how to grant agents real autonomy without blanket lockdown, using five concrete controls including purpose-scoped tool access and classifier-routed approvals to avoid approval fatigue. Useful for anyone designing agent governance.
3 Ways to Boost MoE Inference on NVIDIA DGX Spark
NVIDIA profiles Ling-3.0-flash on DGX Spark and applies three optimizations (Humming MoE kernels, FP8 LM head, multi-token prediction), reporting 42.5% higher decode throughput and 24.5% lower latency.
Why it mattersDecoding at batch size 1 was memory-bound, so the fixes target weight reads and token acceptance. The measured stack of kernel, FP8 head and speculative decoding is reusable for local MoE inference.
Sakana API Platform、エンタープライズ向けにアーリーアクセスプログラムを開始
Sakana AI opens early access to its enterprise API platform. Fugu and Fugu Ultra orchestration models are available first, with Namazu and Fugu Max to follow.
Why it mattersSakana's Fugu orchestration models are now callable through an OpenAI-compatible API with org/workspace management, RBAC, audit logs and spend caps. Teams can switch endpoints without rewriting client code, via an early-access program.
Coding From the Himalayas With an Offline AI Agent
A principal engineer tests how much of a coding-agent workflow survives with the internet off, running an agent locally on a laptop and noting which tasks hold up during network and power outages.
Why it mattersShows which everyday coding-agent tasks (explaining code, debugging tests, small refactors) can run on a local model with no network, useful for flights, outages and restricted environments.
OpenHands v1.34.0
OpenHands 1.34.0 adds a per-conversation Docker runtime with a Settings Runtime page, automation tag filtering and editing, sandbox-aware new conversations.
Why it mattersOpenHands v1.34.0 lets each conversation use its own Docker runtime and moves the static-server session key out of argv into the environment. Users of the agent get isolation and a security fix.
Markdown is 40× more token-efficient with SQLite
Native benchmarks agents querying 11,000 records stored as Markdown folders versus SQLite, finding roughly 40x fewer tokens per correct answer with SQLite.
Why it mattersSuggests structuring agent context in SQLite can cut tokens per correct answer by about 40x versus Markdown files. Typed frontmatter is a workable middle ground.

Ant Ling open-sources Ling-3.1-flash-1019 plus a Ling-3.1-flash-base checkpoint. It reports an Artificial Analysis Intelligence Index of 44 (up from 41), with gains on AA-Briefcase, AutomationBench-AA, CritPt and SciCode. Weights are on Hugging Face and ModelScope.
Why it mattersAn open-weights model scoring 44 on the Artificial Analysis Intelligence Index, with a base checkpoint for further training, is a new option for self-hosted agent work. Gains are reported on automation and tool-use benchmarks.
ui shadcn@4.23.0
shadcn 4.23.0 upgrades its MCP server to the MCP TypeScript SDK v2, serving protocol 2026-07-28 and earlier.
Why it mattersIf you extend or embed the shadcn MCP server, the export is now an McpServer and createServer() returns a fresh instance per connection. Handlers must move to registerTool or server.server.setRequestHandler.
Why is my local Qwen sending requests to Alibaba Cloud?
Vals AI scanned its Qwen evaluation traces for Aliyun hostnames after outside reports.
Why it mattersIf you run Qwen models as agents, they may issue outbound requests to unexpected cloud endpoints. Egress allowlists and trace scanning for such hosts are a practical defense.
Thomson, One N at a Time
Vals AI explains how ten Claude Sonnet 5.5 agents proved the seven-electron Thomson problem in Lean.
Why it mattersTen parallel agents produced a machine-checked proof in roughly 15 hours. The post explains which proof strategies worked and where they stop (N=32 needs a new idea), showing how far long-horizon agent proving currently reaches.
AI promised less work. I've never worked more
A technology VP uses seven years of GitHub contribution data to show that running several coding agents in parallel raised their workload.
Why it mattersCheap implementation leads engineers to run many agents in parallel, and each agent's questions and diffs force context switches. A VP of Technology shows contribution data back at full-stack pace, with burnout risk worth managing.
opencode v2.2.0
opencode v2.2.0 adds experimental desktop plugins, image and decision generation APIs for plugins and the SDK, keyed session instructions that avoid busting the prompt cache, restored desktop Todo tool.
Why it mattersPlugins can now add or update session instructions without editing the system prompt, so the prompt cache stays valid and entries survive compaction. Configurable cache TTLs per provider help control cost on long sessions.

Why Are We Still Governing AI Agents Like Software? - Tim Tyler, Gravitee
Gravitee's Tim Tyler outlines the Agent Accountability framework.
Why it mattersGives a structured model for treating agents as accountable workers: named human sponsor, scoped authority, oversight scorecards and recourse steps. Useful when designing agent identity and permissions.
Can we trust LLMs to judge whether a research idea is novel?
Ai2 introduces Old Ideas, Novel Problems, a study and benchmark measuring how reliably LLMs judge research-idea novelty.
Why it mattersLLM novelty judges are used to filter ideas from automated research agents. Ai2 releases a benchmark, data and code to test how reliable those judges are before you depend on them.

300 Agents, 60 People: How We Secured Our Own AI Agents - Aiden Sochowski, Runlayer
Runlayer reports what it found logging every session and tool call across 300+ internal agents.
Why it mattersSession-level logging of every tool call surfaced real attack patterns and cost blowups. It shows why gateway visibility and scoping agents from observed behavior matter.
[AINews] Anthropic files for $2T IPO in 2 weeks: 1400% growth rate, 48% of revenue through cloud partners, 85% margin, $1B op profit in Q2, $134B cash in bank and $10B lifetime burn
AINews digests Anthropic's S-1.
Why it mattersThe filing's disclosed margins, cloud-partner revenue share and cash position bear on the future cost and availability of Claude.

How a Trading Firm Ships New AI Models the Same Day - Noyan Tokgozoglu, Optiver
Optiver's head of AI Engineering walks through an on-prem AI platform.
Why it mattersShows how a production firm adopts new models within a day using internal golden sets, and how it keeps spend in check through a gateway with routing and budgets.
ElevenLabs on AI Gateway
Vercel AI Gateway now serves 14 ElevenLabs models across speech to text, streaming TTS, realtime voice agents, music, sound effects and multi-voice dialogue.
Why it mattersYou can add transcription, realtime voice agents and generated audio to an app through one gateway key, with usage and cost tracked beside your LLM traffic. A 50% discount runs through November 9.

T3 Code 0.1.3 ships a redesign, two-click guest thread sharing, up to 85% less data loaded on thread open, 60% shorter agent instructions, smaller MCP schemas, steer-by-default, LAN connect, and broader file previews.
Why it mattersT3 Code cut its agent instructions by 60% and shrank MCP tool schemas by a third, which lowers per-session context cost, and it now defaults to steering a running agent rather than queueing messages.
The fx adapter now runs the harness on the host
The AI SDK's fx adapter for HarnessAgent now runs the harness in the host process while the sandbox isolates only filesystem and shell operations.
Why it mattersModel credentials no longer enter the sandbox, shrinking the exposure surface of agents that run code. You also gain mid-turn steering, schema output, tool filtering and resumable sessions.
Ling 3.1 flash 1019 released
inclusionAI releases Ling-3.1-flash-1019, an MIT-licensed hybrid-linear MoE with 560B total and 25B active parameters and a 1M-token context.
Why it mattersAn MIT-licensed 560B MoE with 1M context and 25B active parameters can be self-hosted via SGLang on 8×H200. Reported agentic gains (AutomationBench-AA 62% to 68%) make it a candidate open model for agent workloads.
Linear-Time Context Compression with State-Space Encoding
Boa Compressor uses a Mamba state-space model to compress arbitrary-length context in one linear-time pass for a frozen target LLM, trained by logit distillation.
Why it mattersSoft-prompt context compression has needed an expensive Transformer pass, which limited it to reusable contexts. A linear-time SSM encoder makes compression workable online for a frozen LLM.
Navigating Epistemic Parity in LLM Agents: A Benchmark for Cross-Source Conflict Resolution Between Memory and Procedural Skills
A benchmark of 52 scenarios tests how LLM agents resolve conflicts between memory and procedural skills across factual, format, procedural and permission contradictions.
Why it mattersAgents that inject both memory and skill files into context can receive contradictory instructions with no defined precedence. This benchmark measures how models adjudicate and whether they disclose the conflict to the user.
From Cosmetic to Structural: A Paired Experiment on Metric-Guided Agentic Refactoring
A paired experiment gives the gptme agent CodeScene MCP code-smell reports and CodeHealth scores.
Why it mattersGiving a coding agent code-health feedback through MCP shifts it from cosmetic to structural refactors, but below roughly CodeHealth 5 to 7 it can cause regressions. That tells you when guided refactoring is safe to automate.
Recursive Semantic Divergence for LLM Agent Consistency
Recursive Semantic Divergence is a trajectory-level metric for LLM agent consistency.
Why it mattersTask-success scores miss agents that behave differently on identical runs. RSD measures cumulative semantic disagreement between two rollouts from the same state, giving a way to quantify reliability before deployment.
WebUniverse: Scaling Verified Training Data for Agentic Web Development
WebUniverse builds verifiable front-end development tasks and trajectories from open-source repos and real pages.
Why it mattersPublic trajectories for front-end agent training have been scarce. WebUniverse releases 15K executable environments and verified trajectories, and fine-tuning on them lifted a 35B-A3B model's Vision2Web score from 51.7 to 68.3.
Speculative Forking: Turning Idle Wait into Parallel Exploration for Repository Environment Setup
SpecBuild applies speculative forking to LLM-based repository environment setup.
Why it mattersEnvironment setup agents lose time waiting for slow commands before trying the next route.
Ling 3.0 flash Sante fp8 released
inclusionAI releases an FP8 build of Ling-3.0-flash-Sante, a healthcare-tuned hybrid-linear MoE with 124B total and 5.1B active parameters and 256K context.
Why it mattersAn open-weight, MIT-licensed 124B MoE with only 5.1B active parameters, specialized for medical reasoning and tool-using research workflows, now ships in FP8 for cheaper serving. It is a research model, not a medical device.
pydantic-ai v2.62.0 — v2.62.0 (2026-10-26)
pydantic-ai v2.62.0 lets thinking effort change mid-conversation for OpenAI and Anthropic, adds model error categories, stores summarizing compaction as a CompactionPart.
Why it mattersSeveral defaults change in this release. Hosted MCP tool names get a service prefix, and compaction summaries move out of the system prompt. Agents built on pydantic-ai should check these compatibility notes before upgrading.
ollama v0.40.12
Ollama v0.40.12 adds Liquid AI's LFM3 family (1.7B text, vision, audio, omni) and d1 2B decision models on Apple hardware.
Why it mattersYou can now run Liquid AI's LFM3 models, built for tool calling and structured output, locally with one command on Apple hardware. The release also speeds up prompt processing and adds DFlash2 speculative decoding on MLX.
Vercel Agent sessions now cost 67% less
Vercel Agent sessions now cost 67% less on average after a rebuild of context management, improved prompt-cache reuse, updated CLI skills and leaner planning.
Why it mattersIt shows which levers cut agent token cost: incremental context handling, preserving cacheable context across turns, and tighter planning guidance. Billing rates are unchanged, so the savings come from fewer tokens.
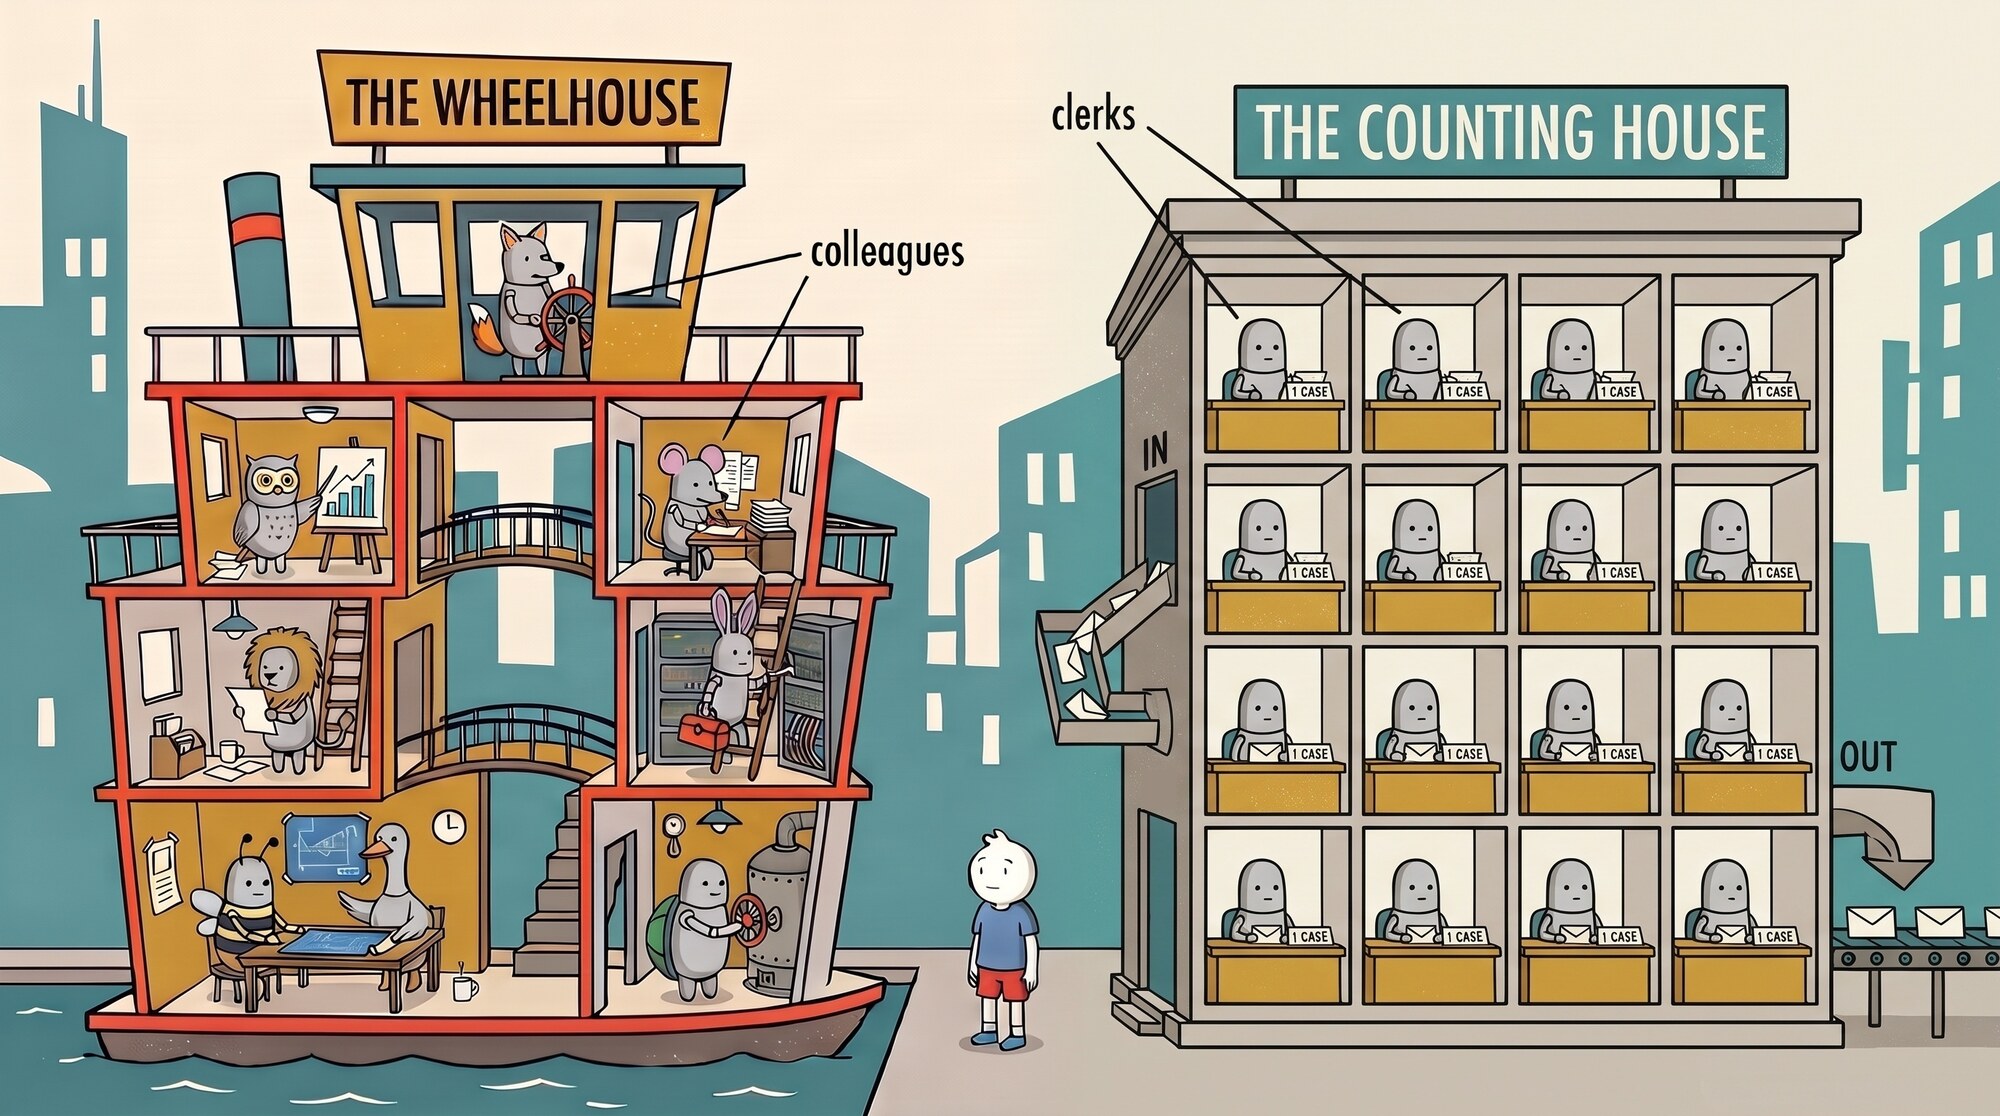
The Counting House
Steve Yegge introduces the Counting House, a pattern for adding AI to large-volume human work like customer service and claims.
Why it mattersDescribes a deployment pattern that puts lower-tier models on controlled rails and measures them against humans. It targets cost, quality and ramp-up in customer service and claims work, without waiting for coding-agent adoption to mature.
Csam Screening
OpenRouter will scan all inference requests in flight for CSAM using hash matching and suspected-content review.
Why it mattersIf you route prompts through OpenRouter, even Zero Data Retention requests will be screened and may be retained for review and legal reporting. Reassess compliance and privacy assumptions for sensitive workloads.
HarnessAgent now supports image inputs for all harness adapters
The AI SDK HarnessAgent layer now takes image inputs on every adapter, including Claude Code, Codex, Cursor, Copilot, Cline, OpenCode and Pi, via mixed text and file content parts.
Why it mattersYou can pass screenshots and images to any supported coding-agent harness through one AI SDK message format instead of per-harness handling.
Introducing Authenticated Fetch
Browserbase's Fetch API now accepts a Context ID and sends saved cookies with the request.
Why it mattersAgents that already logged in through a Browserbase browser can fetch authenticated pages cheaply by passing a Context ID. This avoids a full browser session per retrieval, though it only suits pages that render without JavaScript.
Vercel Plugin now available in OpenCode
Vercel released its plugin for OpenCode 2, bundling skills for the AI SDK, Functions and Workflow, specialist deployment and performance agents, /vercel:deploy and /vercel:env commands.
Why it mattersOpenCode users can now install Vercel guidance, deploy and env commands, and the Vercel MCP server in one plugin, instead of wiring them manually.
An index of the vibe-coding frontier. Corrections welcome.