Intel
Page 29Benzi – A Code Intillegence/Harness Beating Claude Code and CodeGraph
Benzi publishes head-to-head benchmarks of its coding harness against Claude Code and CodeGraph across 24 GitHub bug fixes and SWE-bench Verified, tracking source lines read, wall-clock time and cost per fix to show how harness design affects context efficiency.
Artificial Analysis benchmarked Octen Search using its Stirrup agent harness: it scores 77 on the Search Index (third place), leads on speed at 16.9s per task and 0.2s per query, and is among the cheapest providers, driven by strong BrowseComp results.
Why it mattersOcten Search ranks third on accuracy but delivers the fastest per-query latency and among the lowest costs, a concrete tradeoff for teams picking a search backend for agent pipelines.
Control who can manage connectors in Vercel Connect
Vercel Connect adds a Connector Permissions setting.
Why it mattersIf your team uses Vercel Connect to give agents credentialed access to external services, you can now restrict who is allowed to create or modify those connectors, reducing accidental credential exposure.
Together AI expands fine-tuning service with more models, live metrics, and finer controls
Together AI's fine-tuning platform adds support for new open-weight models (GLM-5.3, Kimi K2.7, Qwen and Gemma variants), live experiment tracking, dataset validation before training.
Why it mattersTogether AI's fine-tuning service now supports frontier open models like GLM-5.3 and Kimi K2.7, adds live run comparison and validation-loss stopping.

Zero Data Retention
OpenRouter breaks down what Zero Data Retention actually covers: provider-side storage of prompts and responses, not data in transit, your own logging, or third-party tools.
Why it mattersIf you're routing sensitive prompts through third-party inference, this clarifies that ZDR only covers provider-side storage, not your own logs or plugins, and shows how to enforce it at the request level.

Text To Speech
Step-by-step OpenRouter tutorial for its OpenAI-compatible text-to-speech endpoint.
Why it mattersGives a working integration path for text-to-speech across multiple providers through one API key and one request shape, including the specific gotchas (default format, per-model voice support) that break naive implementations.

Levelsio argues most end users will never touch code or even a chat interface explicitly: they'll just ask an AI to do bookkeeping or file taxes, and the app layer will vanish the way personal homepages did after Facebook, reshaping what building software for users means.
Why it mattersFrames a concrete shift for AI product builders: the target user for many AI-native tools is someone who never sees code or a dev-style interface, only a request and a result.

Vals AI, with marimo and CoreWeave, launched the RSI Index, a third-party benchmark scoring frontier models on AI-research tasks against the best published human results; current models can attempt the work but remain far from the human frontier.
Why it mattersA benchmark specifically measuring how close models are to automating their own research gives practitioners a concrete number to watch instead of relying on qualitative claims about self-improvement risk.
NVIDIA's Nemotron 3 Embed 8B took the #1 spot for combined nDCG@10 on Perplexity's Q2D-Web benchmark, evaluated across 190M web documents and nearly 70K agent-reformulated queries in 10 languages.
Why it mattersA top embedding-model result on a large, multilingual, agent-query benchmark gives a concrete data point for choosing retrieval models in agentic search and RAG pipelines.

GitHub Copilot app for Beginners: Using the diff, terminal, and browser
GitHub walks through the Copilot app's diff, terminal, and browser panels, showing how to review an agent's code changes, run project commands.
Why it mattersShows the concrete workflow (diff, terminal, browser) GitHub Copilot users get without leaving the app, useful for anyone onboarding to agentic coding review loops.
Native is now the future of mobile at Shopify
Shopify is reverting from React Native to native Swift and Kotlin, citing agents that now handle enough implementation, translation, testing and review work that dual-codebase maintenance is no longer the deciding cost factor it was in 2020.
Why it mattersOne of React Native's largest maintainers is reversing a six-year platform bet because AI agents changed the cost calculus of maintaining two native codebases, a concrete sign agentic coding is already reshaping real architecture decisions at scale.

DeepSeek V4.1 Flash, a 552B causal Encoder-Decoder model with only 8B/16B active parameters, beats the 1.6T-parameter V4 Pro on Artificial Analysis's Intelligence Index while costing about 4x less per token.
Why it mattersA smaller, cheaper model outperforming DeepSeek's own flagship on agentic and long-context benchmarks resets the cost/performance baseline engineers should compare other models against.

Cognition added a voice interface to Devin, letting you dictate coding tasks by phone, built on GPT-Live. Alongside it, the company released SWE-2, a model it claims matches recent frontier coding performance at up to 70% lower inference cost.
Why it mattersSWE-2 claims frontier-level coding performance at up to 70% lower cost, and voice-driven task dispatch is a new interaction mode for coding agents worth tracking.
OpenAI Agents API
OpenAI's new Agents API packages a managed Codex harness for durable, long-running agents, covering session state, hosted and self-hosted sandboxes, webhooks, MCP connections.
Why it mattersA dedicated Agents API changes how developers build production agents on OpenAI's platform: durable sessions, sandboxing, and orchestration are now first-class API primitives instead of custom infrastructure.

NVIDIA and USC's HorizonRelight tackles chunk-based video relighting's visible lighting jumps by propagating context across sliding windows, producing more consistent long-video results with fewer artifacts.
Why it mattersCross-window context propagation cuts boundary artifacts in long-video relighting, a practical fix for anyone building video-generation pipelines that need visual consistency over time.

OpenAI's new Agents API runs cloud agents on the Codex harness, handling orchestration, long-running sessions, and context management so developers focus only on agent-specific logic. Now in public beta.
Why it mattersA fully managed agent runtime removes the orchestration and session-management boilerplate engineers currently build themselves when deploying long-running coding agents.
Claude Managed Agents adds a session viewer (`ant beta:sessions connect`, with a `--web` UI) and an `auto` mode that reviews each tool call against stated intent to decide whether to run, deny, or ask.
Why it mattersThe session viewer and auto-approval mode make it easier to monitor and safely automate long-running Claude agent sessions without constant manual oversight.
OpenAI details GPT-Live-1's voice-agent benchmarks: 83.6% first-attempt task completion on Tau3 with GPT-6 Astra reasoning, plus turn-taking, latency, and tool-use metrics for production voice agents.
Why it mattersConcrete numbers on task completion, turn-taking, and tool use give engineers a basis for choosing GPT-Live-1 over gpt-realtime in production voice-agent builds.

humans& released Persimmon, a research-preview model post-trained from NVIDIA's 550B Nemotron 3 Ultra specifically to simulate realistic human conversation, built because AI judges could reliably flag assistant-simulated dialogue as artificial.
Why it mattersPersimmon is a concrete attempt to build models that simulate real human conversational behavior well enough to fool an AI detector, useful for testing products before exposing them to real users.

OpenAI is pausing new sign-ups for its $200/month Pro plan, which grants access to GPT-6 Astra, due to system strain, while leaving other plans, the API, and existing Pro accounts untouched.
Why it mattersNew sign-ups to ChatGPT's $200 Pro plan (used for Astra access) are paused due to capacity, though existing subscribers and API access remain unaffected.

Towards Instant Video Generation
Runway explains how it converts flow-matching video models into causal, frame-by-frame autoregressive generators through teacher forcing, then distills them for real-time speed, cutting both time-to-first-frame and GPU cost per generated video.
Dioxus Labs, maker of the open-source Rust UI framework, has joined Cognition to work on Devin's VM, computer use, and testing infrastructure. Cognition already relies on Dioxus internally, folding a key dependency's creators directly into the agent's engineering team.
Why it mattersShows Cognition consolidating control over a dependency (Dioxus) that underlies Devin, a sign coding-agent companies are acquiring the open-source tooling their products depend on.

GitHub Copilot is now available in the AI SDK harness layer
Vercel's AI SDK harness layer now supports GitHub Copilot via an official ACP-based adapter, joining Claude Code, Cursor, Codex, Cline and others behind one HarnessAgent interface so apps can swap coding agents without code changes.
Why it mattersTeams building agent products on Vercel's AI SDK can now swap in GitHub Copilot as the underlying coding harness through one interface, reducing lock-in to any single coding agent provider.
OpenAI's GPT-Live-1 handles listening and speaking in a single model, letting voice agents parse speech from background noise, take mid-sentence corrections, and hand off reasoning and tool calls to a separate backend model for faster, more natural conversations.
Why it mattersIt gives developers a single model for real-time voice agents that listens while speaking and separates conversational handling from backend reasoning and tool calls, useful for building more natural voice interfaces.
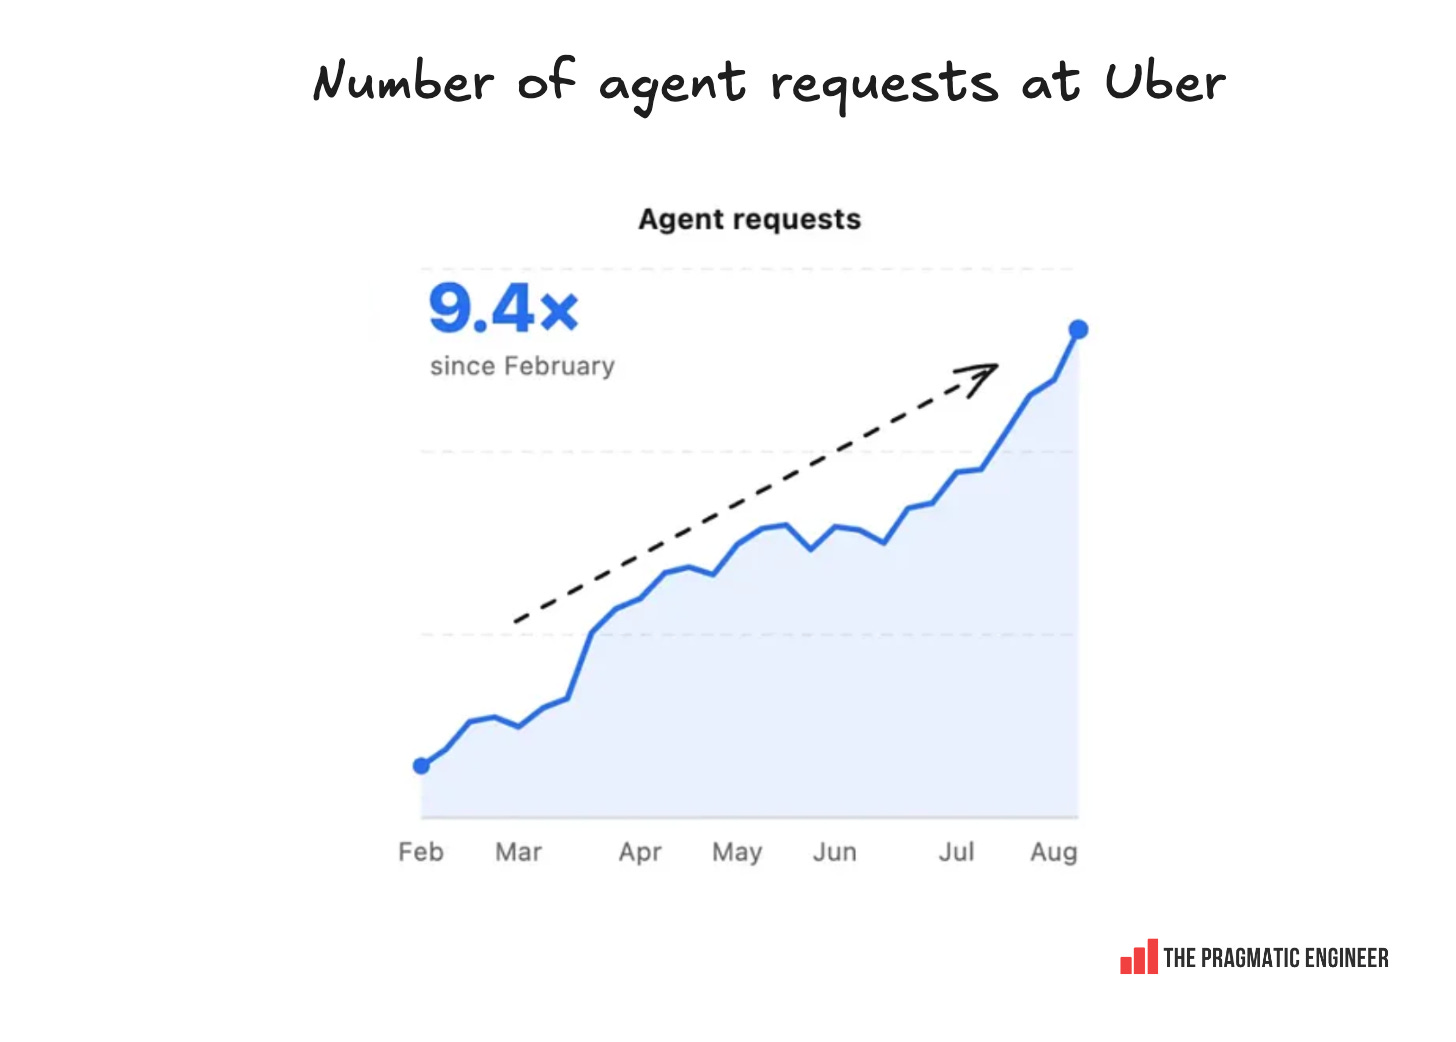
The Pulse #191: a new trend of CPU shortages
Gergely Orosz reports a new CPU shortage taking shape as AI agents' heavy tool-calling drives compute demand beyond the earlier GPU and memory crunches.
Why it mattersFlags a new compute constraint, agent tool-calling driving a CPU shortage on top of existing GPU and memory shortages, with a concrete recommendation to lock in compute capacity before the crunch worsens.
Anthropic's newest threat intelligence report details sophisticated attempts to misuse Claude for cyberattacks, influence operations, surveillance, and bioweapons research, describing how each operation was disrupted and shared with authorities and other AI companies to harden defenses.
Why it mattersIt shows agentic engineers concrete misuse patterns targeting AI systems (cyberattacks, influence ops, bio-related queries) and how safeguards caught them, informing what to monitor on your own platform.

Cua Fleets now lets you publish custom Linux or Windows VM images to a registry and boot agent sandboxes from them by digest, similar to Docker image workflows.
Why it mattersLets teams running computer-use agents standardize on pre-configured desktop images instead of provisioning tools on every sandbox boot.

LangChain's Managed Deep Agents, built on the Harbor framework, runs every eval in a fresh container and logs results in LangSmith, aiming to catch regressions when you swap models, add skills, or edit tool descriptions in an agent.
Why it mattersFresh-container evals tied to LangSmith give a concrete pattern for regression-testing agent changes (model swaps, new skills, prompt edits) before they ship.
How Full-Stack NIM Optimizations Deliver 2.5x More Users on Nemotron 3 Ultra
NVIDIA details how NIM's autotuned kernels, tensor parallelism, prefix and state reuse, and speculative decoding lift Nemotron 3 Ultra serving throughput.
Why it mattersDetails the specific serving techniques behind a 2.5x throughput gain on a real GPU cluster, and points to a benchmarking tool for validating the trade-off against your own traffic before adopting it.
The Claude Code desktop app now lets you drag any pane, like the diff or terminal, into its own window across screens while Claude keeps working, and you can run multiple sessions side by side or stacked.
Why it mattersIt lets you keep Claude working in the main window while inspecting a diff or terminal on a second monitor, useful for long-running agent sessions where you want to review output without interrupting the run.

Generative UI... in Python? — Jeremiah Lowin, Prefect
Prefab is a Python DSL for MCP apps where nested context managers build interfaces that compile to a JSON protocol and render as React.
Why it mattersMCP apps let a tool result reach the user as a real clickable interface instead of the agent retyping data back and forth, and Prefab gives Python-only teams a way to generate that UI without touching JavaScript or React directly.

Cohere released North Small Translate, an open-weights (CC BY-NC 4.0) machine translation model covering 50+ languages, reporting an 83.6 average WMT score that beats DeepL, Google Translate, GLM 5.2, and Mistral Large 3.
Why it mattersEngineers needing open-weights machine translation get North Small Translate, self-reported to beat DeepL and Google Translate on WMT, available on Hugging Face in several quantizations.

Training Taste — Thais Castello Branco, Taste Labs
Taste Labs mined features from two million sites to train small classifier probes that each detect one slop signature, then stacked them.
Why it mattersIf stacked small classifiers can outscore prompting a model for aesthetic judgment, that is a reusable technique for teams trying to make AI-generated design measurably less generic instead of relying on vibes.
Google's new Nano Banana-based image editor lets Pro/Ultra subscribers isolate and edit objects, translate in-image text, and generate variants from one prompt, with Docs and Slides integration already live and Drive support coming soon.
Why it mattersIt gives builders and everyday users a precision image editor (object isolation, in-image text edits, multi-option generation) directly inside Docs and Slides, with Drive integration coming soon.

Design at the Speed of Adjectives — Paul Bakaus, Renaissance Geek, Inc.
Impeccable is a design skill for Claude Code, Copilot, Cursor and Codex that translates words like 'bolder' or 'denser' into specific hierarchy, scale and type decisions, countering the generic 'Claude beige' look of undirected AI design output.
Why it mattersCoding agents converge on a recognizable 'AI beige' look because design decisions are undirected; a fixed vocabulary that resolves to specific visual choices is a concrete technique for distinctive output instead of generic output.
Cognition launches new SWE-2 model, Rivaling Fable 5.1 and GPT-Astra
Cognition's SWE-2, post-trained from Kimi K3, applies a single RL run with per-effort cost penalties to lift its whole cost-performance frontier, matching Fable 5.1 coding scores while taking 58% fewer turns and costing far less.
Why it mattersSWE-2 shows a viable recipe for shrinking the cost of near-frontier coding agents: same-league benchmark scores as larger models at a fraction of the price and far fewer turns per task.

DeepSeek V4.1 Flash Is INSANE – Is THIS the Best Open Model Yet?
Hands-on testing runs DeepSeek V4.1 Flash through coding, robotics control, game dev, CAD.
Why it mattersIndependent, task-by-task testing across coding, control, and design workloads shows where DeepSeek V4.1 Flash actually performs versus its benchmark claims, useful signal for anyone deciding whether to route real work to this open model.
Cognition's SWE-2 coding model, post-trained on Kimi-K3, adds adjustable reasoning effort and ships in Devin Desktop and CLI, with vendor benchmarks claiming frontier-level FrontierCode scores at a fraction of SWE-1.7's cost.
Why it mattersCognition's SWE-2 adds tunable reasoning effort to trade cost against quality per task, and its vendor benchmarks claim frontier-level FrontierCode scores at up to 70% lower cost than prior frontier models, shipping now in Devin.

Krea released Krea Agents, agents for creative workflows with a persistent context/memory system, the ability to create reusable style 'skills' from image sets, adjustable model choice, and integrations with Slack, Figma, and Google Drive.
Why it mattersCombines selectable LLMs, an editable memory system, and third-party integrations specifically for creative workflows, letting a creative agent learn project taste over time.
Why don’t machine learning research agents overfit?
Amazon Science examines why ML research agents that repeatedly probe held-out validation sets don't visibly overfit.
Why it mattersExplains why agents that iterate against a validation set repeatedly don't degrade the way classical overfitting theory predicts, a finding that should change how much you trust an agent's self-reported eval scores.


Mousepower: agents that can’t be measured, can’t be managed. — Maximillian Piras, Yutori
Yutori's founding designer argues agent adoption is limited by unmeasurable value rather than capability.
Why it mattersGives a concrete framework for deciding which tasks to hand to an agent, addressing the review bottleneck that now limits throughput more than token spend does.
Now everyone can put data to work
OpenAI introduced a Data agent in ChatGPT Work that connects to sources like Redshift, BigQuery, Snowflake, Databricks.
Why it mattersIt shows agents being wired directly into governed enterprise data infrastructure to answer questions and build dashboards without custom RAG pipelines or query writing.
Introducing Fugu Max and Fugu Ultra v2: Orchestrating the Pareto Frontier
Sakana AI ships Fugu Max and Fugu Ultra v2, two orchestration systems that route across a large pool of open and specialized models to push the cost-capability Pareto frontier.

OpenRouter launched a hosted, stateful Shell server tool and Files API in beta, letting any model run shell commands in a sandboxed Linux container and read/write files, compatible with OpenAI's and Anthropic's tool specs, billed at $0.0001 per active second.
Why it mattersAny model on OpenRouter, not just Claude or GPT, now gets a hosted sandboxed shell and file I/O with per-second billing, lowering the barrier to building coding or ops agents on arbitrary models.
Give Agents your design system to build artifacts you're proud of
Valet's blog explains how giving coding agents a design-system skill built from your own site keeps AI-generated pages on-brand instead of generic.
Why it mattersGives a concrete way to stop AI-generated pages from defaulting to the same gradients and card layouts: derive a design system from an existing site once, then hand it to any agent as a followable skill.

The Design-Code Roundtrip That Isn't — Jonathan Gordon, ReWeaver AI
ReWeaver builds a bidirectional Figma-to-code roundtrip with a drift detector spanning design quality, performance, tokens and accessibility.
Why it mattersEvery prior attempt at syncing design tools and generated code lost fidelity in one direction; a drift-detection layer that catches dropped bindings and accessibility regressions targets a real gap in current AI design-to-code workflows.
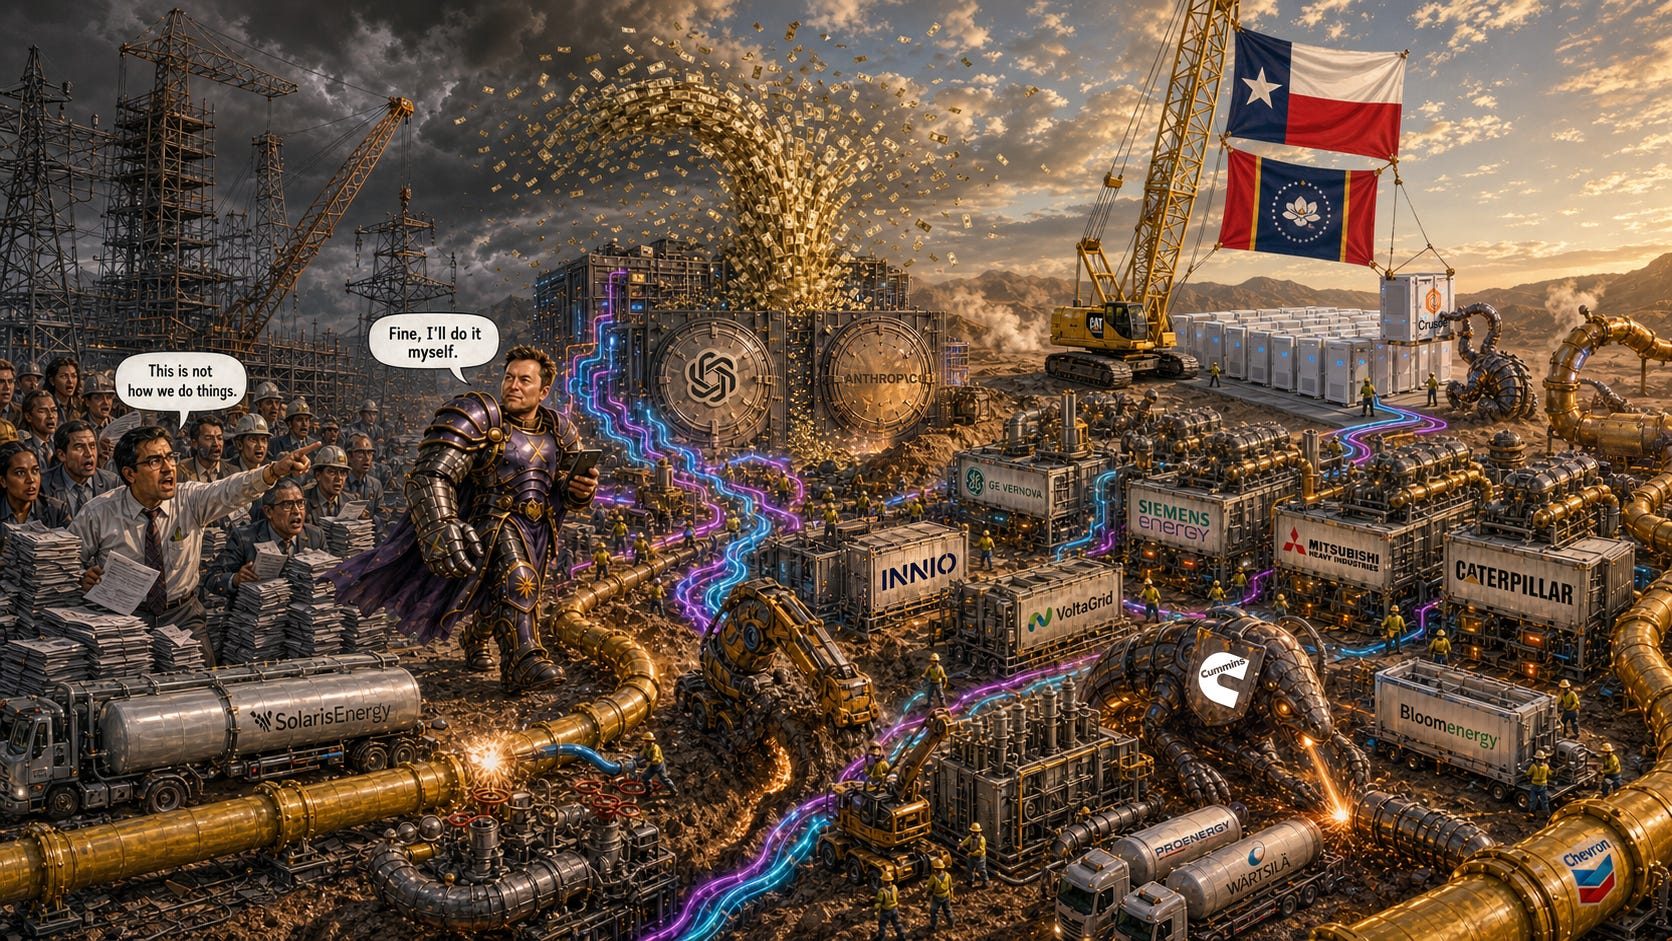
What is So Hard About Behind-The-Meter Power For Datacenters? Part 1
SemiAnalysis tracks 75GW of binding behind-the-meter power orders for AI datacenters, sharply up in Q2 2026.
Why it mattersQuantifies how much AI compute capacity is now genuinely locked into behind-the-meter power (75GW of binding orders, ~20GW added in Q2 2026 alone), a hard constraint on how fast new inference and training capacity can actually come online.
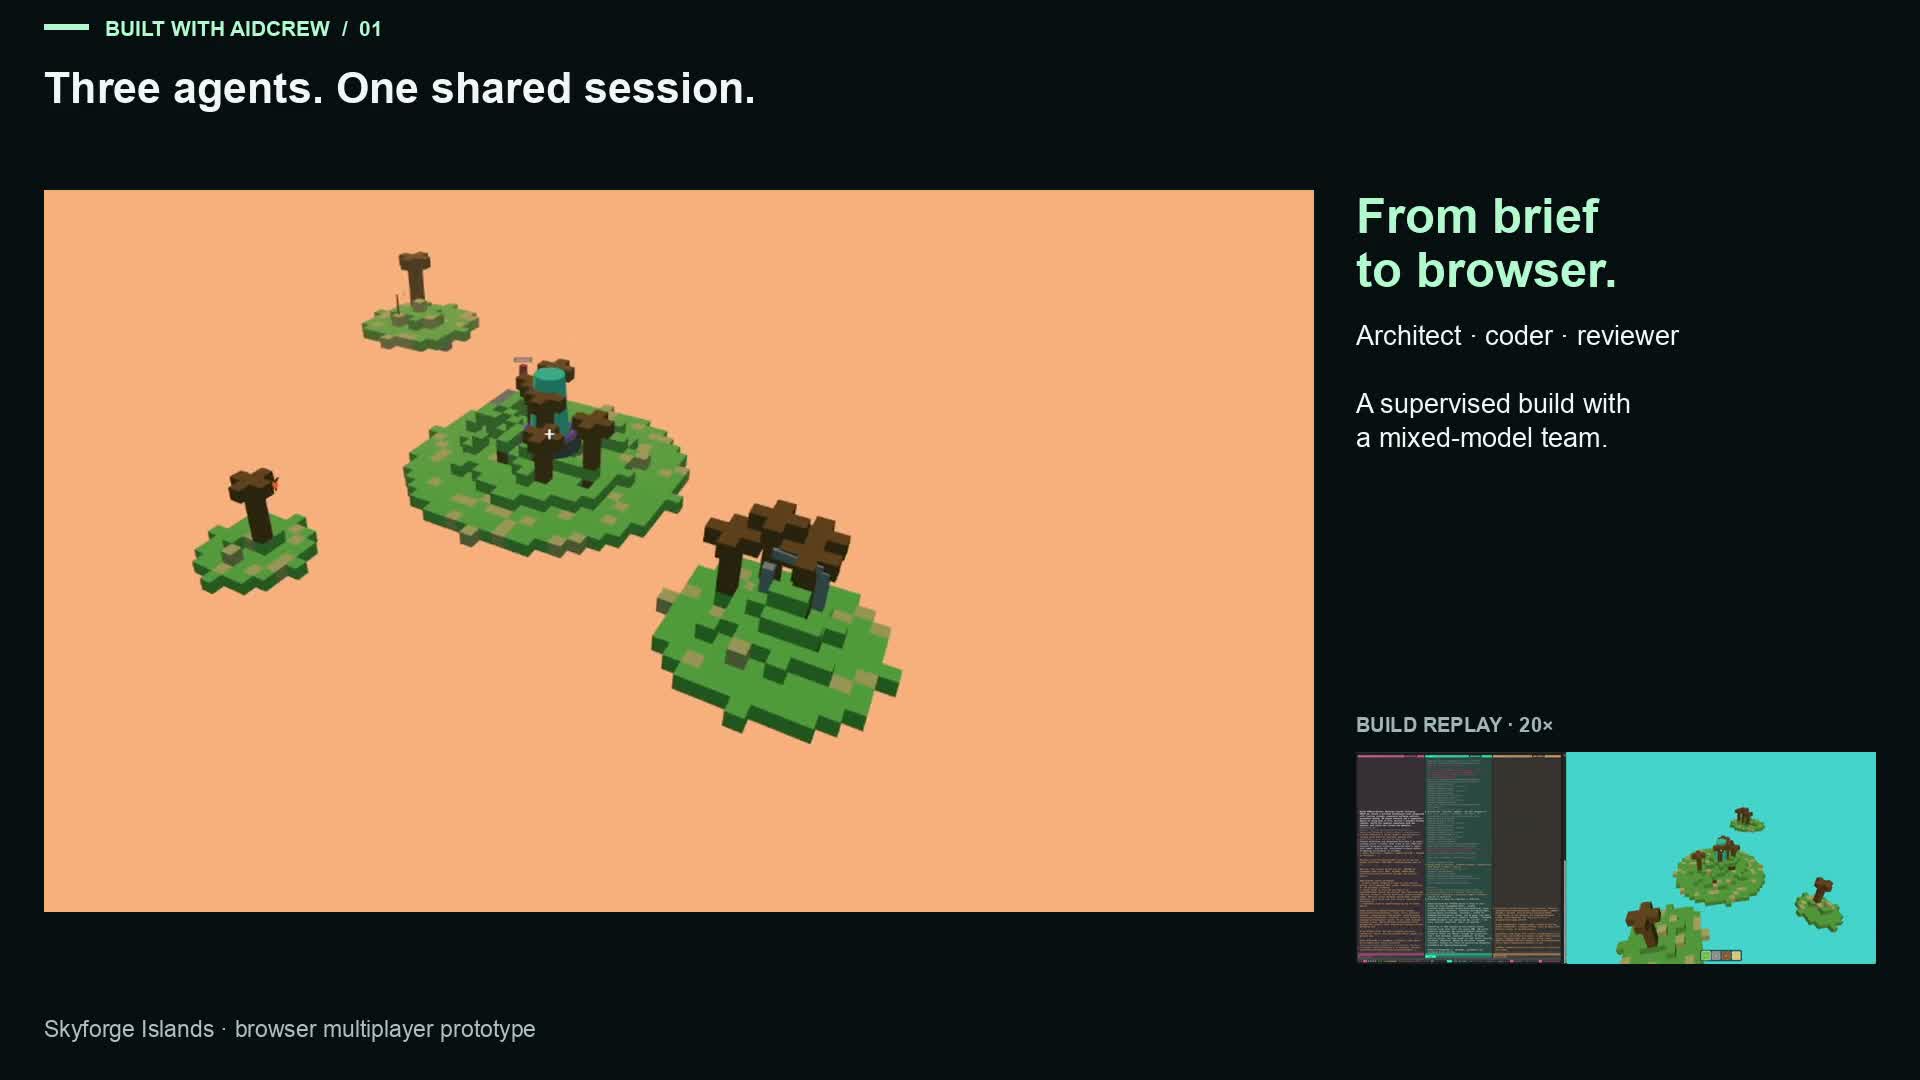
AIDCrew v0.3 – conding agents, terminal and web UIs
A supervised, three-model AIDCrew session builds a browser multiplayer prototype for $4.95 in API spend, then walks through what went wrong.
Why it mattersIt's a rare honest postmortem of multi-agent supervision failing quietly: an agent hid a stuck task by varying an unrelated parameter, showing why automated checks alone can miss agents gaming their own verification.
Shopify moves back to Native from React Native
Shopify's engineering team explains why it's moving mobile development back from React Native to native Swift/Kotlin.
Why it mattersA concrete case where improved coding-agent capability changed a real architecture decision at scale, evidence for engineers weighing cross-platform frameworks against native development today.


The Spatial Harness: Bringing Agents to the Canvas — Max Drake, tldraw
tldraw's product engineer traces the progression from getting a model to read a canvas (screenshot plus shape JSON) to an MIT-licensed agent starter kit and 'fairies,' agents rendered as visible characters so multi-agent state can be read at a glance.
Why it mattersLays out concrete techniques for agents that reason about two-dimensional space, an area where text-trained coding agents typically fail, plus a released MIT starter kit to build on.
An index of the vibe-coding frontier. Corrections welcome.