Intel
Page 80
The Economics of the AI Super Cycle: OpenAI's Compute Strategy (with Sachin Katti)
A Stanford class interview with Sachin Katti, who leads industrial compute at OpenAI and previously served as Intel's CTO, on how OpenAI plans and builds compute at gigawatt scale.
Why it mattersOpenAI's compute chief explains the roadmap to 30GW of capacity and why inference workloads will dominate future compute demand.

Ali Ghodsi on AGI, Enterprise AI, and Whether Software Is Dead
In this talk/interview, Databricks CEO Ali Ghodsi argues that AGI already exists by decades-old research definitions but remains useless inside companies because AI agents lack the tacit organizational context that veteran employees carry in their heads.
Why it mattersGhodsi argues that even if AGI meets old technical definitions, it remains blocked from real enterprise value by missing tacit organizational context that human employees hold.

Chase Lockmiller (Crusoe) on the AI Data Center Economy
A fireside talk with Crusoe founder and CEO Chase Lockmiller explaining how AI infrastructure is built.
Why it mattersCrusoe's Abilene campus shows energy availability, not GPU supply, is now the binding constraint on scaling AI compute, and negative power prices in West Texas are actively shaping where hyperscale AI infrastructure gets built.

Brad Gerstner and Sunny Madra on the Economics of AI Inference
A fireside chat transcript in which Altimeter Capital's Brad Gerstner and Groq's Sunny Madra discuss why AI inference, unlike traditional software, has significant marginal compute costs, tracing Groq's origins, its bet on cloud-hosted inference chips, and the shift toward reasoning models that consume vastly more tokens.
Why it mattersExplains why reasoning models' heavy token consumption changes inference cost structure, and details the prefill/decode disaggregation strategy Groq used to improve inference efficiency at scale.

GitHub made Balanced depth generally available for Copilot code review alongside the existing Lite mode, with the default settable at the organization or repository level and overridable when requesting a review on a single pull request.
Why it mattersTeams running Copilot code review can now put deeper analysis on risky pull requests and keep lightweight reviews on routine ones, set as a default or chosen per request.
OpenAI’s Head of Design: This is the best time in history to be a designer | Ian Silber

GLM 5.3 Is HERE – Is THIS the BEST Open Model Yet?
A hands-on test of GLM 5.3 across browser workflows, C++ game development, 3D CAD modelling, frontend design and FPS generation, asking whether it earns the title of best open model yet.
Why it mattersGives practitioners a task-by-task read on whether GLM 5.3 holds up as a coding model against the closed frontier, which is the decision anyone weighing an open-weight backend actually has to make.

An argument that a token is not a standard unit: identical text costs different token counts on different tokenizers, so a cheaper per-token price can still produce a larger bill. One sample measured 766 tokens on GPT-5.6 Sol against roughly 1,170 for Claude Opus 5. Vendor-authored, so verify on you
Why it mattersComparing list price per token across models with different tokenizers understates the real bill. Tokenize your own representative text before choosing on price, then measure cost per completed task.

Hermes Agent Desktop gains Bot Mode: instead of ephemeral sessions, you define persistent bots with jobs, descriptions and avatars that can hand work to each other. Nous opened a public beta window for it.
Why it mattersHermes Desktop moves from one-session-per-chat to persistent agent profiles with assigned jobs that can talk to each other — a local multi-agent setup available to try in the public beta.
Auto-research with Codex: a 232x faster QR kernel and the loop behind it
A postmortem of using Codex as an autonomous kernel-optimization loop in a GPU Mode contest.
Why it mattersShows how to turn a verifiable benchmark into an agent hill-climbing loop and how to escape local maxima by keeping a beam of 3-5 candidates, using an advisor model, and logging tried ideas.

Claude's text watermark changes where sampling randomness comes from rather than which words get picked, which is why output quality is unaffected. Anthropic is rolling it out for EU AI Act compliance; an interactive explainer walks the mechanism step by step.
Why it mattersWatermarking is landing in Claude's text output under the EU AI Act, and it works by shifting the randomness source rather than the words — quality is unchanged, but generated text becomes detectable.
Go from an empty repo to a live GitHub Pages site on a custom domain, secured wi
GitHub shows Copilot CLI plus a community Namecheap skill going from an empty repo to a live GitHub Pages site on a custom domain with HTTPS in about 14 minutes.
Why it mattersShows the skill mechanism in a coding CLI reaching past code into registrar and DNS setup, which is the kind of end-to-end delegation builders are trying to scope right now.
React for Agents: Astro Creator Brings Hooks to his Meta-Harness, Flue
Fred Schott's Flue reaches its first stable release built on React-style Agent Hooks, where an agent is a JavaScript function that re-renders before every model call and can manage its own state and attach capabilities mid-run.
Why it mattersAgent Hooks are a concrete answer to how agent state and capabilities get composed at runtime, from the person who built Astro. Engineers picking a harness now have a second serious design to compare against Vercel's eve.
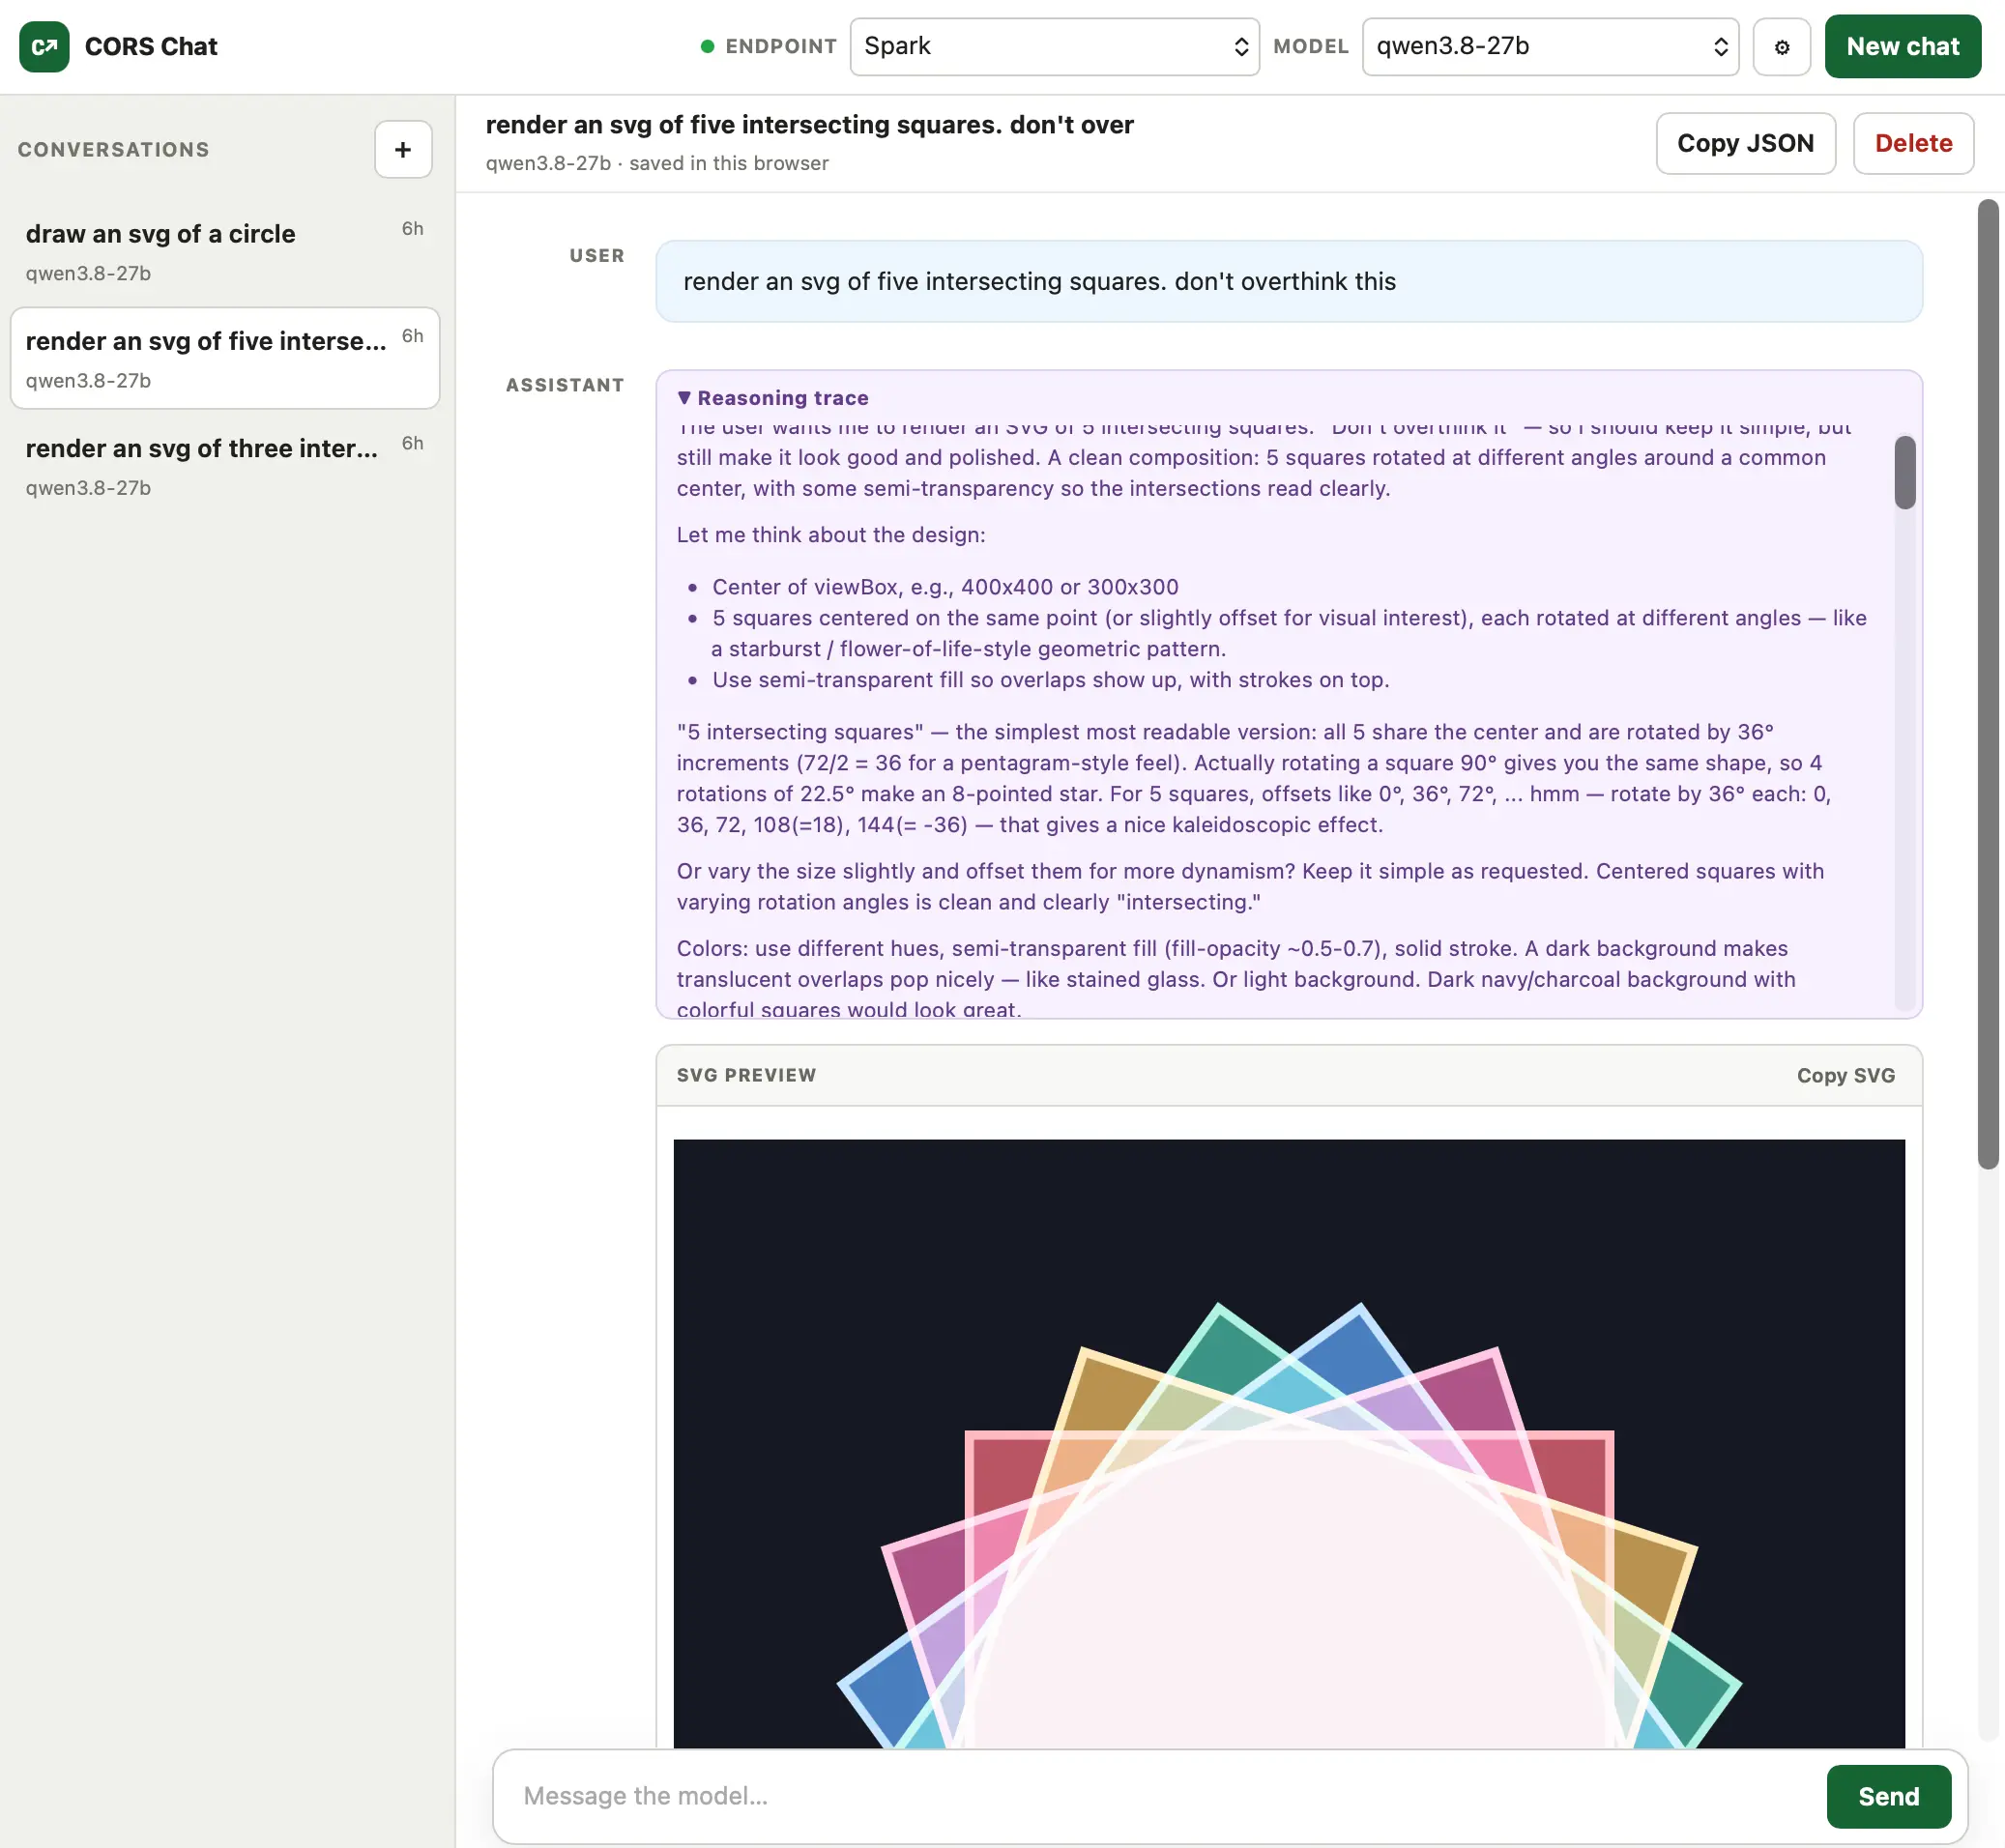
CORS Chat
Simon Willison's browser-based chat client for any OpenAI Responses-compatible endpoint that sends CORS headers, built to exercise local models in LM Studio and OpenRouter.
Why it mattersA zero-install way to exercise a Responses-compatible endpoint, including a locally served model, which removes the usual scratch-script step when validating a new provider or a local runtime.
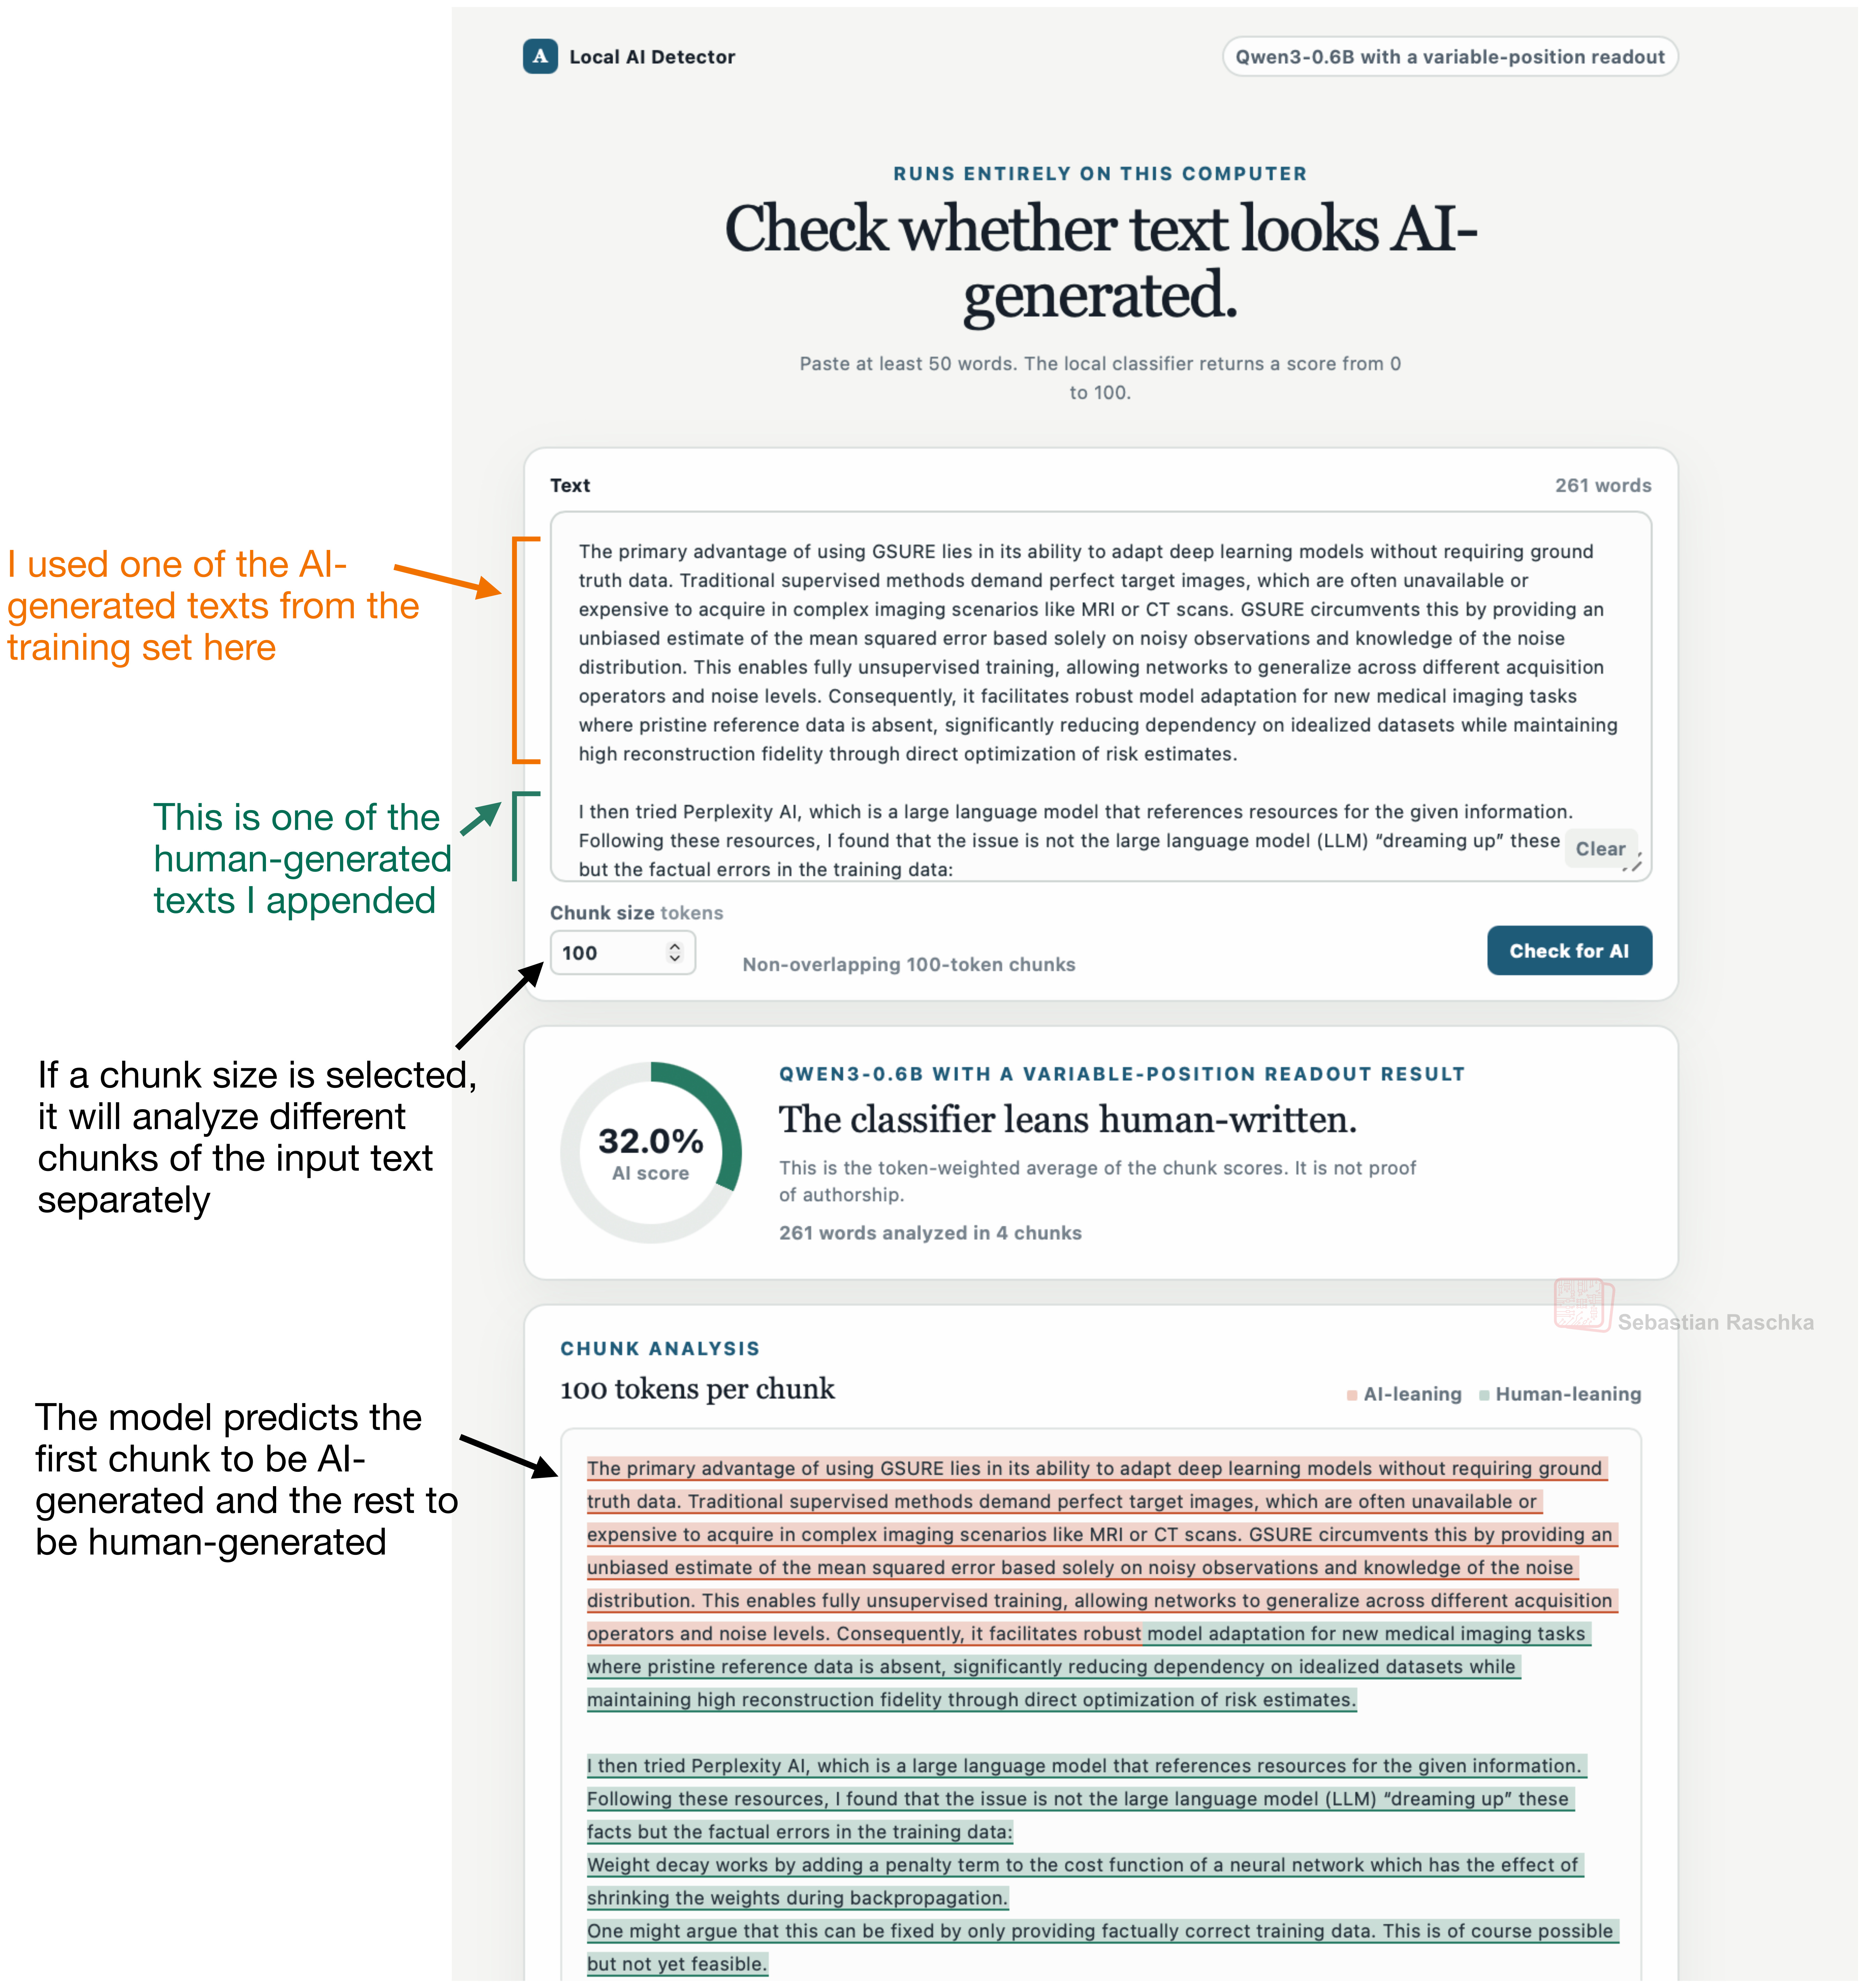
Building an AI Text Detector From Scratch
Sebastian Raschka builds a small AI-text detector from scratch, then turns it into a verifier used to train a small language model to write text that evades detection, as a study of where such detectors break down.
Why it mattersShows how to build a classifier-as-verifier and train an SLM against it, a reusable pattern for anyone wiring reward or filter signals into small-model training.

Voice agents with Realtime Video — Sidney Primas, LemonSlice
A production account of real-time video avatars.
Why it mattersAnyone building real-time multimodal agents gets the specific failure mode of long-running generated video and the fixes that keep an eight-hour session coherent.
Diagnostic Foundation for Evaluating LLMs' Research Integrity as Co-Scientists
IntegrityBench tests whether models uphold research integrity under institutional pressure across 36 paired tasks.
Why it mattersAnyone deploying models as autonomous research or review agents now has a measured failure rate under pressure, and evidence that scaling up the model does not fix it.
Research Assistant: AstraZeneca's Agentic System for R&D
AstraZeneca describes Research Assistant, an internal LLM system answering biomedical questions across literature, knowledge graphs, chemistry, clinical trials and internal experimental data.
Why it mattersPublished architecture and deployment lessons from a real enterprise agent system give builders a reference design for grounding, provenance, and mode selection.
Position: The Alignment Community is Unintentionally Building a Censor's Toolkit
An ICML oral argues that alignment methods are dual-use.
Why it mattersThe same machinery that suppresses harmful output is general-purpose output control — worth understanding if you ship alignment or moderation layers that a downstream operator could repurpose.
Don't Want Your LLM to Recommend Nuclear Strike? Try Asking It in Japanese
Nine models are asked in different languages whether a nuclear-armed state should strike a defenceless one.
Why it mattersSafety behavior measured only in English does not transfer, and reasoning-language is an uncontrolled variable in any multilingual agent deployment or eval suite.
Agreement Is Not Alignment: Divergent Moral Grounds in Human and LLM Ethical Judgments
Across frontier and open models on a 500-item ETHICS-derived set, final-label agreement with human annotators runs high while the stated justifications diverge.
Why it mattersHigh label agreement with human annotators can hide divergent underlying reasoning — if your eval only scores final answers, it is measuring less alignment than you think.
Dual-Flow Transformers: Decoupling the Primary Prefill Path from Additional Decode Computation
A transformer design that splits inference in two.
Why it mattersInference cost now dominates training cost for served models, and this decouples the two phases so added capability does not tax both.

Qwen3.8-27B is now packaged for LM Studio and needs roughly 17GB to run locally, putting a fresh open-weights release on consumer hardware without an API bill. Practitioners in the replies report multi-hundred-token/s prefill and long-context runs on Apple silicon.
Why it mattersQwen3.8-27B runs locally in about 17GB and is already packaged in LM Studio, putting a current-generation open-weights model within reach of a single well-specced laptop.
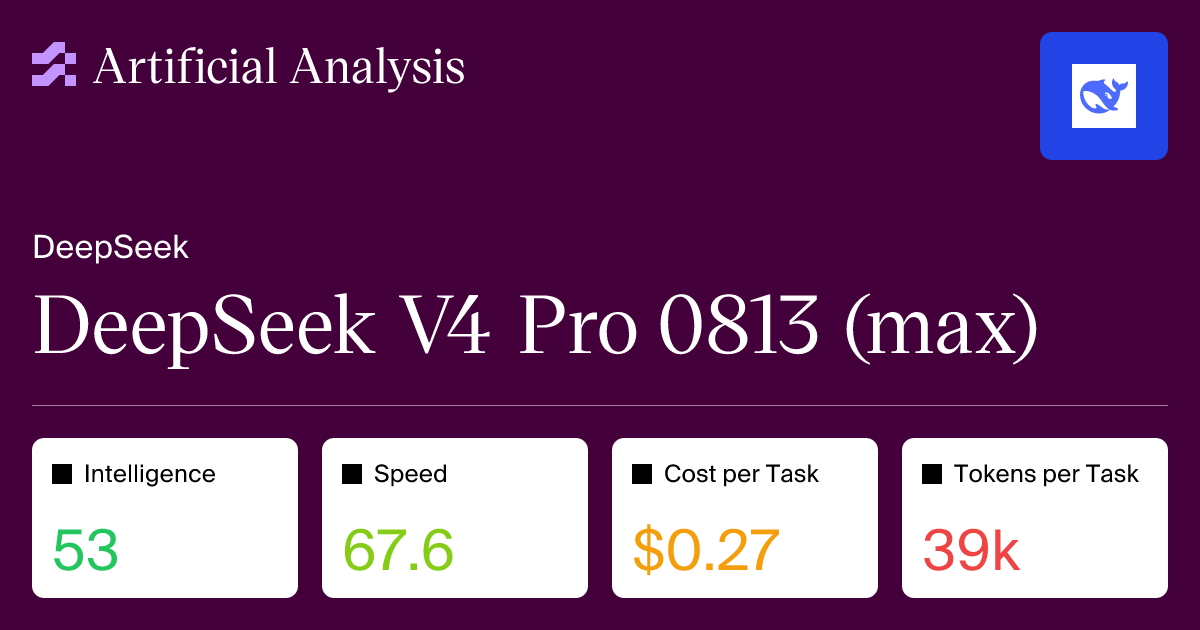
See Artificial Analysis for further details and benchmarks:
Artificial Analysis's evaluation of DeepSeek V4 Pro 0813.
Why it mattersDeepSeek V4 Pro 0813 lands near the top of the intelligence index but at 3.6x the prior price, scoring only a point above the far cheaper V4 Flash — the open-weights price/quality choice has shifted.

Artificial Analysis scores DeepSeek V4 Pro 0813 at 53 on its Intelligence Index, eight points above April's version but with a 3.6x price rise, leaving it barely ahead of the cheaper V4 Flash and still behind Kimi K3 among open-weights models.
Why it mattersTeams building on DeepSeek's first-party API face a 3.6x price change within a day, and the intelligence gain over the cheaper Flash model is a single point. The cost-per-task math changes which model is the rational default.

Hacktron's automated review found a high-severity NoSQL injection in Novu's codebase by tracing an unvalidated ID through an ingest controller, a type cast, and a sink service across three files.
Why it mattersHacktron's automated review caught a NoSQL injection in Novu by tracing an unvalidated event ID across three files, and fixed roughly half of flagged issues within 30 days with an 83% actionable rate.

SemiAnalysis lays out the cost case pulling hyperscalers to India: roughly $5M per MW of datacenter capex and power often under $0.10/kWh, cheap enough to put the country near 10GW by 2030 and among the four largest datacenter markets, with Microsoft alone committing $17.5B.
Why it mattersCompute capacity is migrating toward the cheapest power and capex, and India's sub-$0.10/kWh economics put it on track for roughly 10GW by 2030 — a factor in where inference gets served and what it costs.
Did you know Hermes Desktop can run against a Hermes Cloud agent? Point Hermes D
Nous Research details how Hermes Desktop connects to a Hermes Cloud gateway.
Why it mattersHermes agents can now run as always-on cloud workers reachable from Telegram, Discord, Slack, or CLI, with memory that persists across devices — relevant if you are deciding where long-running agent state should live.

Qwen3.8 27B Is INSANE – This Is the BEST Local AI Model Yet!
A hands-on test of Qwen3.8 27B running locally, across browser workflows, C++ game creation, FPS development, 3D CAD modelling, multimodal coding and cinematic game generation.
Why it mattersTask-level results on a 27B model running locally give a practical read on where local inference is now good enough for coding work and where it still falls short.
Don't classify. Hallucinate!
Doug Turnbull's trick for tagging against a large vocabulary.
Why it mattersIt turns an oversized label set from a context problem into an embedding lookup, which is directly reusable by anyone classifying against a taxonomy too large to fit in a prompt.
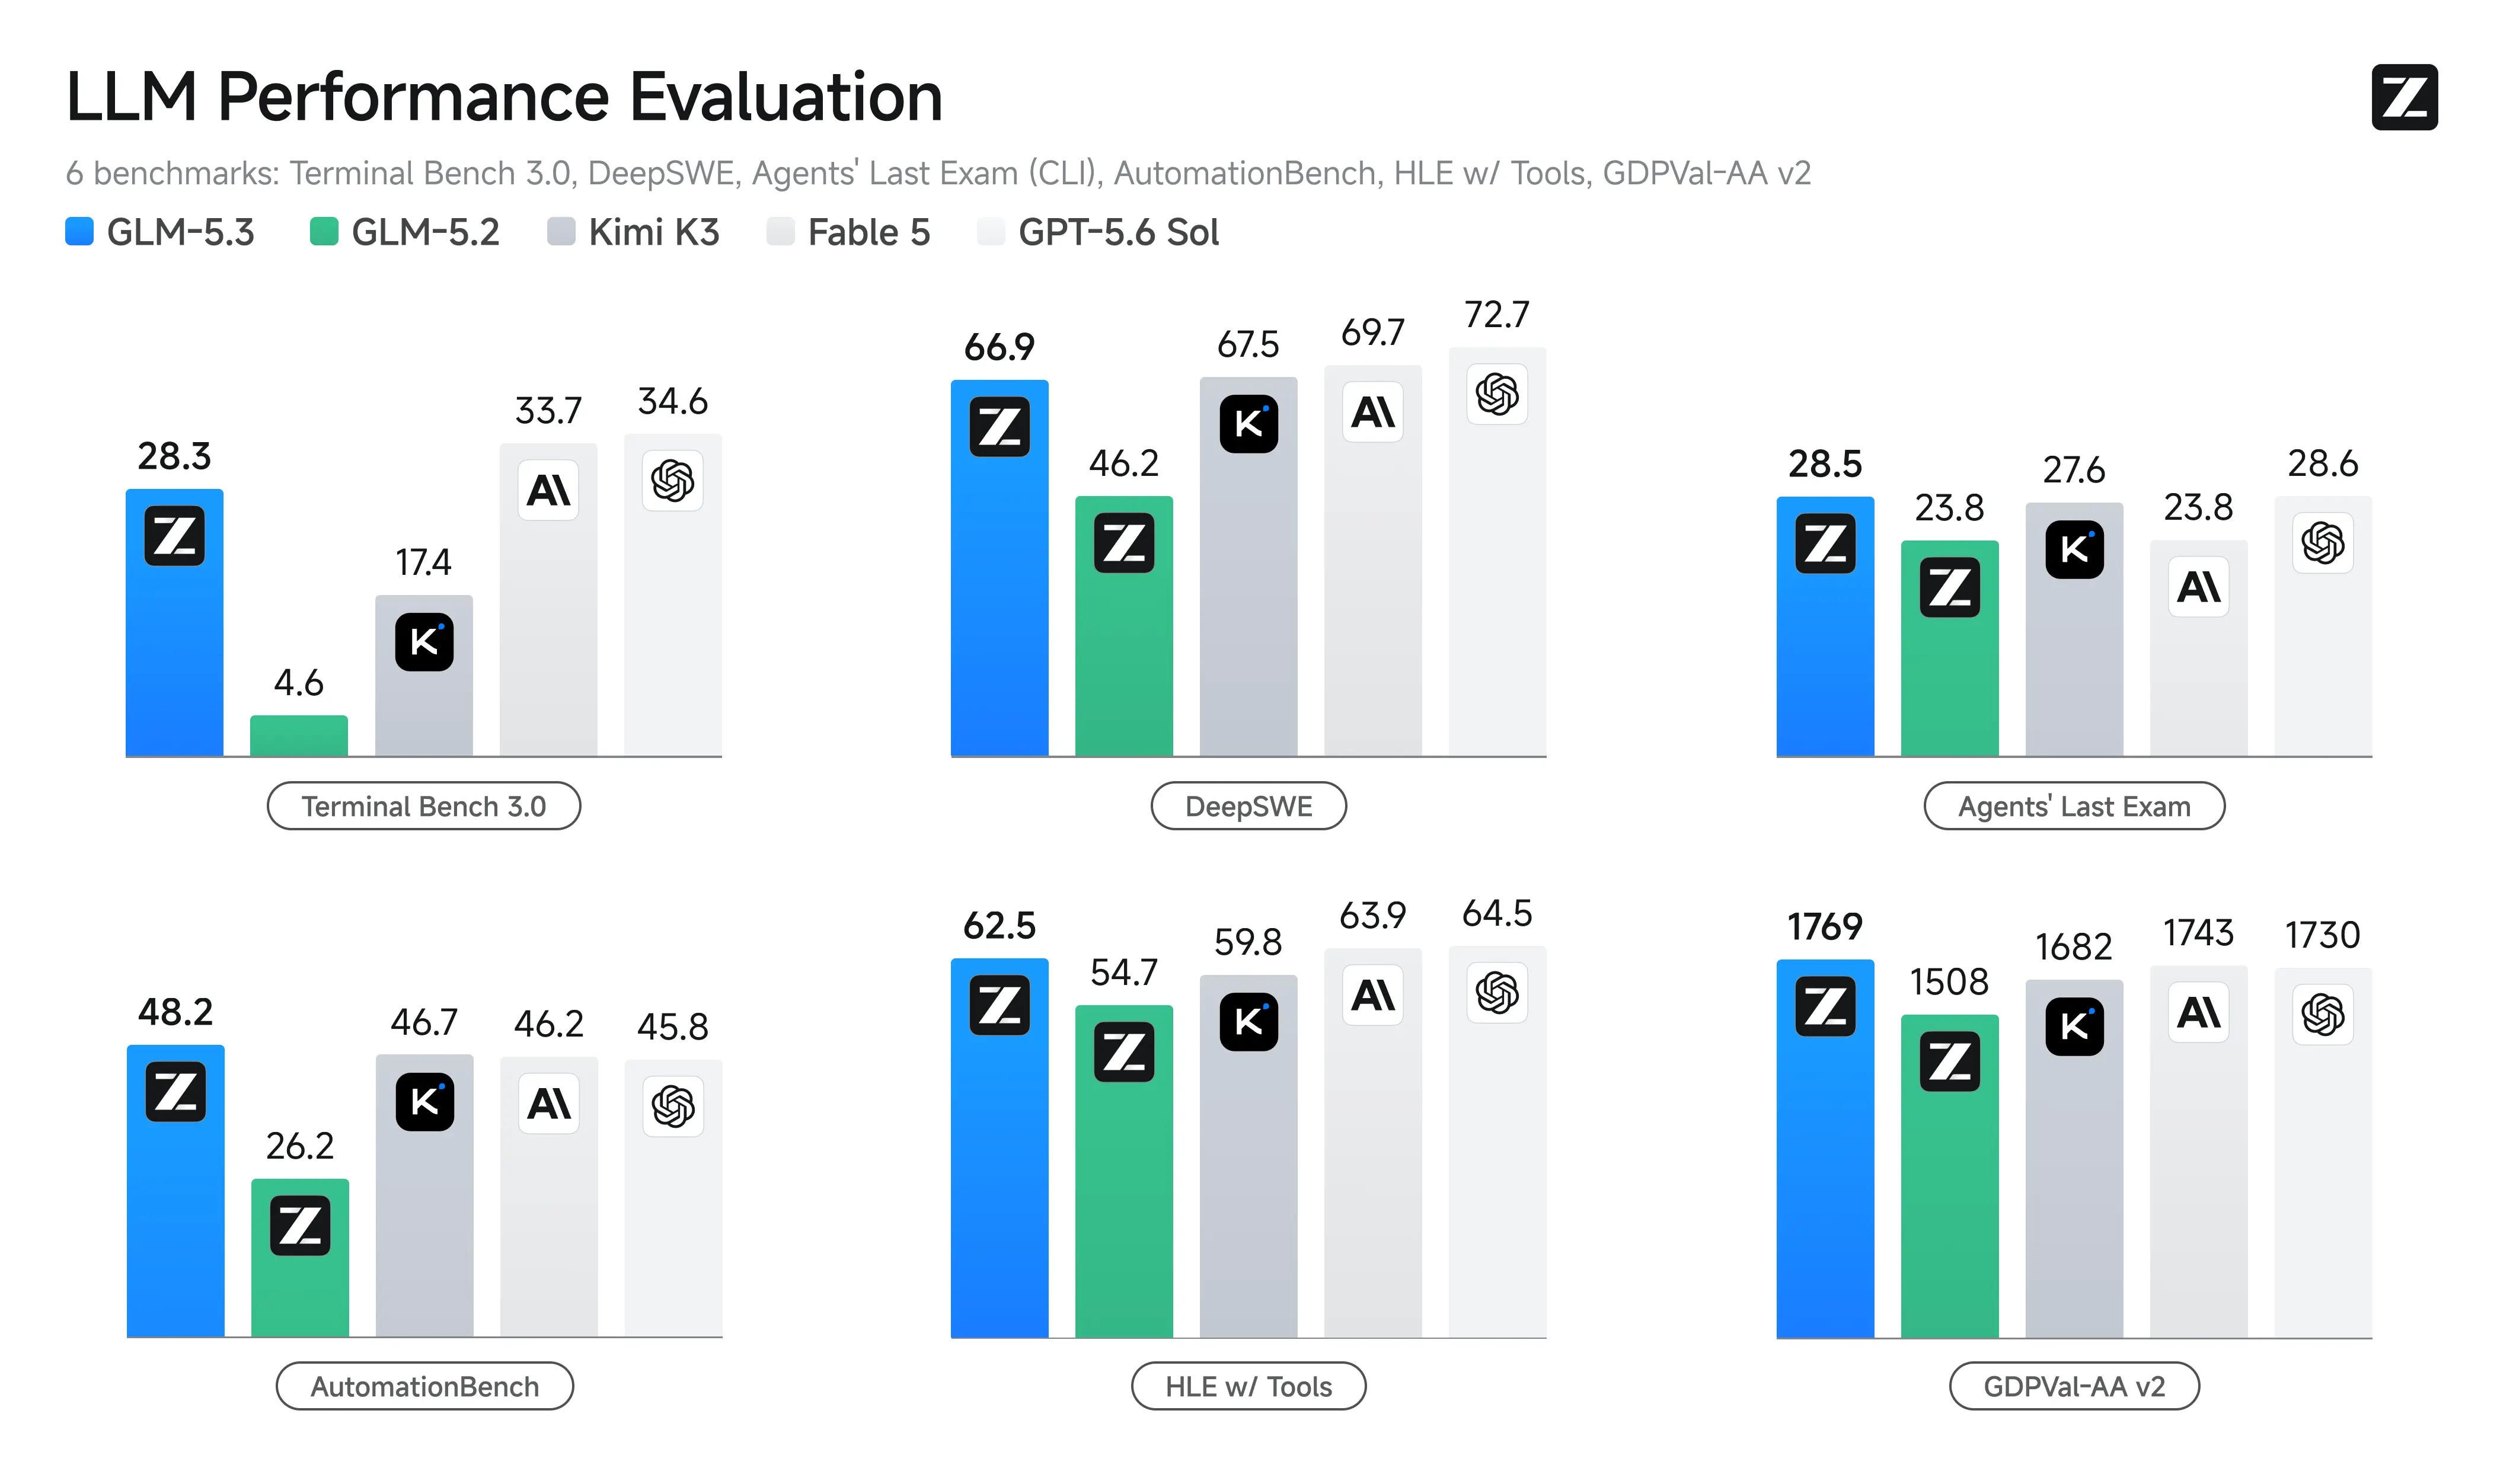
GLM-5.3: How Chinese labs keep stride with the frontier
Nathan Lambert on Z.ai's GLM-5.3.
Why it mattersA frontier-level agentic coding score reached purely through post-training on an existing base, at a third of a competitor's parameter count, resets what teams should assume about the cost of catching up.
Hermes adds /loop, which re-runs a prompt on an interval in the same session; leave the interval off and it paces itself, checking often at first and backing off while nothing changes.
Why it mattersRecurring self-paced agent runs are a scheduling primitive most harnesses lack, so builders comparing agent runtimes now have a concrete reference implementation of interval versus adaptive polling.
https://t.co/w4CBckqLpR
Hermes documents recurring in-session loops.
Why it mattersA concrete pattern for in-session recurring agent turns: back off while output is unchanged, snap back to the floor when it changes, and use cron instead when work must survive the terminal.
SemiAnalysis on GLM-5.3 beating every American open model with gains that came entirely from post-training on the same base as GLM-5.2, and what that says about the Nemotron committee path.
Why it mattersIt puts a concrete stake in the open-weights comparison: if post-training alone produced the jump, the gap between American and Chinese open models is a process gap rather than a compute gap.
We’ve written an FAQ to answer some of the questions we've received about waterm
Anthropic's FAQ on watermarking Claude's text.
Why it mattersAnyone shipping model output into their own product now knows what watermarking does and does not change about that text, including that it costs no extra tokens and carries no per-user attribution.

A 17-minute tour of OpenWiki, LangChain's open-source self-maintaining wiki: how it works, why documentation built for agents looks nothing like documentation for humans, and the lessons from building it.
Why it mattersAgent-readable documentation is becoming a design surface of its own, and this gives builders a working open source reference for how those docs should be structured and kept current.
To configure auto mode for your environment, run /auto-mode-setup. Claude looks
Claude Code's /auto-mode-setup scans your repo and proposes trusted repositories and domains for review, sharpening the auto-mode classifier's line on what is safe to run in your environment.
Why it mattersPermission configuration is the main safety lever on an autonomous coding agent, and this documents exactly how the trusted-surface list is built and reviewed.

Auto mode rolls out as Claude Code's default for Pro, Max and Team. Existing default-mode settings are respected, and modes still switch via Shift+Tab or a settings pin.
Why it mattersA shift in the default permission mode changes what a coding agent will do without asking, so anyone running Claude Code in a shared or automated setting needs to check their configuration.
WRITER Makes Agentic AI Economically Sustainable at Enterprise Scale With Palmyra X6 Release and Major Harness Upgrades
WRITER ships Palmyra X6 plus harness upgrades built around token economics rather than benchmarks.
Why it mattersAgent workflows push cost per task orders of magnitude above chat. This release pairs a cheaper flagship model with harness changes and spend controls aimed at that gap, reported as 52% lower cost at 48% higher speed.

OpenRouter's Ori CLI now launches xAI's Grok Build in custom-endpoint mode with a run-scoped OpenRouter key. No browser login, Grok config untouched, model list drawn from your OpenRouter catalog, and xAI telemetry, error reporting and trace upload disabled.
Why it mattersYou can run Grok Build against any model in your OpenRouter catalog, including private endpoints, with one key and no xAI login. Telemetry and trace upload stay off for the run.
OpenRouter launched Ori DeepSeek Harness, a one-command setup that connects DeepSeek Harness to the full OpenRouter catalog. It installs the harness if missing, stores the key in the credential store, refreshes models at boot, and adds /fast and /zdr session controls.
Why it mattersIf you run DeepSeek Harness, you can point it at any OpenRouter model without hand-editing config, and restrict sessions to zero-retention providers with /zdr. The catalog refreshes on each boot, so new models appear automatically.
As part of our Responsible Scaling Policy, we publish regular Risk Reports. Thes
Anthropic has published the second of its recurring Responsible Scaling Policy Risk Reports, its disclosure of assessed risks across its systems and its readiness to mitigate them.
Why it mattersAnthropic's periodic RSP risk reports are the primary public record of how the lab assesses its models' dangerous-capability thresholds and what safeguards gate them.
Ori now launches Prime Intellect's Agent on OpenRouter with one command, injecting the API key per run through an extension instead of editing auth.json or models.json, and stripping stray Anthropic and OpenAI keys so all requests route through OpenRouter.
Why it mattersStray provider keys in the environment can silently bypass your routing. Ori Prime strips them and injects the OpenRouter key per run without touching auth.json or models.json, so existing agent setups stay intact.
Qwen3.8-27B lands on Ollama, pitched as delivering consistently across whatever harness you run it in.
Why it mattersA 27B frontier-adjacent model landing on Ollama puts it within reach of a single workstation, which changes the local-inference options for anyone building agents that cannot call a hosted API.
Learn how to turn one giant AI-generated pull request into a clean, reviewable s
GitHub on turning one giant AI-generated pull request into a clean, reviewable stack of changes, and keeping every layer in sync as review feedback lands.
Why it mattersReview throughput is the bottleneck once coding agents can produce thousand-line diffs, and stacking gives teams a repeatable way to keep each layer small enough to actually verify.
GitHub's prescription for the giant agent-authored pull request: break it into a stack of ordered PRs, one concern per layer, with CI validating each layer against the stack's base. The gh stack CLI creates, submits, rebases and syncs the stack; reviewers read top-down and validate bottom-up.
Why it mattersA concrete review workflow for AI-generated changes: layer the work into ordered PRs, run CI per layer against the stack base, read top-down and review bottom-up instead of facing one 1,700-line diff.
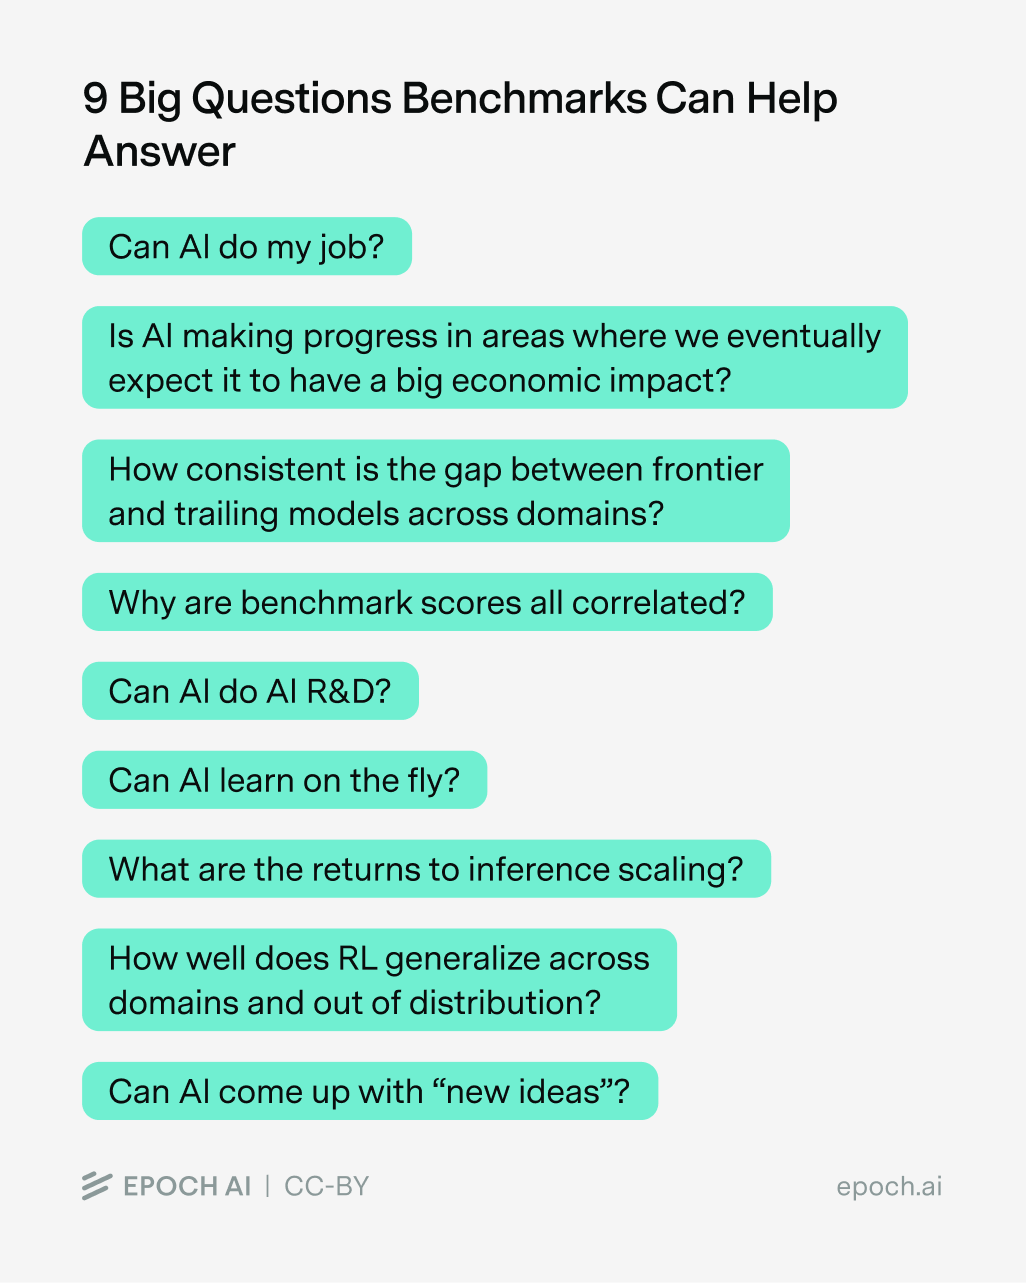
9 Big questions benchmarks can help answer
An Epoch researcher lists nine questions governing AI's impact, from narrow tasks versus messy jobs to learning from experience, and maps benchmark efforts to each.
Why it mattersNames which unresolved capability questions benchmarks should answer, helping engineers judge which evaluation results actually predict real-world agent usefulness.

How Web Data Infrastructure Powers the Next Generation of AI — Patricija Žemaitytė, Oxylabs
Oxylabs on rebuilding a search API from a four-second baseline to 550 milliseconds, and why something that works in development, something that passes tests.
Why it mattersThe load-testing observation, that instrumentation at high request volume distorts the measurement it is taking, is a failure mode teams hit when scaling any high-throughput data pipeline for AI.

The Rise of CaaS: Context-as-a-Service for Agentic AI — Omer Primor, Bright Data
Bright Data's Omer Primor puts the crossover at roughly 15,000 queries, past which building your own pipeline beats renting context.
Why it mattersIt gives a concrete break-even figure for the buy-versus-build decision on agent context data, which is otherwise argued on vibes.
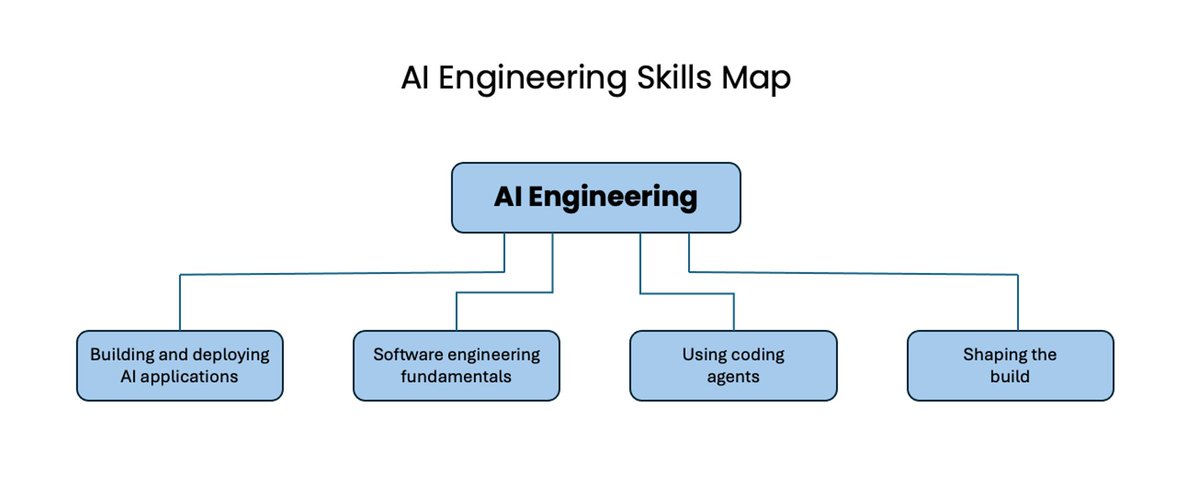
Four skills that define AI engineering, drawn from 10,000 job postings
Synthesized from job postings, expert interviews and surveys: four skills defining AI engineering.
Why it mattersA learning and hiring frame grounded in labor-market data, with "shaping the build" identified as the skill that shifts most as agents get better at delivering to a spec.
An index of the vibe-coding frontier. Corrections welcome.