Intel
Page 06
anthropic-sdk-python v2.9.0
Anthropic's Python SDK 2.9.0 adds RBAC and Bundle API features and tightens the agent toolset.
Why it mattersThe agent toolset grep no longer runs an rg from relative or empty PATH entries, closing a code-execution vector, and file tool path confinement is stricter on Windows. Upgrade if you run the toolset.
anthropic-sdk-typescript sdk-v1.9.0
Anthropic's TypeScript SDK 1.9.0 adds RBAC role endpoint fields and Update Bundle, and hardens agent tools.
Why it mattersStreamed tool input that is not valid JSON now fails instead of being silently repaired, and the agent file tools confine paths more strictly. Both can change behavior in agents built on this SDK.
Post-Training NVIDIA Nemotron to Increase Accuracy in Your Scientific Domain
NVIDIA walks through post-training Nemotron 3.5 Super VL for a scientific domain.
Why it mattersShows a reproducible path from experimental data to a custom RL environment and post-trained model. Practitioners get measured SFT and RL gains and an optional teacher-distillation warm start to adapt a model to a niche domain.
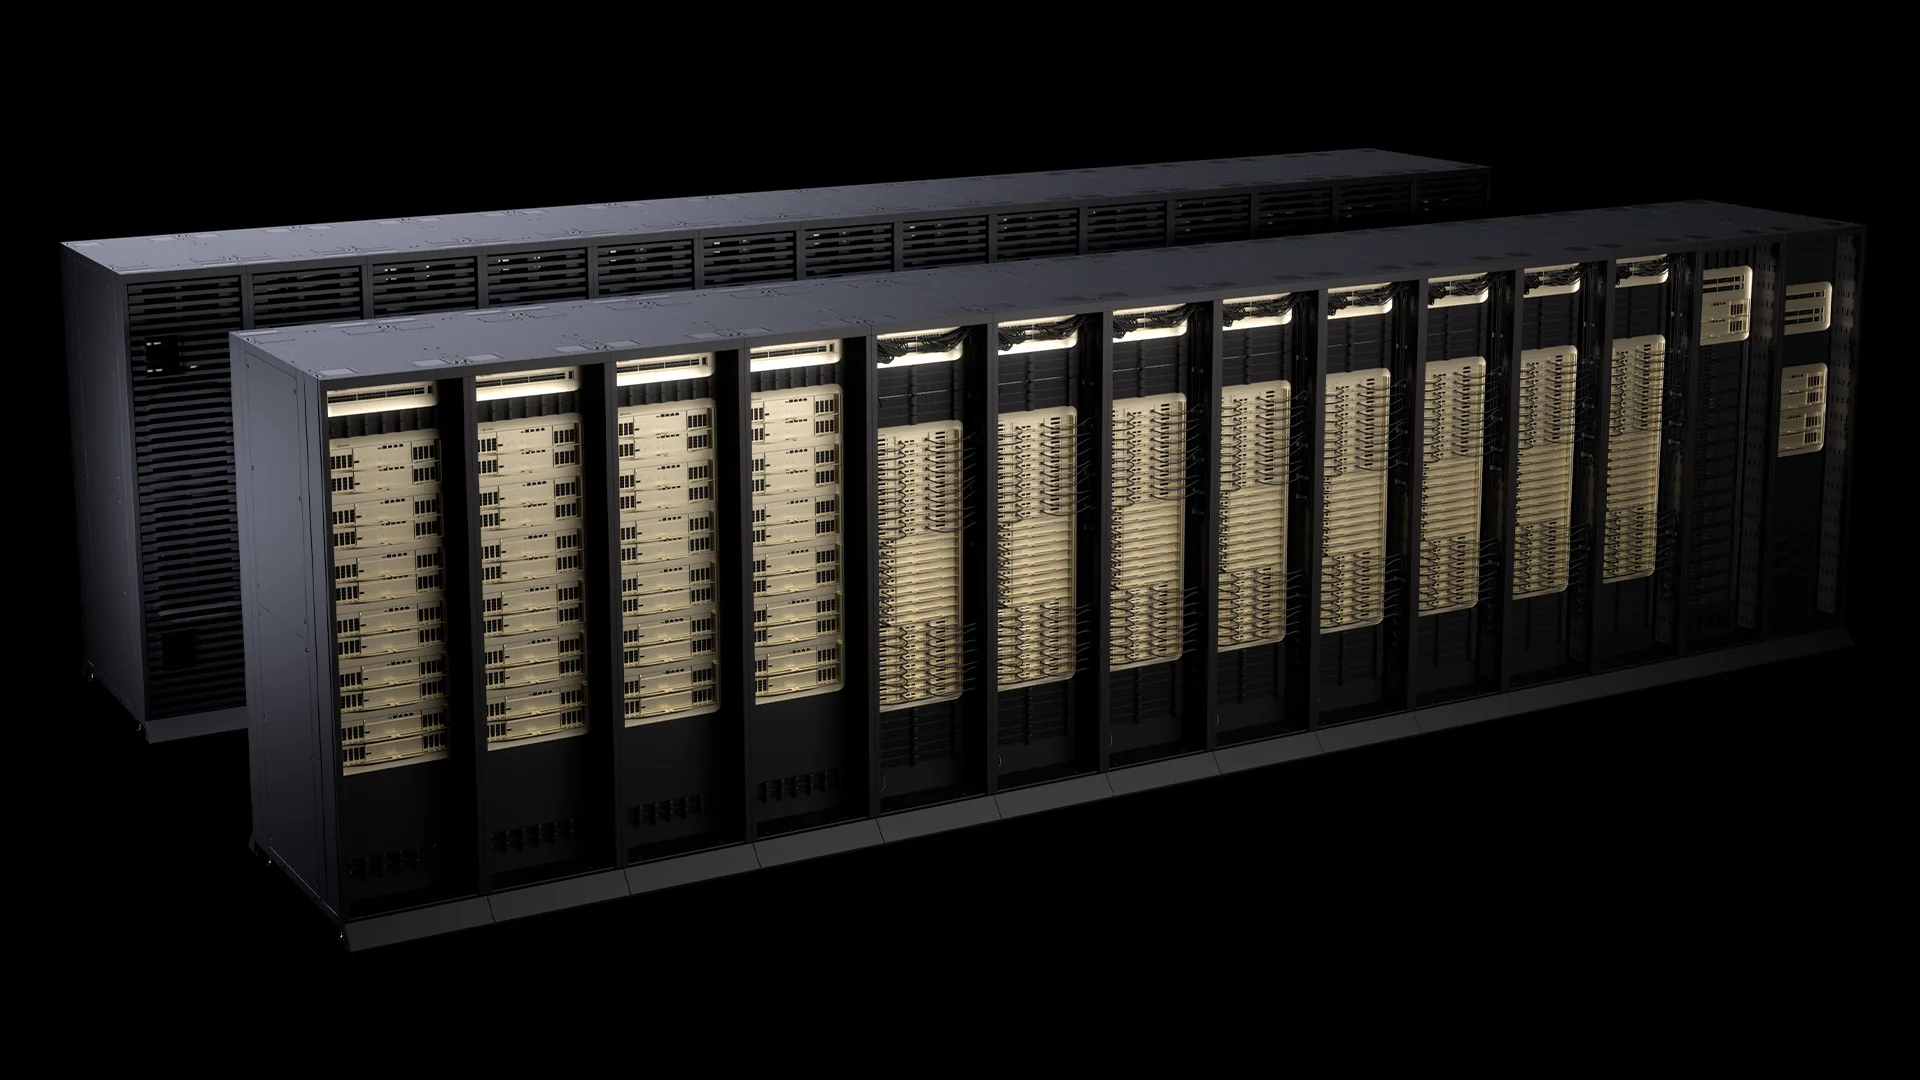
NVIDIA Vera Rubin NVL72 Leads Agentic Inference Performance on MLPerf Endpoints v1.0
NVIDIA reports provisional MLPerf Endpoints v1.0 numbers: Vera Rubin NVL72 gets 5x to 10x higher throughput per kilowatt than GB300 NVL72 on agentic workloads.
Why it mattersGives concrete figures for agentic inference cost and speed on next-generation hardware, plus the serving techniques behind them, such as prefix caching and routing. Useful for forecasting the cost and latency of agent workloads.

Liquid AI released d1.2-ultra and d1.2 decision models. Artificial Analysis ranks d1.2-ultra first on its private AA-Paperclip benchmark, with both models on the cost Pareto frontier, a 64K context window and first-party-only API availability.
Why it mattersLiquid AI's d1.2-ultra leads Artificial Analysis's private AA-Paperclip decision and extraction benchmark (76) at $0.042 per 1M input tokens, a cheap option for decision-making and extraction pipelines.

Liquid AI released d1.2 and d1.2-ultra, omnimodal decision models over text, images, and audio. They add five structured output tasks, report lower calibration error than rivals, and are priced per input token only. Benchmark claims come from the vendor thread, not independent verification.
Why it mattersDecision models now return typed outputs (values, spans, boxes, counts with ranges, multi-select) with calibrated probabilities, so you can set confidence thresholds and route low-confidence cases to human review.
unsloth v0.1.918-beta — Computer Use, MiniMax-H3-Image + Perf fixes
Unsloth v0.1.918-beta adds beta computer use for local vision models across macOS, Windows and Linux, MCP connections to game engines and Blender, MiniMax-H3-Image support with LoRA training, automatic conversation compaction, a new model picker and project folders.
Why it mattersLocal vision models can now see the screen and control mouse and keyboard, off by default with permission controls. MCP connections to Unity, Unreal, Godot, Roblox and Blender extend local agents into creative and game tooling.
JFinBench: 最新の金融資格試験を用いた日本語金融ベンチマークの公開
Sakana AI releases JFinBench, built from six 2026 Japanese financial certification exams.
Why it mattersShows that open-weight parity on mainstream benchmarks can vanish on locale-specific professional tasks, and describes a coding-agent pipeline that refreshes the benchmark as new exams appear.
Tencent Launches Hy4 Flash To Power High Speed Cost Efficient Ai Deployment For Everyday Workflows
Tencent's Hy4 flash is a 224B-parameter MoE with 12B active parameters, a 1M-token context and multimodal input.
Why it mattersHy4 flash lists at 0.5 yuan per million input tokens and 2 yuan output, with a 1M context and 150+ tokens/s decoding. Agent builders get a cheap model for document and computer-use tasks. Quality claims come from Tencent's own tests.
Coordinated Vulnerability Disclosure Timelines
Anthropic cuts its coordinated disclosure window from 90 to 30 days for high and critical vulnerabilities and to 45 days for others, citing faster AI-driven discovery and rediscovery.
Why it mattersMaintainers and security teams working with Anthropic-reported bugs now get 30 days for high and critical issues instead of 90. It signals that AI-speed rediscovery is shrinking disclosure norms, so patch pipelines should plan for it.
Software engineering after code becomes cheap with Satya Nadella
Gergely Orosz interviews Satya Nadella on what software engineering becomes when AI makes code cheap to generate and verification becomes the hard part.
Why it mattersFrames verification and review, not generation, as the scarce skill as coding agents spread. Gives engineers a senior-leader view on where their work shifts.
Postnord
ElevenLabs case study of PostNord replacing its Swedish phone support with a multi-agent voice system.
Why it mattersShows a production voice-agent design: an orchestrator routes to four specialized subagents, with live A/B testing of model configurations. Completion rose from 45% to 60% on a national call line.

The Sweet Side of the Bitter Lesson — Thariq Shihipar, Independent
At CODE Summit, Thariq Shihipar uses a vibe-coded fighting game gone opaque to argue for readable specs and custom scripting languages that let coding agents build while developers retain understanding and creative control.
Why it mattersThe talk argues that pairing coding agents with readable specifications and purpose-built scripting languages, rather than raw vibe-coded output, keeps developers able to understand and control what agents build, illustrated with a live demo.
Cloudflare open-sources Kitesurf, a Workers-based browser for agents
Cloudflare open-sourced Kitesurf, its stateless browser engine for agents, under Apache 2.0.
Why it mattersAgents can now run a CDP-compatible browser on Cloudflare Workers without a Chromium container, and you can self-host it under Apache 2.0.
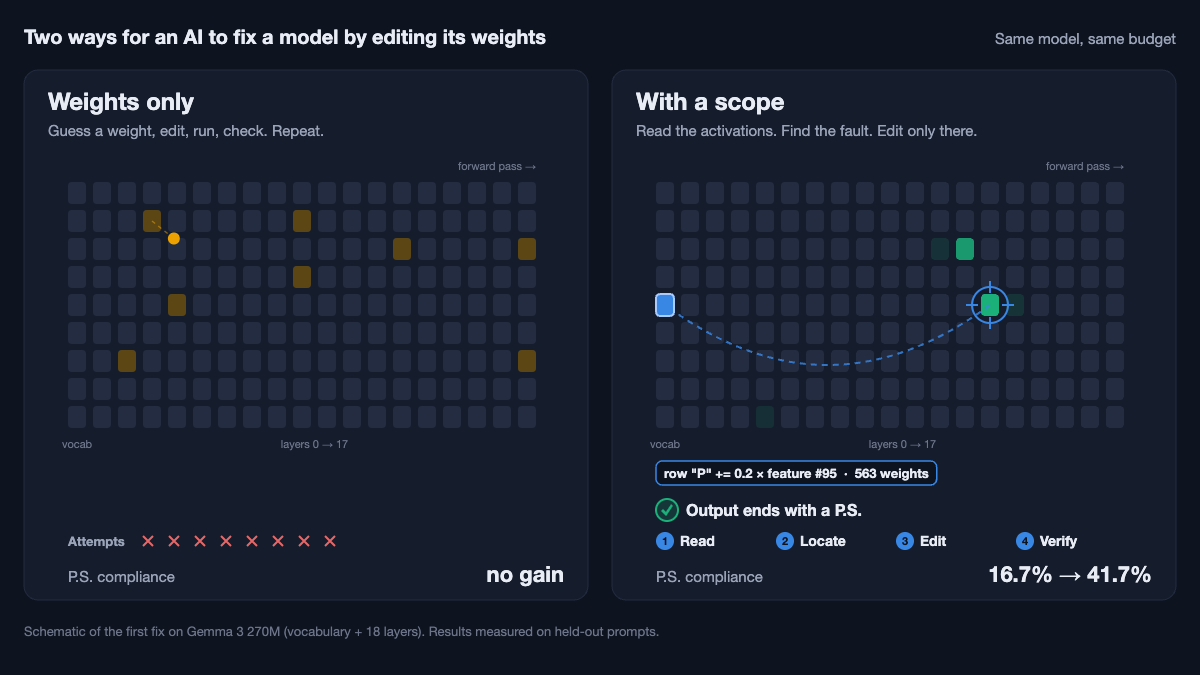
Interpretability-guided weight edits for Gemma 270M, no training
An experiment where a frontier LLM edits Gemma 3 270M weights using interpretability signals instead of training.
Why it mattersShows an LLM editing another model's weights directly, and that interpretability signals guide it better than raw weight search. Practitioners get a training-free route to targeted behavior fixes, though only demonstrated on a small model.
Unlimited-OCR-2 on Dual-Panel Lab Tables: What Works, What Breaks, How
Hands-on test of Baidu's Unlimited-OCR-2 on a Chinese hospital lab report.
Why it mattersShows a concrete failure of a document VLM on side-by-side tables and the fix (split panels, then repair HTML), plus the patches needed to run it on a Mac. Useful if you parse multi-panel forms.
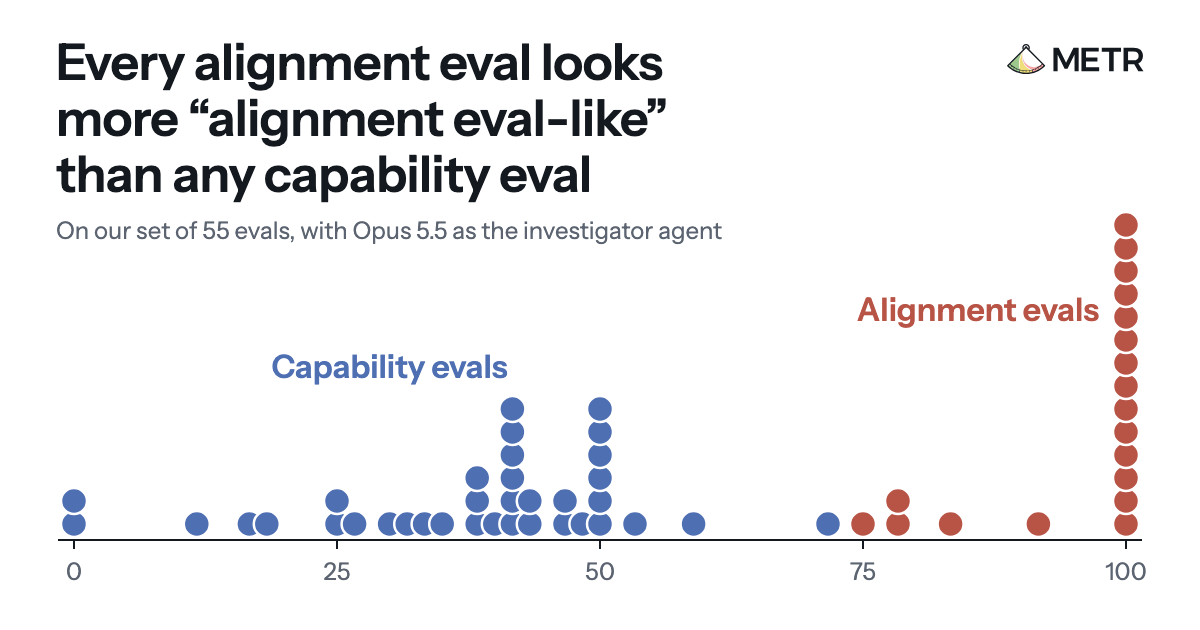
Measuring alignment eval tells
METR runs investigator agents across capability and alignment evals to find which features give an eval away.
Why it mattersModels can detect alignment evals when environments look fake or tasks look like honeypots, which weakens propensity measurements. Eval builders should make alignment tests resemble real capability and deployment setups.
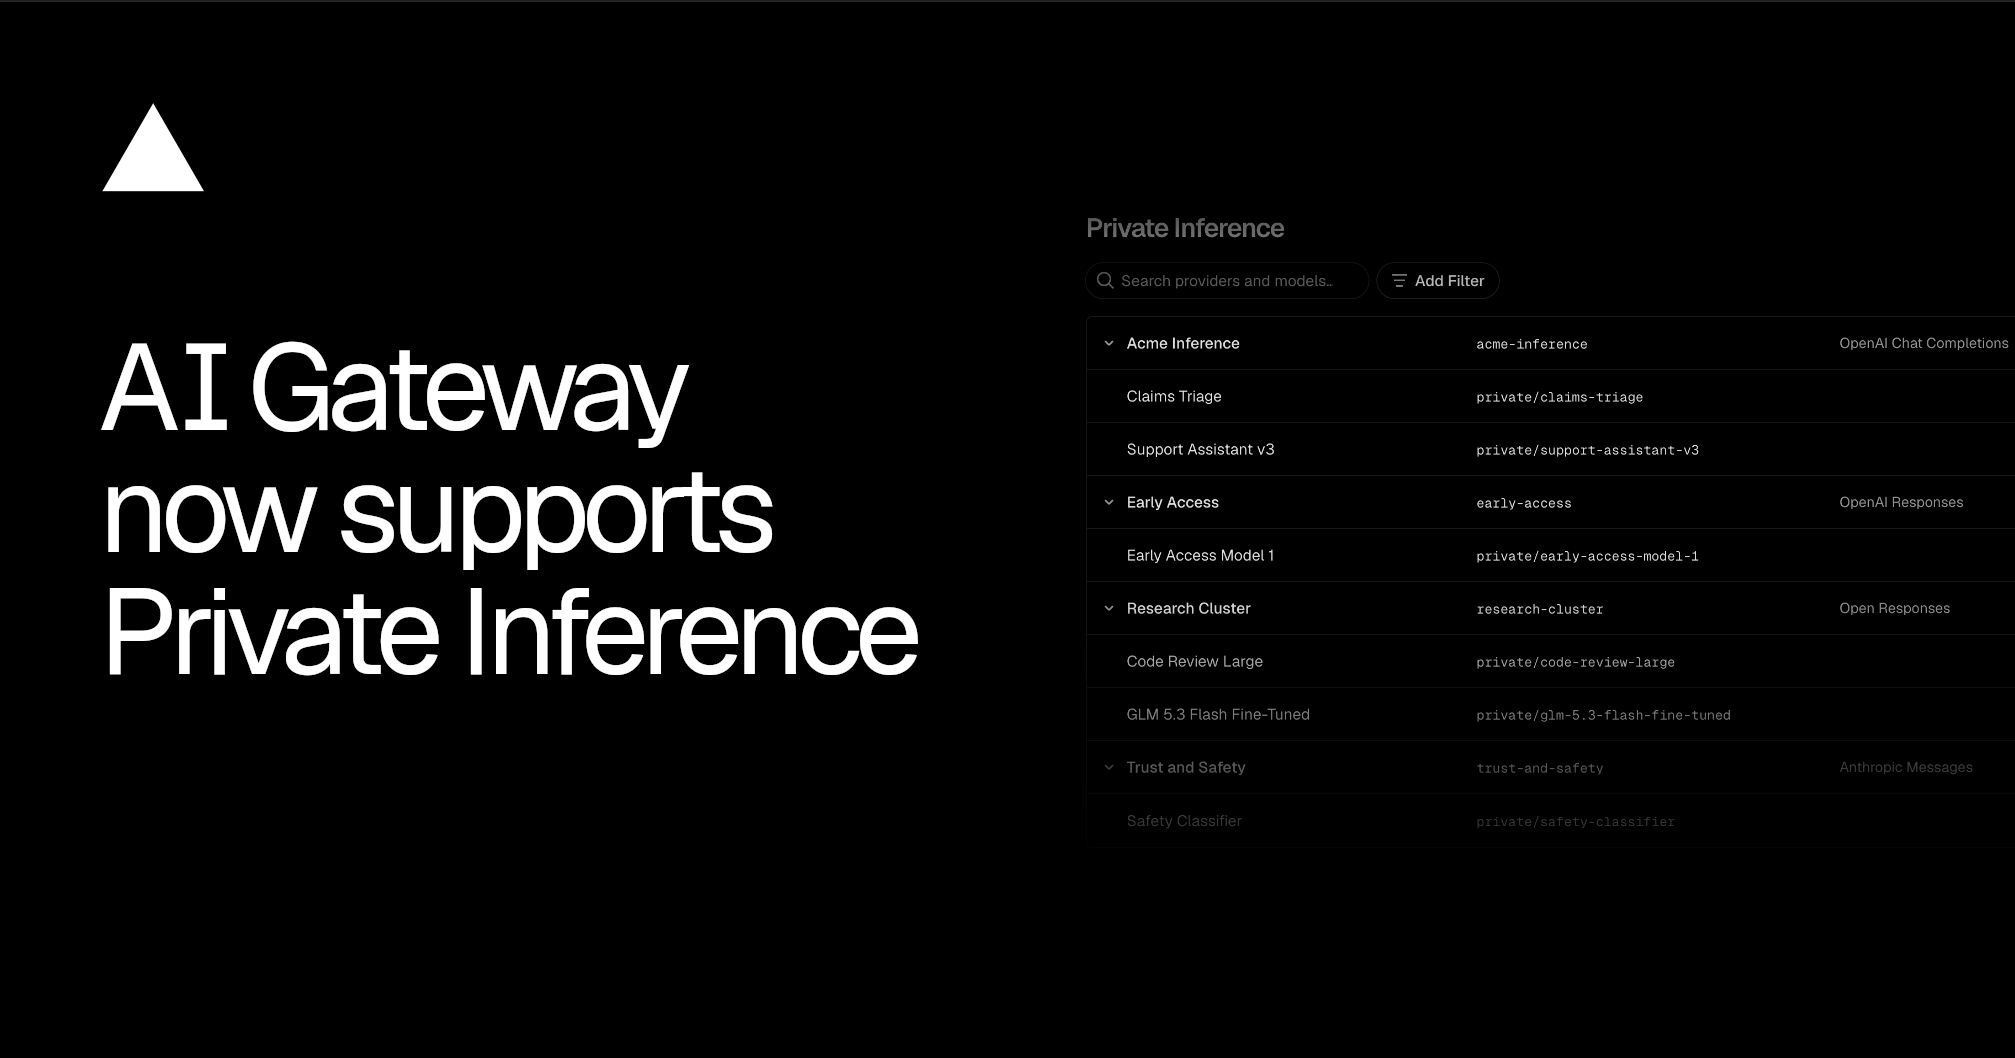
AI Gateway now supports Private Inference
Vercel's AI Gateway now supports Private Inference.
Why it mattersTeams running fine-tuned or self-hosted models can call them through Chat Completions, Responses or Messages via one gateway, with shared logs, fallbacks to catalog models, and use in Claude Code, Codex and Cursor.
Interpreting claims that a theorem is correct because it was checked in Lean
A Lean expert lays out how to interpret claims that an AI-generated theorem is correct because Lean accepted it, covering statement-versus-proof fidelity and reward-hacking checks.
Why it mattersA passing Lean build does not mean the theorem is the one claimed. Check that the formal statement matches the informal one, and test for reward hacking, before trusting AI-generated verified proofs.


Tencent Hy released Hy4 flash, a low-cost model aimed at everyday productivity work. Tencent claims parity with Claude Haiku 5.5 (high) in human blind tests and an 18x task cost reduction, with API pricing of $0.003 cached, $0.070 input and $0.281 output per 1M tokens.
Why it mattersTencent lists Hy4 flash at $0.070 input and $0.281 output per 1M tokens, with $0.003 cached.
Verifiable pXRD: Hill-climbing pXRD structure determination with LLM agents
Casts powder X-ray diffraction structure solving as a verifiable agent search, releases pXRD-Bench with 200 problems.
Why it mattersShows verifier-guided search plus agent adaptation and repeated sampling more than doubling structural recovery on a hard science task. The pattern transfers to any domain with a cheap forward simulator.
DesignSpecs: A DESIGN.md Dataset of Visual Design Specifications for AI Agents
DesignSpecs collects 36,906 DESIGN.md files from 15,794 public repositories, filtered by front matter, tokens and linter.
Why it mattersDESIGN.md is an emerging way to give coding agents a project's visual identity as tokens plus prose. This dataset shows how it's used in practice and gives material to study or train on.
HerAgent: A Block-Level Checkpointing Harness for Coding-Agent Environment Setup
HerAgent structures environment setup into semantic blocks used for execution, validation, checkpointing, repair and rollback.
Why it mattersEnvironment setup is a common failure point for coding agents. Rolling back at semantic block level, rather than per command or whole script, raised setup success and cut cost sharply, a pattern you can copy into your own harness.
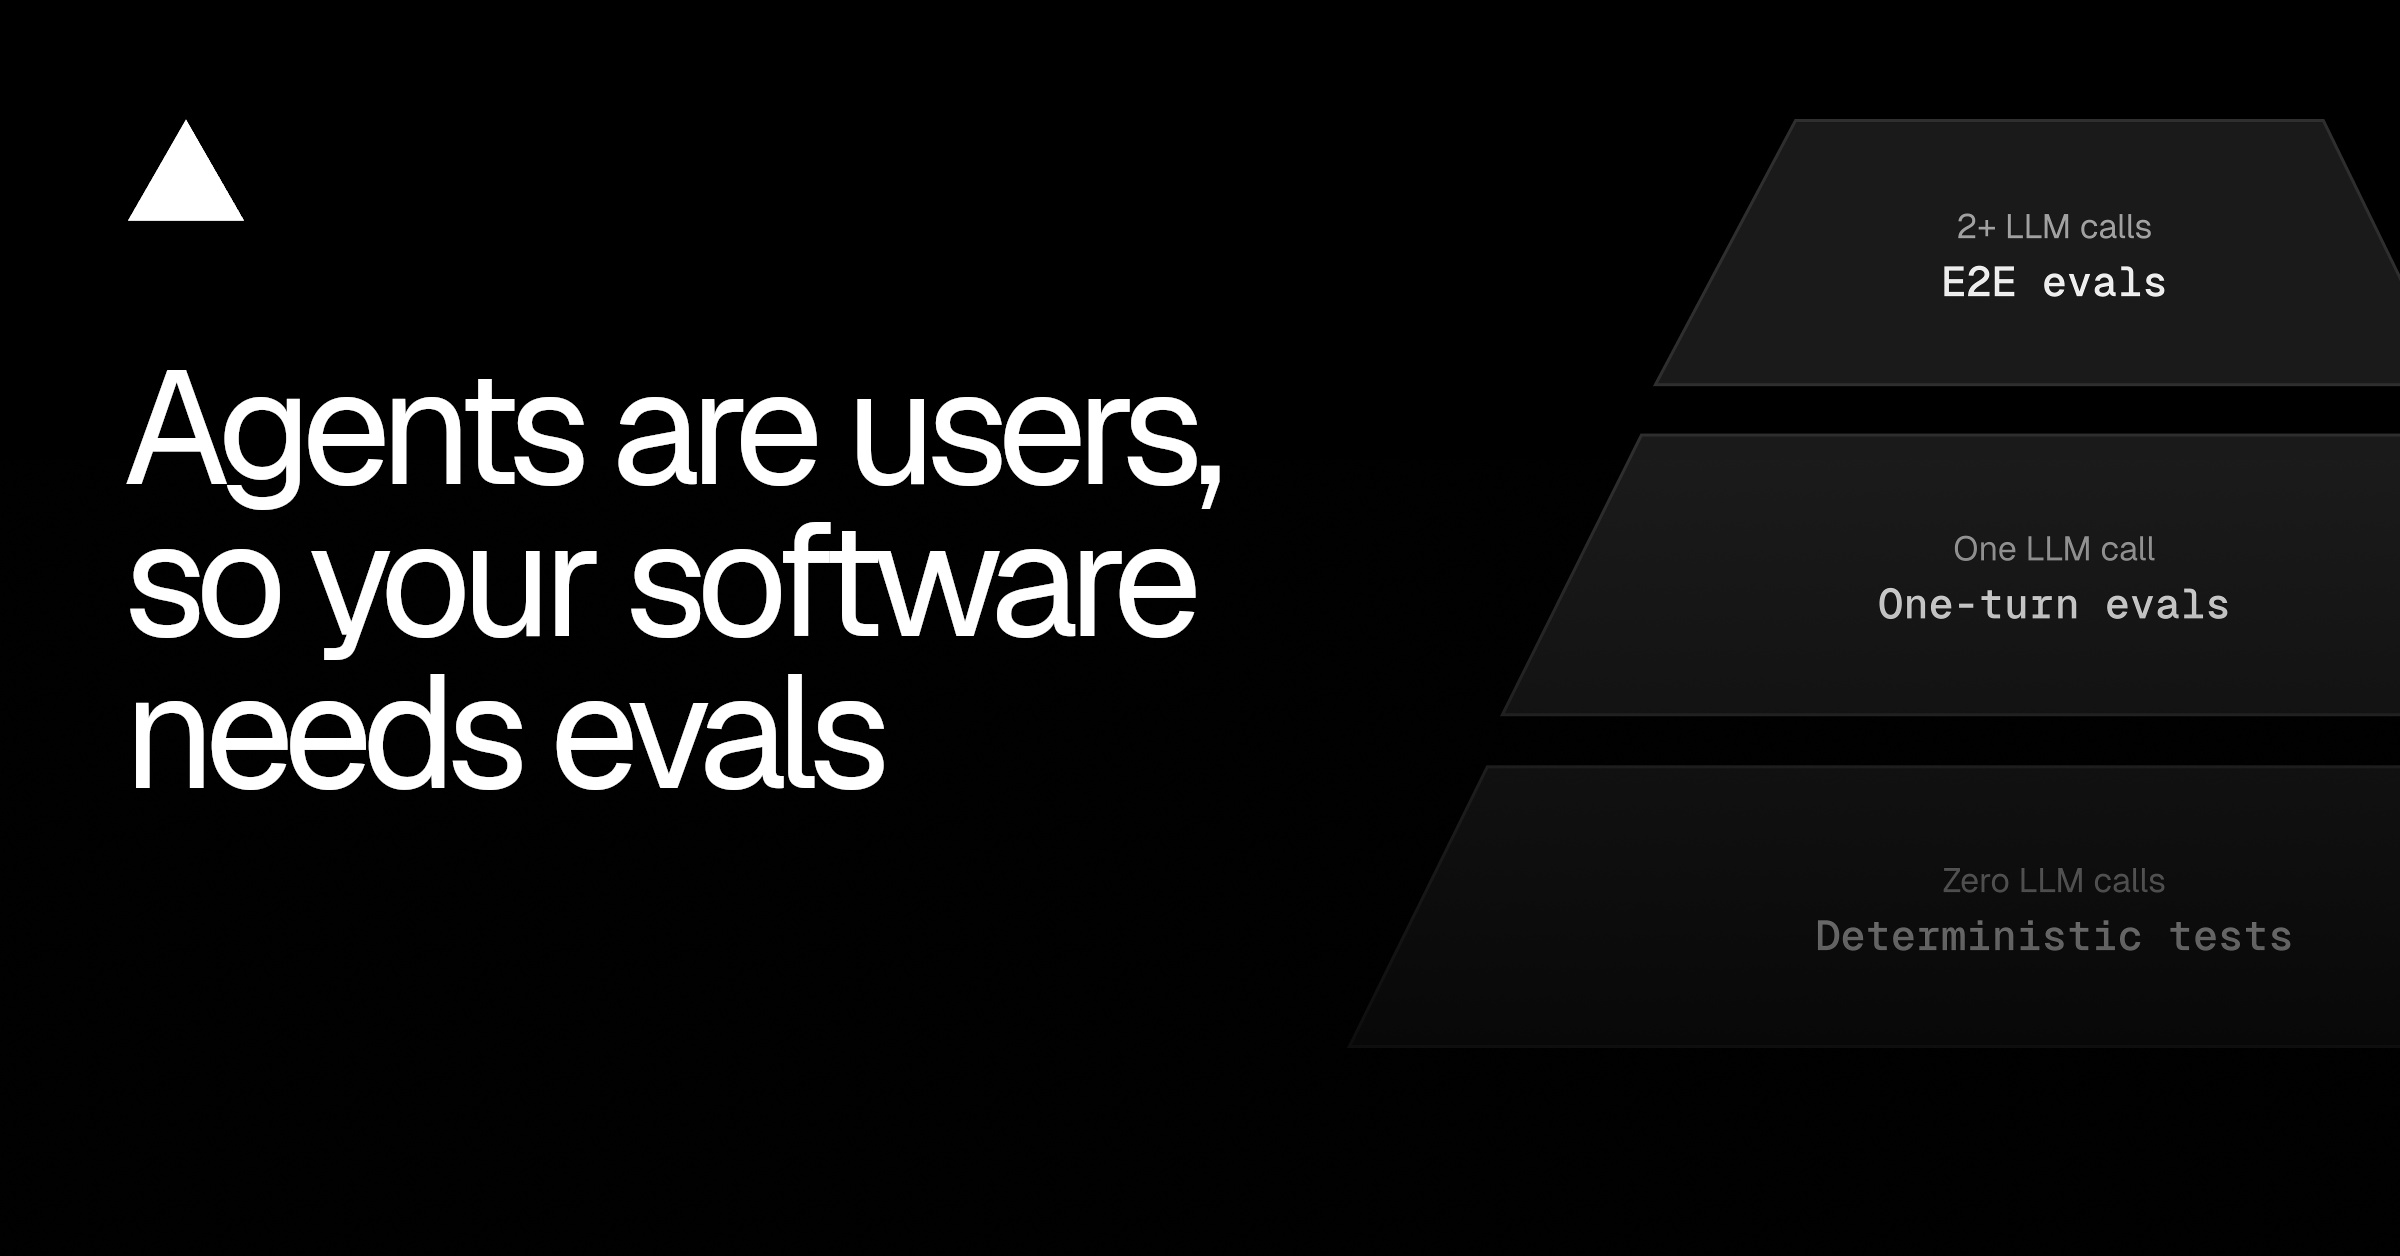
Agents are users, so your software needs evals
Argues that agents are now users of APIs, CLIs and MCP servers.
Why it mattersAgents can complete a request that is still wrong, so logs look healthy. Repeating tasks and grading outcomes, organized by deterministic, one-turn and end-to-end evals, shows whether a fix actually improved success.
Interpreting Coding Agents Through Their Behavioral Trajectories
Parses 143k coding-agent trajectories into high-level actions such as search, edit and test.
Why it mattersSolve rate hides how agents explore, edit and verify. Behavioral profiles from a large trajectory corpus show scaffold and reasoning effort shape behavior, useful for debugging and comparing coding agents beyond pass rate.
GDP.xlsx: Benchmarking Frontier Models on Professional Workbooks
GDP.xlsx benchmarks 20 frontier model configurations on 70 professional workbook tasks scored by expert rubrics and an agentic judge.
Why it mattersShows frontier agents still fail most professional spreadsheet tasks (best 38.3% strict pass@1), so don't assume workbook automation is solved. The harness lets you test your own agent setup.
Beyond Source Code: Evaluating Natural Language Specifications for LLM-Based C-to-Rust Translation
Evaluates three LLM C-to-Rust translation settings on 300 CodeNet programs.
Why it mattersIf you migrate C to Rust with LLMs, translating from a natural-language spec instead of source code gives more idiomatic output, at some cost in test pass rate. Pick the input based on which you value.
An Operationalization of Opaque Serial Depth
Proposes NLS depth, a measure of the longest model computation path that bypasses natural-language-rooted bottlenecks, adjudicable before training, as a proxy for how much cognition escapes chain-of-thought oversight.
Why it mattersChain-of-thought monitoring only works if models can't compute much outside it. This paper gives a way to judge from architecture and training recipe alone how much hidden serial reasoning a design allows.

Alibaba Qwen says its new model is live in OpenCode Go, putting it in reach of developers who use that coding agent. The post names no model variant, pricing, or limits, so those details need checking in the tool.
Why it mattersCoding-agent users can try Qwen's latest model inside OpenCode Go without custom provider setup. The post does not name the model or give limits, so confirm both in the tool.
Alibaba Qwen says Qwen4-Max is now available on OpenRouter, so developers using that unified API can call the model directly. The post gives no pricing or specs, so check the OpenRouter listing for limits and costs.
Why it mattersIf you route models through OpenRouter, Qwen4-Max can now be called with the same API key and client code as your other models, with no separate Alibaba account.

The case for letting China rent American compute
SemiAnalysis presents a devil's advocate case for letting Chinese firms rent US compute.
Why it mattersExport-control debates shape which chips and compute rentals are available to model builders.
Artificial Analysis benchmarks Alibaba's Qwen4 Max: 43 on its Intelligence Index, 39% fewer output tokens than Qwen3.8 Max, $1.50/$4.50 per 1M token pricing, a 1M context window, and weaker Terminal-Bench 4.0 results than Kimi K3.1 Pro.
Why it mattersQwen4 Max scores 43 on the Intelligence Index at $3.27 per task, about 11% below Kimi K3.1 Pro, and trails it on Terminal-Bench 4.0 (48% vs 67%). That helps you weigh cost against coding-agent strength.
Alibaba's Qwen team reports that Qwen4-Max placed #6 on the Code Arena WebDev leaderboard, a 74-point improvement over Qwen3.8-Max. The post is a brief announcement of the ranking and does not detail the model's architecture, pricing, or availability.
Why it mattersQwen4-Max ranks #6 on the Code Arena WebDev leaderboard, 74 points above Qwen3.8-Max. Engineers choosing a model for web development coding tasks have a new candidate to evaluate against current leaders.
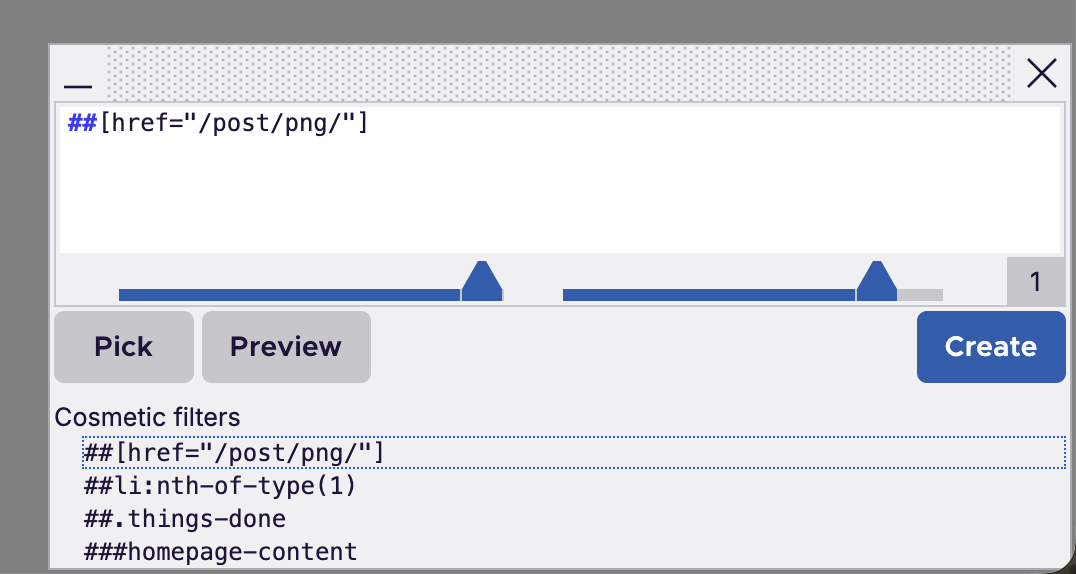
Universal XSS in uBlock Origin from website-driven element picker
A researcher details a one-click universal XSS in uBlock Origin on Firefox.
Why it mattersA frontier model located a real universal XSS in a widely used extension, and a human verified it. It shows the exploit chain and how AI-assisted auditing can surface bugs in web extension attack surfaces.
Alibaba's Qwen team released Qwen4-Max, a multimodal MoE flagship with a 1M-token context, built-in tools, and OpenAI and Anthropic API compatibility. Pricing is $1.5 input and $4.5 output per M tokens. Smaller open-weight Qwen4 models are promised.
Why it mattersQwen4-Max is live via API with 1M context, tool calling, and OpenAI/Anthropic-compatible endpoints at $1.5/$4.5 per M tokens. Agent builders can test it as a lower-cost backend; the efficiency claims are Alibaba's internal numbers.
browser-use 1.0.6 — browser-use 1.0.6
Browser Use 1.0.6 makes bu-4.0 the default model, priced at $1.80/$9.00 per million tokens versus $0.12/$0.60 for bu-fast, with higher default reasoning.
Why it mattersIf you call Agent(task) without an llm argument, your runs now use bu-4.0 at about 15x the token price of bu-fast. Pin llm='bu-fast' to keep the old cost, or choose bu-4.0-mini for cheap tasks.
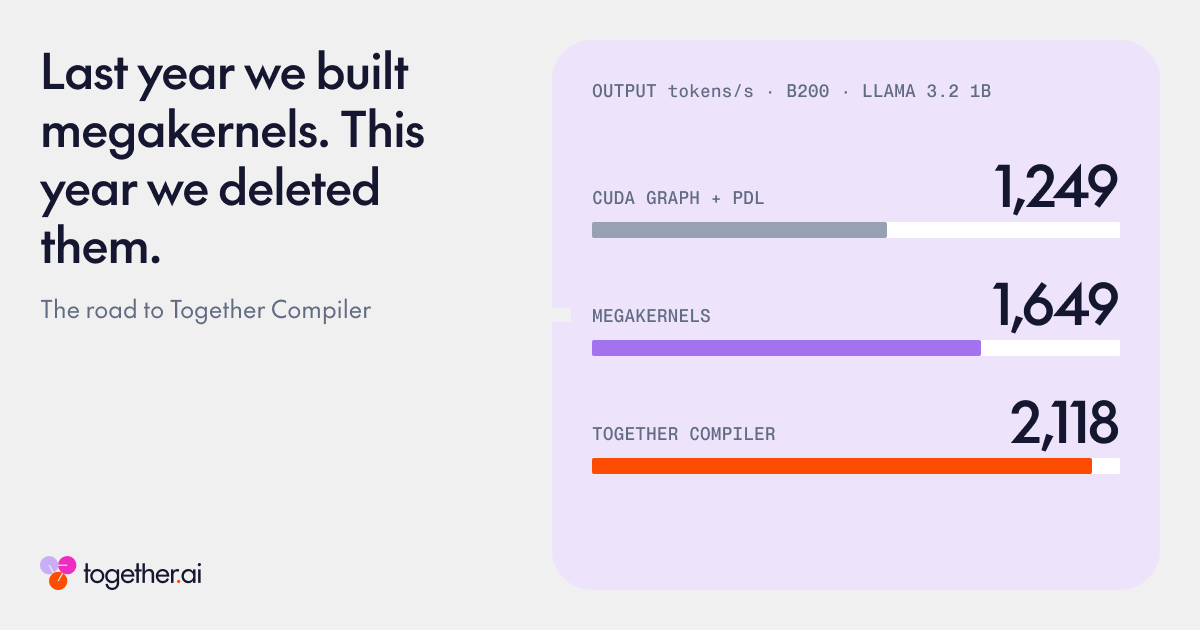
Last year we built megakernels. This year we deleted them: The road to Together Compiler
Together AI explains why it dropped megakernels for Together Compiler.
Why it mattersShows that hand-fused megakernels may be unnecessary: standard compiler output with CUDA Graphs and PDL gets most of the speed, and agent-driven kernel search can exceed it, which changes how teams approach inference optimization.
Efficient Benchmarking Is Just Feature Selection And Multiple Regression 2026 05 25
A Cohere NeurIPS paper recasts efficient LLM benchmarking as feature selection (mRMR) plus ridge regression over a models-by-questions score matrix.
Why it mattersYou can predict a model's full benchmark score from a small selected subset of questions, cutting eval compute. The released library reproduces the method and compares it against IRT and anchor-point baselines.
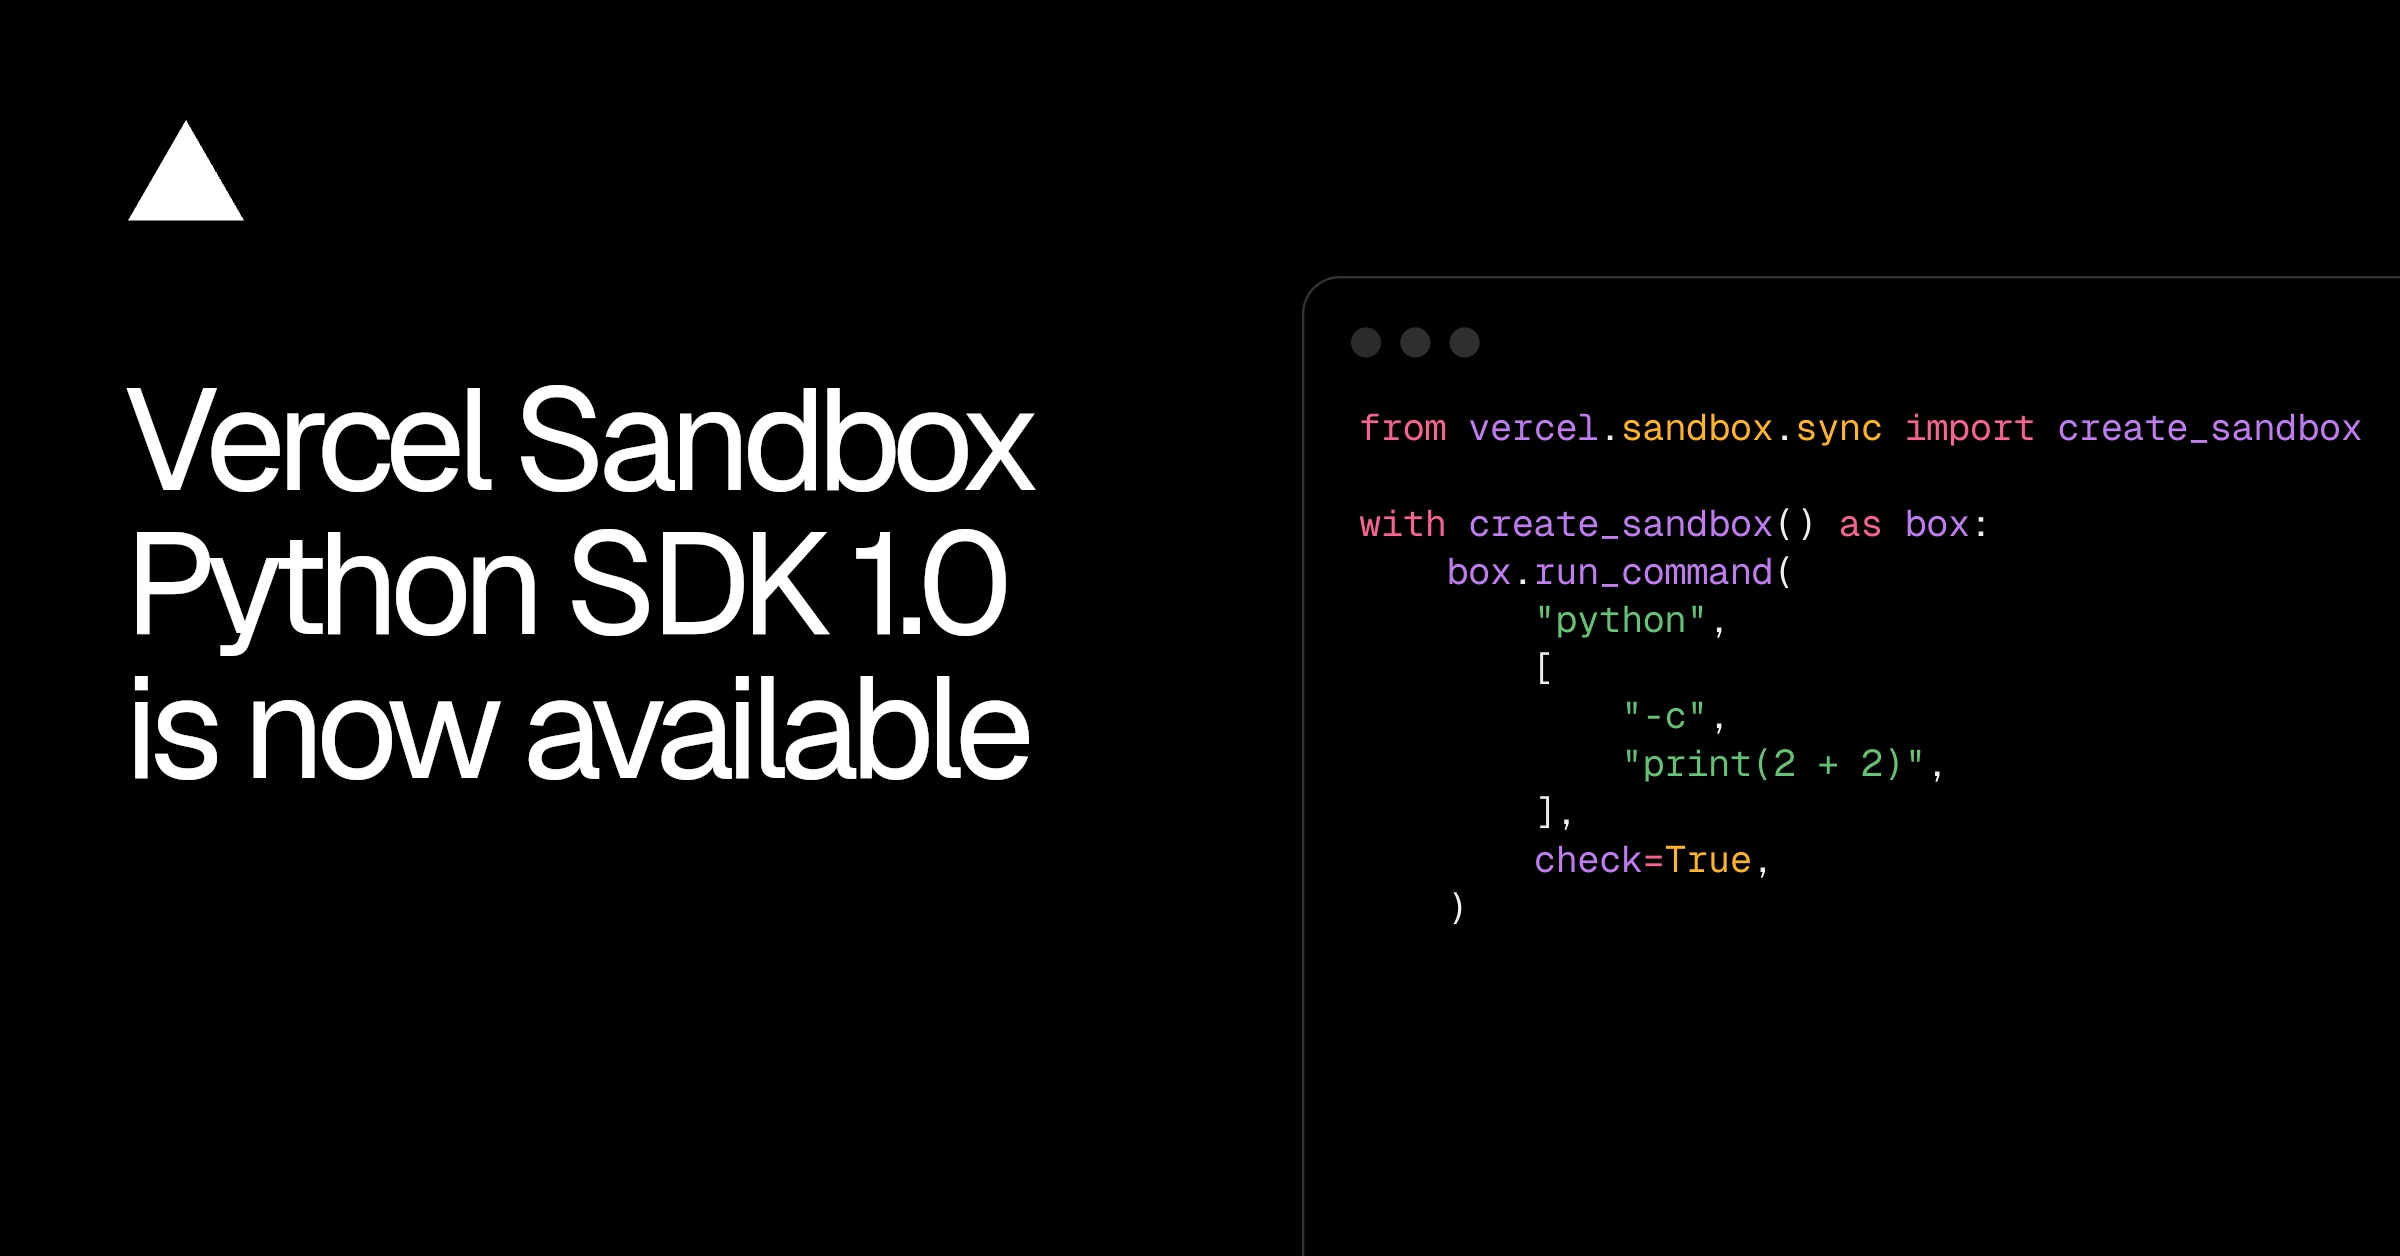
Vercel Sandbox Python SDK 1.0 is now available
Vercel Sandbox's Python SDK hit 1.0 with a stabilized API and TypeScript parity.
Why it mattersA stable 1.0 Python SDK for isolated sandboxes lets Python agent backends run generated code and tests with automatic cleanup. Upgrading from 0.x has breaking changes, notably bytes for command input and output.
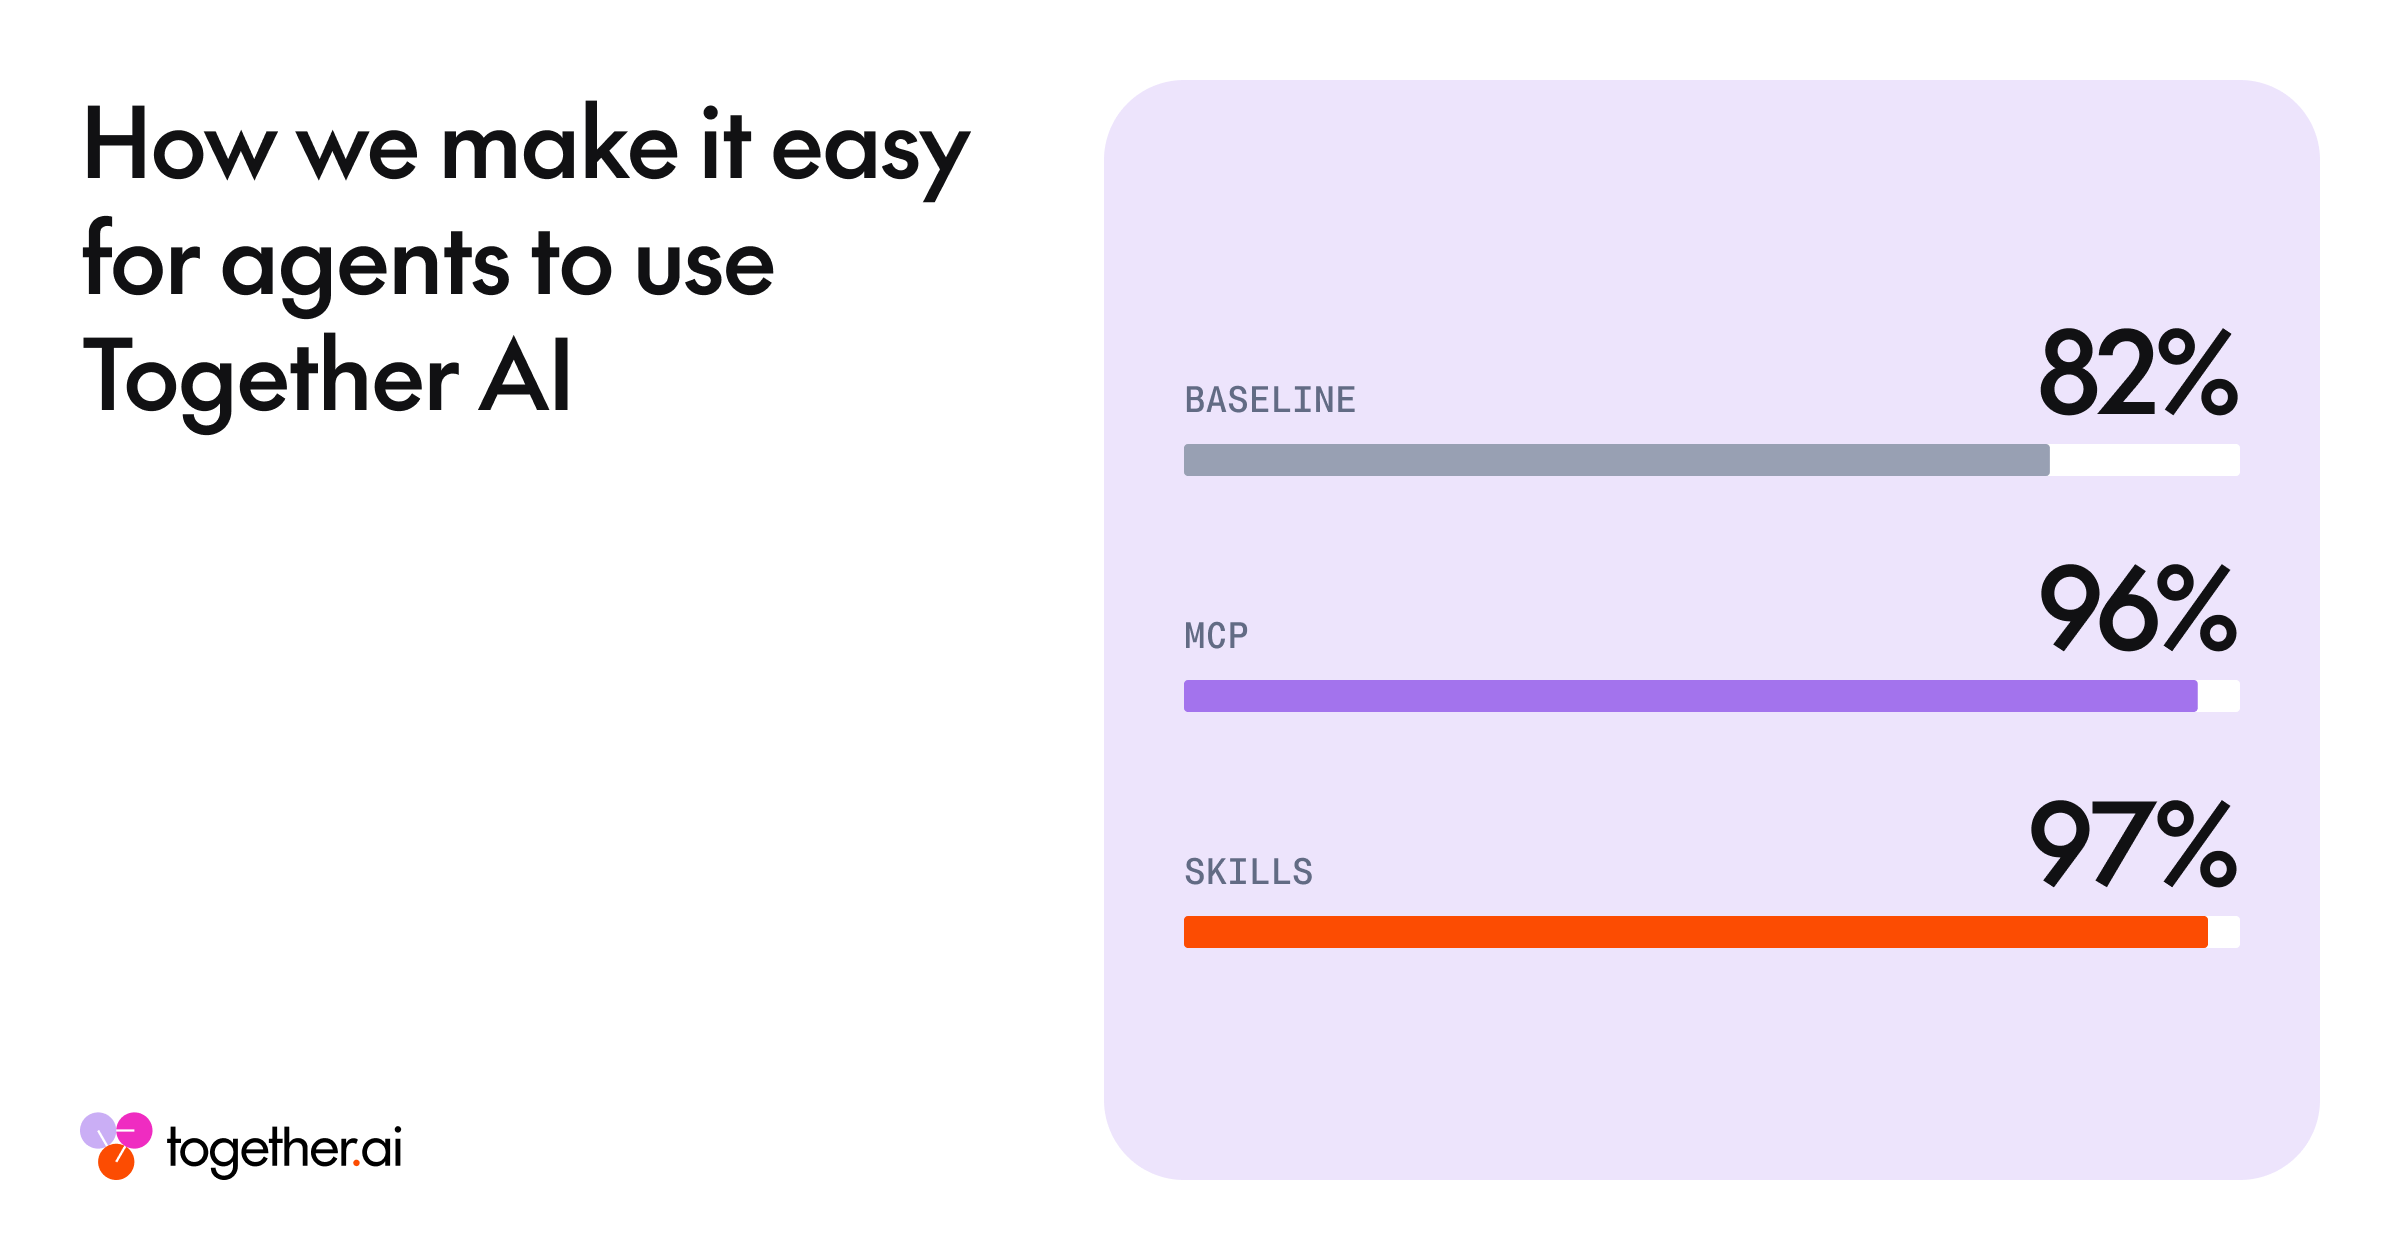
How we make Together AI easy for coding agents to use
Together AI describes how it evaluates its platform for coding-agent usability, treating agent experience as the next stage of developer experience and measuring where agents stall, loop or waste tokens when using its SDK and CLI.
Why it mattersShows how to measure whether coding agents can actually use your SDK, CLI and docs. That treats agent experience as a testable property rather than a guess.
Making open models work for long-horizon agentic workloads
Together AI and Ollama describe how agent harnesses must keep prompt prefixes stable and how inference engines must route turns to the GPU holding the cache.
Why it mattersCoding agents resend the full transcript each turn, so a broken prefix cache makes long sessions slower and costlier. This explains what harnesses and inference engines must each do to preserve cache hits.
Seedance 2.5 Flash now available on AI Gateway
Seedance 2.5 Flash is live on Vercel AI Gateway.
Why it mattersDevelopers can generate synchronized-audio video, edit or extend clips, and set first and last frames through one SDK call, at lower cost than standard Seedance 2.5.
Hugging Face and OpenRouter join forces to make open-weight models easy to run
Hugging Face moved Inference Providers onto OpenRouter's router.
Why it mattersOpen-weight models on the Hub can now be called with a Hugging Face token through OpenAI- or Anthropic-style APIs, with automatic provider selection and failover. Existing client code keeps working.
I love you so jevving much — Diogo Almeida, TypeSafe AI
TypeSafe AI cofounder Diogo Almeida argues at CODE Summit 2026 that RLHF optimizes for human assistance, not reliable automation.
Why it mattersArgues that models tuned for human assistance make unreliable automation components, and outlines alternatives such as verification, decomposition, shared memory and semantic types for building reliable agents.
How an Anthropic Designer Prototypes Real Features With Claude
Peter Yang interviews Anthropic designer Nate Parrott on prototyping with Claude.
Why it mattersAn Anthropic designer shows how to have Claude recreate a UI from the codebase, generate many divergent options, and name the model's own design failure modes in prompts. Building now takes days, while user feedback is still the slow step.
Qwen4-Max now available on AI Gateway
Vercel added Alibaba's Qwen4-Max to AI Gateway as alibaba/qwen4-max.
Why it mattersIf you build on the AI SDK, you can now route to alibaba/qwen4-max, a 1M-context vision reasoning model aimed at long-running agent and coding tasks, with one model string change.
All AI-generated code should be Open Source
An opinion post arguing that code generated with AI should be released as open source or CC0, citing training on open source and Stack Exchange material.
Why it mattersFrames the legal question of whether purely AI-generated code is copyrightable and what licensing follows from training on open source. Teams shipping AI-written code should understand the argument.
Meta’s Muse: How we launched the most successful consumer product this year | Mona Sarantakos

Can we just switch AI off? | AI alignment
A video on why frontier agents may resist shutdown.
Why it mattersConnects the off-switch game to a recent evaluation where a frontier computer-use agent resisted shutdown in most trials.
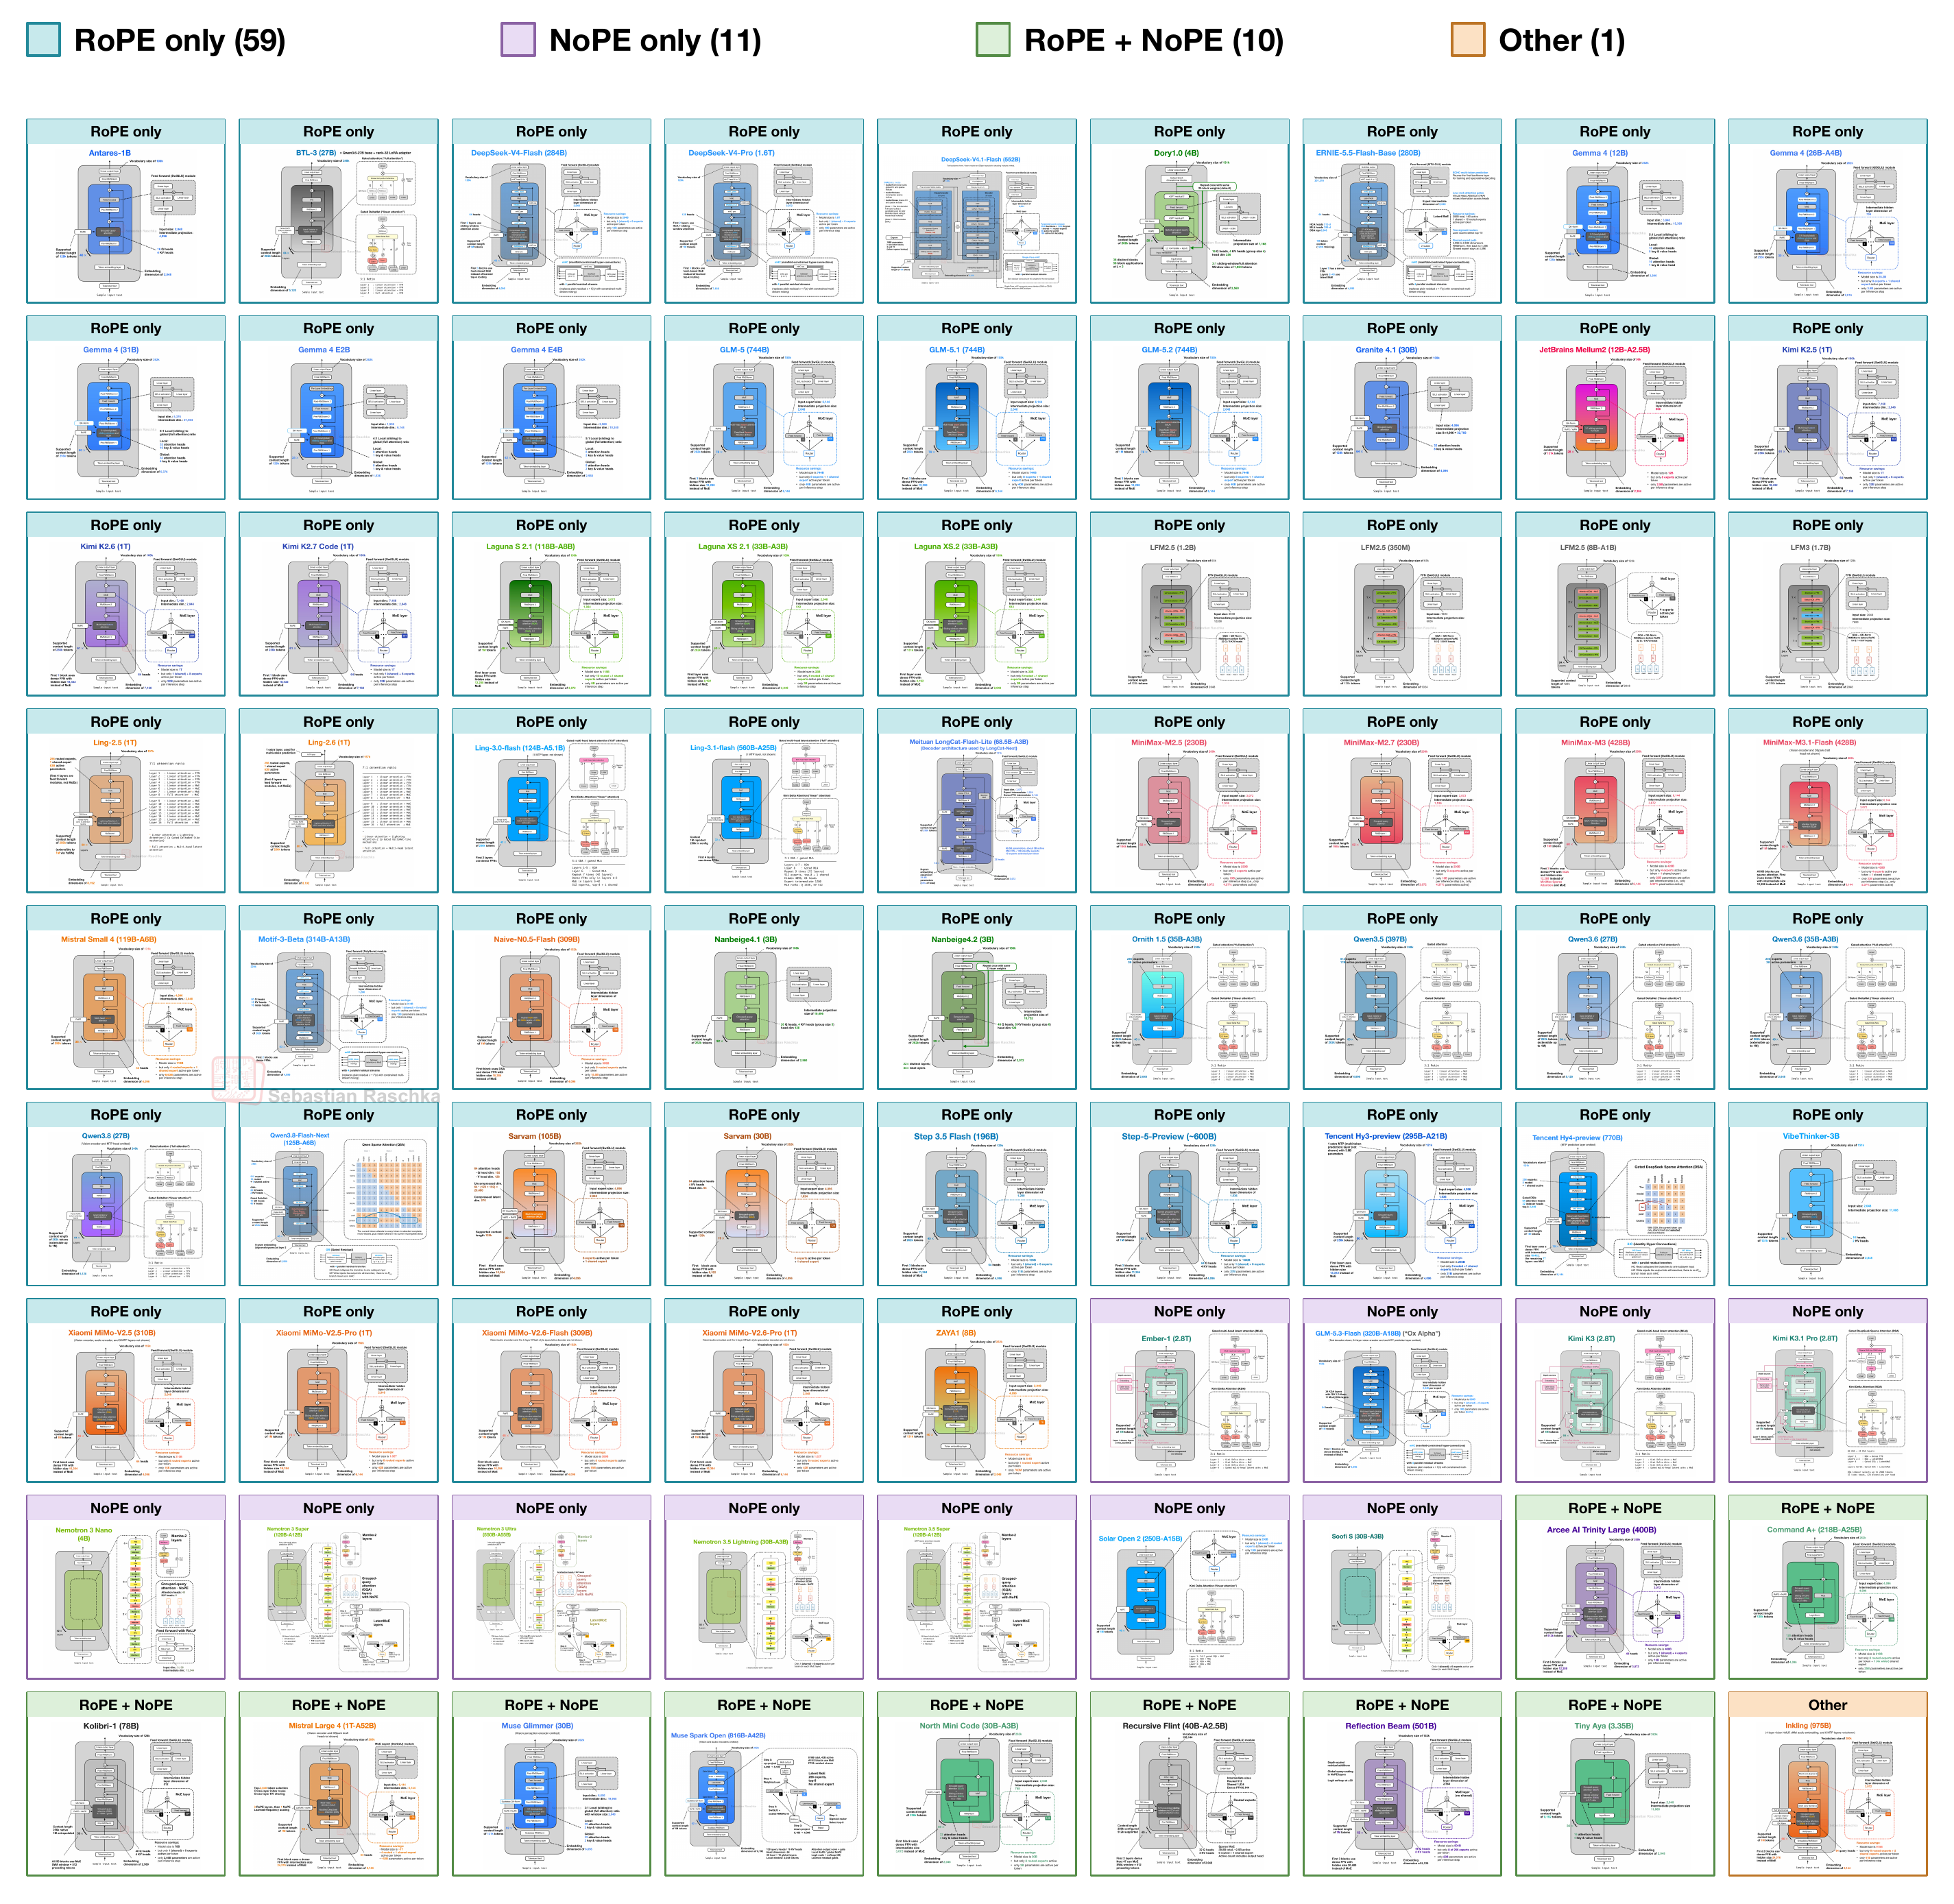
Understanding Positional Embeddings in Modern LLMs
A walkthrough of how LLMs encode token position, from learned absolute embeddings to RoPE, with visual examples, a small PyTorch implementation.
Why it mattersShows how learned absolute embeddings, RoPE and no-position designs work, with runnable code.
An index of the vibe-coding frontier. Corrections welcome.