Intel
Page 70
Breaking Models to Test the Judge: A Mutation Testing Approach for Semantic Evaluators of Domain Class Diagrams
Rather than asking humans whether an LLM judge is right, inject known semantic defects and see if it catches them.
Why it mattersIf you rely on an LLM judge, mutation testing gives you a way to measure whether it actually detects defects instead of trusting spot-checks: inject known faults, score detection, compare to human validation.
DepWareTrans: Dependency-Aware Incremental Repository Migration across Co-executable Languages
Traces repository-scale code translation failures to dependency inconsistency between files.
Why it mattersAnyone pointing an agent at a whole-repo migration hits fragmentation across inter-file dependencies. Naming dependency inconsistency as the root cause suggests where to spend orchestration effort.
Engineering Reliable Coding Agents: Evaluating and Operating the System Around the Model
A monograph on operating coding agents as systems rather than models, locating reliability in the harness, execution state, retrieval, memory, permissions and review surfaces that surround the model.
Why it mattersTeams debugging agent failures reach for a better model first, when the defect is usually in the surrounding system. This gives a structured place to look and a vocabulary for evaluating the harness itself.
GRPO Beyond English: A Large-Scale Study of GRPO in Non-English and Multilingual Settings
A large study of reinforcement learning with verifiable rewards outside English, sweeping base models, training languages and reasoning-language rewards.
Why it mattersTeams doing RLVR post-training outside English have been extrapolating from English-only results. This says the native-language reasoning penalty is small, which changes how those training runs get configured.
LegacyWorld: Atomicity-Aware Evaluation of GUI Agents for Legacy Workflows
An evaluation of graphical-interface agents on stateful legacy workflows that scores atomicity, counting the invalid changes a failed run leaves behind rather than only whether the task eventually succeeded.
Why it mattersMost agent benchmarks score the end state and ignore the wreckage of failed attempts. For anyone deploying computer-use agents against real records, partial-failure damage is the risk that actually matters.
Modular Cognitive Architecture Emerges in Large Language Models
Circuit analyses across 46 tasks in four cognitive domains find that language models develop specialized regions echoing human brain organization.
Why it mattersIf task families recruit distinct neuron populations, that is a handle for interpretability work, targeted editing, and reasoning about which capabilities interfere. It reframes model internals as modular rather than uniformly entangled.

Codex exposes an opt-in 1M-token context window for GPT-5.6 Sol, newly documented after repeated requests. OpenAI tuned the default lower on purpose and says autocompaction is near-seamless — its own researchers advise against raising the limit.
Why it mattersCodex now documents an opt-in 1M-token context for GPT-5.6 Sol, but OpenAI's own researchers say the tuned default with autocompaction wins on both performance and cost.
A/B test models in production
Together's endpoints can now split live traffic across a control and up to 20 model variants, ramp a winner via blue-green rollout.
Why it mattersModel A/B splits move from feature flags and hash-mod routing in your application to the endpoint itself, so you can expose a candidate model to a chosen slice of real users and unwind it with one call.
Activity Dashboard
Usage analytics for teams running agents.
Why it mattersPer-agent, per-model and per-request spend, cache hit rate and tail latency are now queryable and groupable.
Deploy Cursor Origin repositories with Vercel in public beta
Vercel opened public beta support for Cursor Origin repositories.
Why it mattersAnyone weighing Origin needs to know the deploy path already exists, and the speed of the wiring shows how fast the ecosystem is adapting to a week-old hosting platform.
GPT-5.6 Sol is 50% off on AI Gateway for the next month
Vercel is running GPT-5.6 Sol at half price on its AI Gateway through September 18, across every service tier including fast mode.
Why it mattersAnyone already sending Sol traffic through this gateway gets the lower rate with no code change, and the window closes September 18.
DeepSeek V4 Pro 0813 vs Claude Fable 5 on DeepSWE: Cost, Coding, and Routing
A DeepSWE comparison of DeepSeek V4 Pro 0813 and Claude Fable 5 that measures a 90x cost gap and an unusually low per-task correlation, the property that makes escalation routing between them worthwhile.
Why it mattersCross-model disagreement, not average accuracy, is what makes a cascade pay off, and this puts a number on it for two models at opposite ends of the price sheet.
$12B of US ratepayers' money wasted on a modeling mistake and PJM wants to do it again
SemiAnalysis rebuilt PJM's black-box Reserve Requirement Study and argues its methodology ignores winter efficiency gains and post-Elliott resilience, understating capacity by ~4GW.
Why it mattersPower in America's largest electricity market is procured off a model that understates existing supply by roughly 4GW, inflating capacity costs and squeezing the grid headroom datacenter expansion depends on.
Qwen 3.8 27B is excellent, but it defaults to wildly overthinking things
Hands-on notes on Qwen 3.8 27B, the Apache 2 licensed vision-capable release from Alibaba's Qwen lab, run in quantized form on a 128GB MacBook Pro and an NVIDIA DGX Spark.
Why it mattersA capable vision model in the 27B range runs on a well-specced laptop, but its default reasoning effort makes it impractical there; anyone trying it should turn that setting down before judging the model.
Guillermo Rauch on Vercel's Shift Toward Agentic Infrastructure
In this interview, Vercel founder Guillermo Rauch describes how the platform has evolved from deploying front-end websites to hosting AI coding agents and autonomous software, driven by models like Opus 4.5.
Why it mattersRauch argues platforms must shift from human-facing elastic compute to 'agentic infrastructure' that lets coding agents deploy, secure, and maintain software autonomously over hours or days.
awesome-claude-code
A curated, community-maintained list of resources for Claude Code, covering guides, skills, agents, status lines, developer tooling, plugins, and orchestration patterns.
Why it mattersIt aggregates guides, skills, agents, plugins, and observability tools for Claude Code in one continually updated place, saving practitioners from hunting across scattered repos and blog posts.
Awesome Hermes Skills
A curated, install-ready directory for the Hermes Agent ecosystem from Nous Research, cataloging the agent's 82 built-in skills, a 117-skill optional catalog.
Awesome Claude
A curated directory of Claude AI resources for developers, aggregating official Anthropic documentation, SDKs (Python, TypeScript, Java, Go, Ruby, C#, PHP), agent SDKs, cookbooks, quickstarts, cloud provider integrations (Bedrock, Vertex AI, Azure), system cards.
Awesome Claude Code
A curated, hand-maintained list of resources for Claude Code, organizing links to guides, skills, agents, status lines, plugins, orchestration tools.
Why it mattersIt aggregates guides, skills, agents, plugins, and observability tools for Claude Code in one continually updated place, saving practitioners from hunting across scattered repos and blog posts.

An OpenAI engineer documents the exact Codex config keys for running GPT-5.6 Sol at a one-million-token window, plus a single-session CLI override, with a warning that the shipped default was tuned deliberately for cost and performance.
Why it mattersCodex ships a tuned default context budget; these three config keys raise it to 1M tokens for GPT-5.6 Sol, and the capability now works on ChatGPT accounts rather than API keys only.

Tuhin Srivastava (Baseten) on Production Inference Economics
Baseten is an AI inference infrastructure platform that runs production machine learning models—including custom and post-trained open-source models.
Why it mattersBaseten's CEO makes the case that once you are at scale, renting a frontier API stops being the cheap option and post-training an open model becomes both the cost play and the moat.

Anthropic and Chai Discovery on AI-Accelerated Drug Development
A Stanford guest lecture transcript featuring Anthropic's Eric Abrams and Chai Discovery's Josh Meier discussing how AI models are being applied across drug discovery and life sciences R&D.
Why it mattersExplains specific technical bottlenecks in applying AI to the 10-15 year drug development pipeline and how Anthropic's Claude and Chai's molecular design platform are targeting them.

Yash Patel on the History and Future of AI Model Training
A Stanford talk transcript in which Applied Compute founder Yash Patel traces AI model development from AlexNet through transformers, scaling laws, RLHF.
Why it mattersArgues the next AI capability bottleneck is continual, data-efficient learning from sparse real-world feedback rather than more pretraining, and explains why verifiable domains like code and math currently dominate RL training.

The Economics of the AI Super Cycle: OpenAI's Compute Strategy (with Sachin Katti)
A Stanford class interview with Sachin Katti, who leads industrial compute at OpenAI and previously served as Intel's CTO, on how OpenAI plans and builds compute at gigawatt scale.
Why it mattersOpenAI's compute chief explains the roadmap to 30GW of capacity and why inference workloads will dominate future compute demand.

Ali Ghodsi on AGI, Enterprise AI, and Whether Software Is Dead
In this talk/interview, Databricks CEO Ali Ghodsi argues that AGI already exists by decades-old research definitions but remains useless inside companies because AI agents lack the tacit organizational context that veteran employees carry in their heads.
Why it mattersGhodsi argues that even if AGI meets old technical definitions, it remains blocked from real enterprise value by missing tacit organizational context that human employees hold.

Chase Lockmiller (Crusoe) on the AI Data Center Economy
A fireside talk with Crusoe founder and CEO Chase Lockmiller explaining how AI infrastructure is built.
Why it mattersCrusoe's Abilene campus shows energy availability, not GPU supply, is now the binding constraint on scaling AI compute, and negative power prices in West Texas are actively shaping where hyperscale AI infrastructure gets built.

Brad Gerstner and Sunny Madra on the Economics of AI Inference
A fireside chat transcript in which Altimeter Capital's Brad Gerstner and Groq's Sunny Madra discuss why AI inference, unlike traditional software, has significant marginal compute costs, tracing Groq's origins, its bet on cloud-hosted inference chips, and the shift toward reasoning models that consume vastly more tokens.
Why it mattersExplains why reasoning models' heavy token consumption changes inference cost structure, and details the prefill/decode disaggregation strategy Groq used to improve inference efficiency at scale.

GitHub made Balanced depth generally available for Copilot code review alongside the existing Lite mode, with the default settable at the organization or repository level and overridable when requesting a review on a single pull request.
Why it mattersTeams running Copilot code review can now put deeper analysis on risky pull requests and keep lightweight reviews on routine ones, set as a default or chosen per request.
OpenAI’s Head of Design: This is the best time in history to be a designer | Ian Silber

GLM 5.3 Is HERE – Is THIS the BEST Open Model Yet?
A hands-on test of GLM 5.3 across browser workflows, C++ game development, 3D CAD modelling, frontend design and FPS generation, asking whether it earns the title of best open model yet.
Why it mattersGives practitioners a task-by-task read on whether GLM 5.3 holds up as a coding model against the closed frontier, which is the decision anyone weighing an open-weight backend actually has to make.
An argument that a token is not a standard unit: identical text costs different token counts on different tokenizers, so a cheaper per-token price can still produce a larger bill. One sample measured 766 tokens on GPT-5.6 Sol against roughly 1,170 for Claude Opus 5. Vendor-authored, so verify on you
Why it mattersComparing list price per token across models with different tokenizers understates the real bill. Tokenize your own representative text before choosing on price, then measure cost per completed task.

Hermes Agent Desktop gains Bot Mode: instead of ephemeral sessions, you define persistent bots with jobs, descriptions and avatars that can hand work to each other. Nous opened a public beta window for it.
Why it mattersHermes Desktop moves from one-session-per-chat to persistent agent profiles with assigned jobs that can talk to each other — a local multi-agent setup available to try in the public beta.

A blog post detailing how the author used Codex as an autonomous research loop—iterating over 1500 submissions across 14 days—to optimize a batched Householder QR decomposition CUDA kernel, placing 12th of 183 in a GPU Mode contest with a 232x speedup over baseline.
Why it mattersIt shows what an agent loop can do when the scoring signal is fast and objective, and names the harness conditions that made it work. That is a reusable pattern for anyone pointing a coding agent at an optimization problem.

Claude's text watermark changes where sampling randomness comes from rather than which words get picked, which is why output quality is unaffected. Anthropic is rolling it out for EU AI Act compliance; an interactive explainer walks the mechanism step by step.
Why it mattersWatermarking is landing in Claude's text output under the EU AI Act, and it works by shifting the randomness source rather than the words — quality is unchanged, but generated text becomes detectable.
Go from an empty repo to a live GitHub Pages site on a custom domain, secured wi
GitHub shows Copilot CLI plus a community Namecheap skill going from an empty repo to a live GitHub Pages site on a custom domain with HTTPS in about 14 minutes.
Why it mattersShows the skill mechanism in a coding CLI reaching past code into registrar and DNS setup, which is the kind of end-to-end delegation builders are trying to scope right now.
React for Agents: Astro Creator Brings Hooks to his Meta-Harness, Flue
Fred Schott's Flue reaches its first stable release built on React-style Agent Hooks, where an agent is a JavaScript function that re-renders before every model call and can manage its own state and attach capabilities mid-run.
Why it mattersAgent Hooks are a concrete answer to how agent state and capabilities get composed at runtime, from the person who built Astro. Engineers picking a harness now have a second serious design to compare against Vercel's eve.
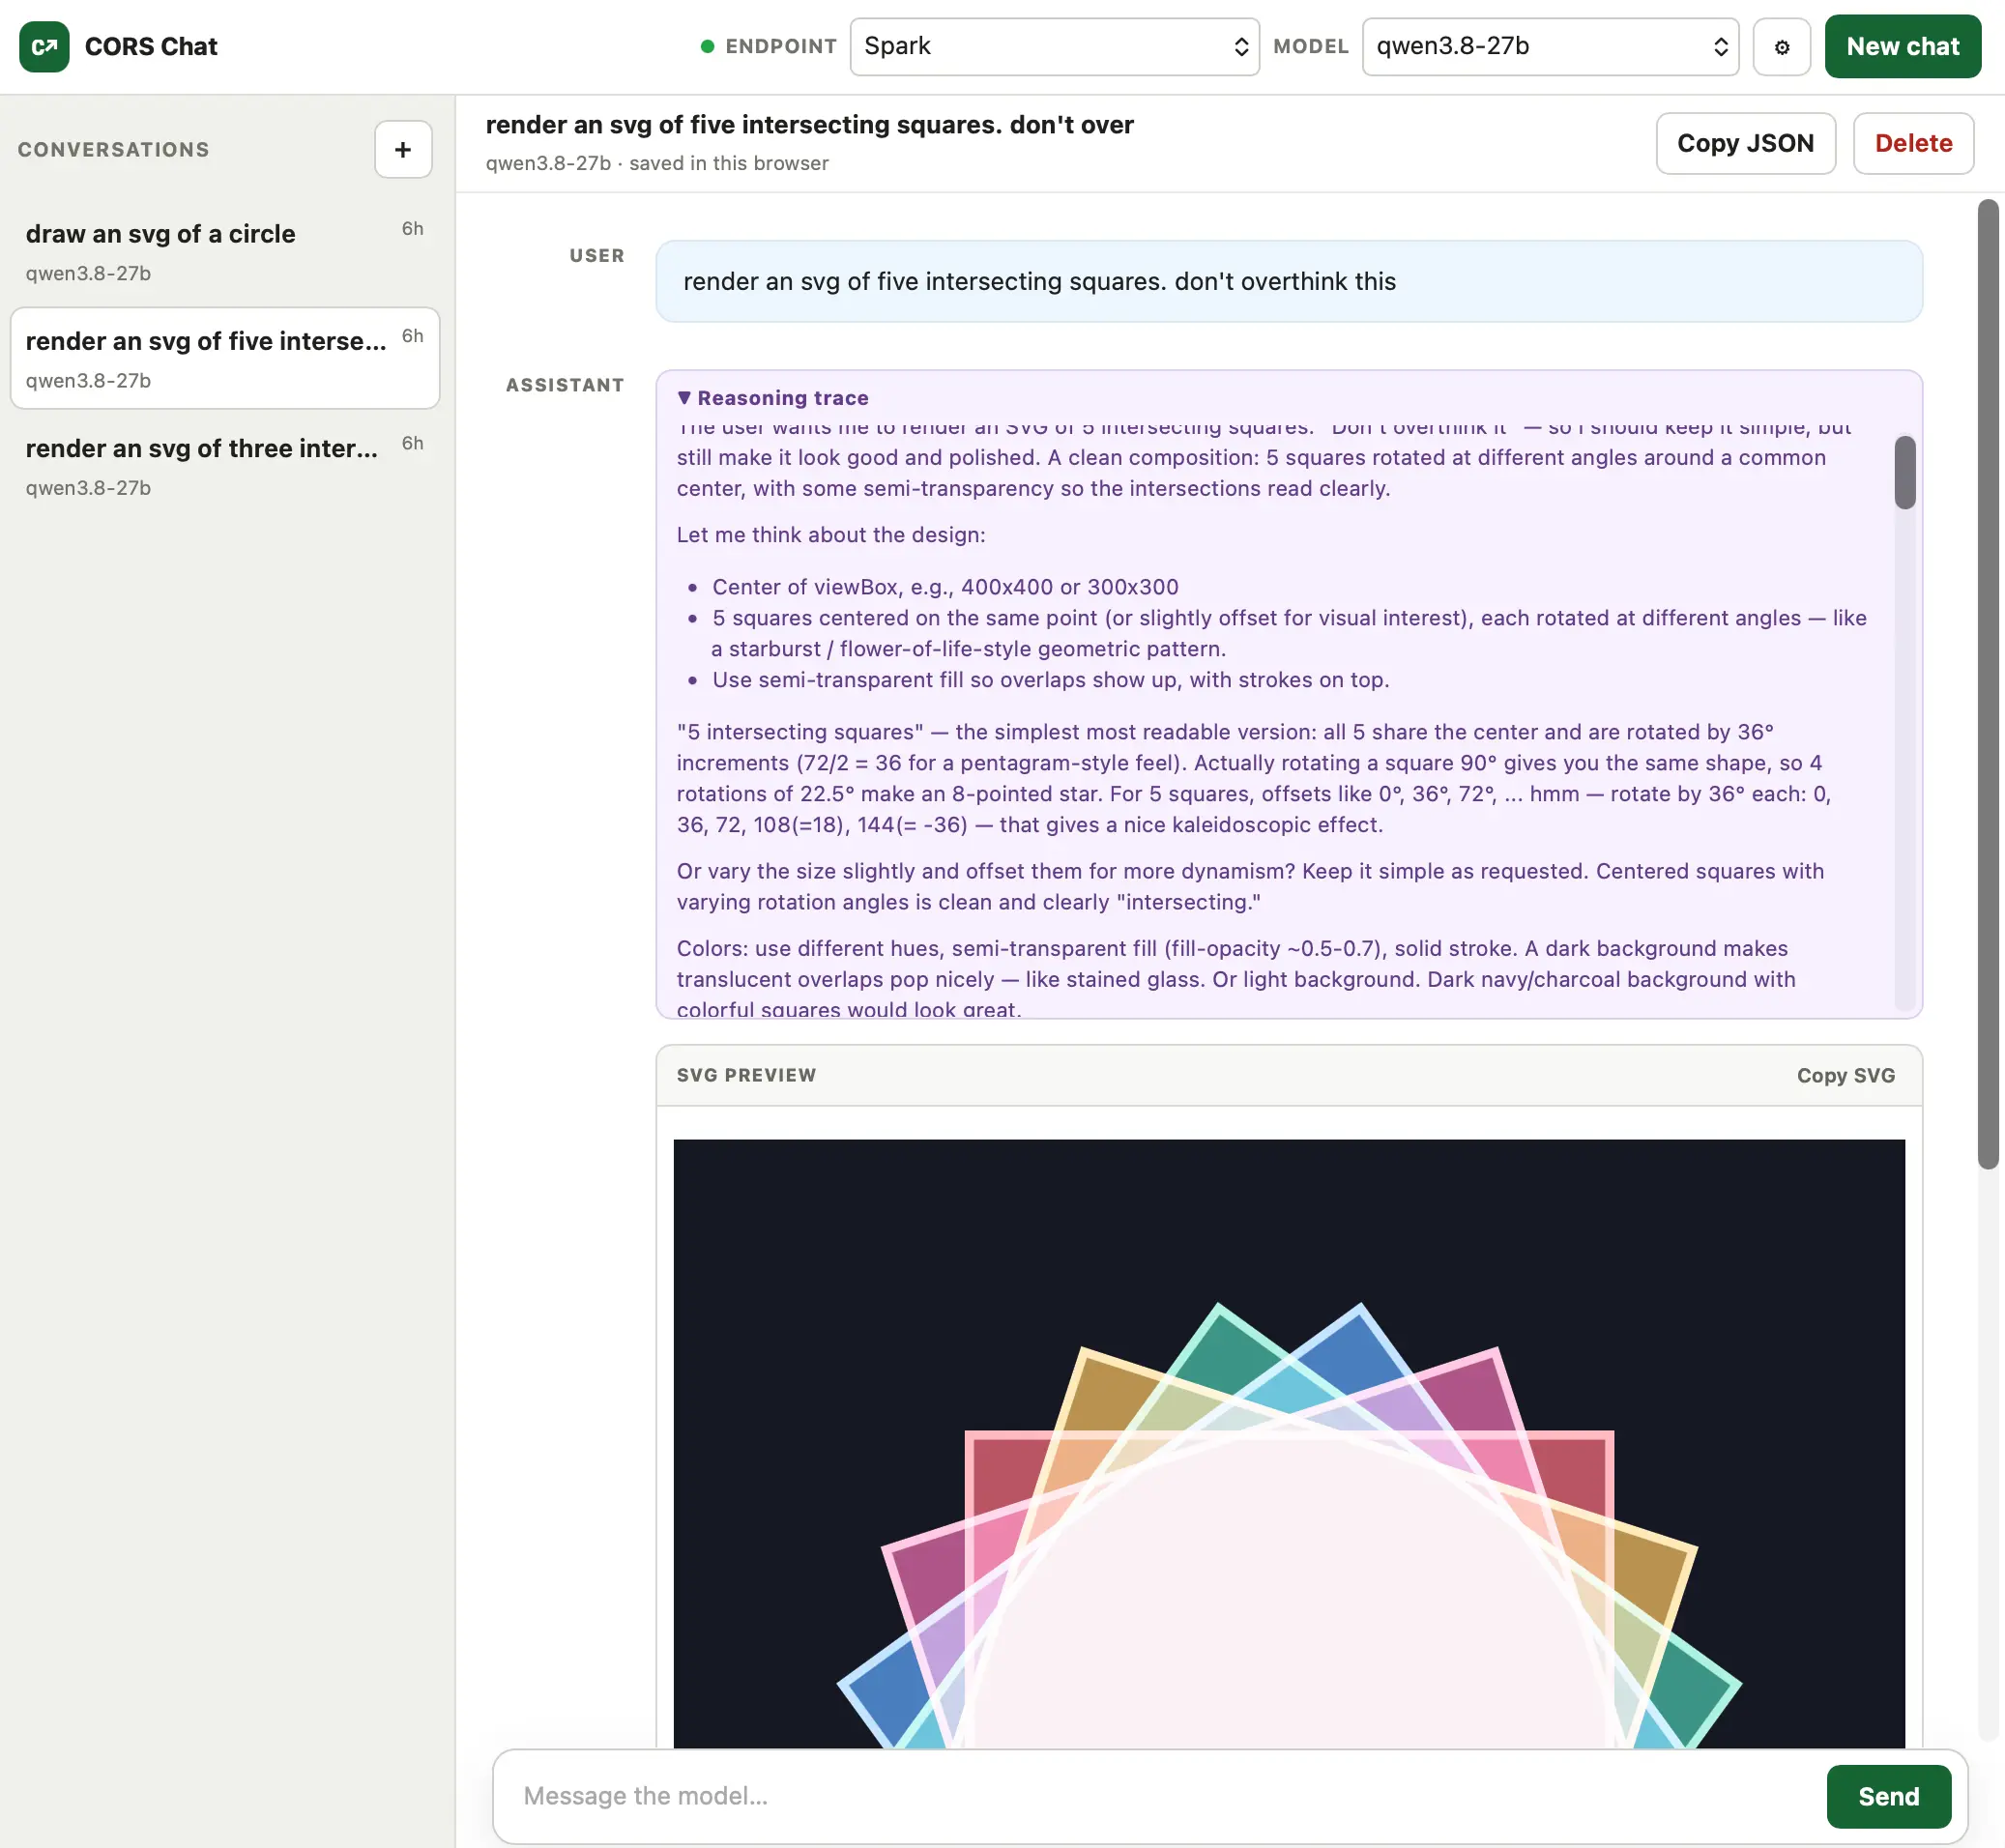
CORS Chat
Simon Willison's browser-based chat client for any OpenAI Responses-compatible endpoint that sends CORS headers, built to exercise local models in LM Studio and OpenRouter.
Why it mattersA zero-install way to exercise a Responses-compatible endpoint, including a locally served model, which removes the usual scratch-script step when validating a new provider or a local runtime.
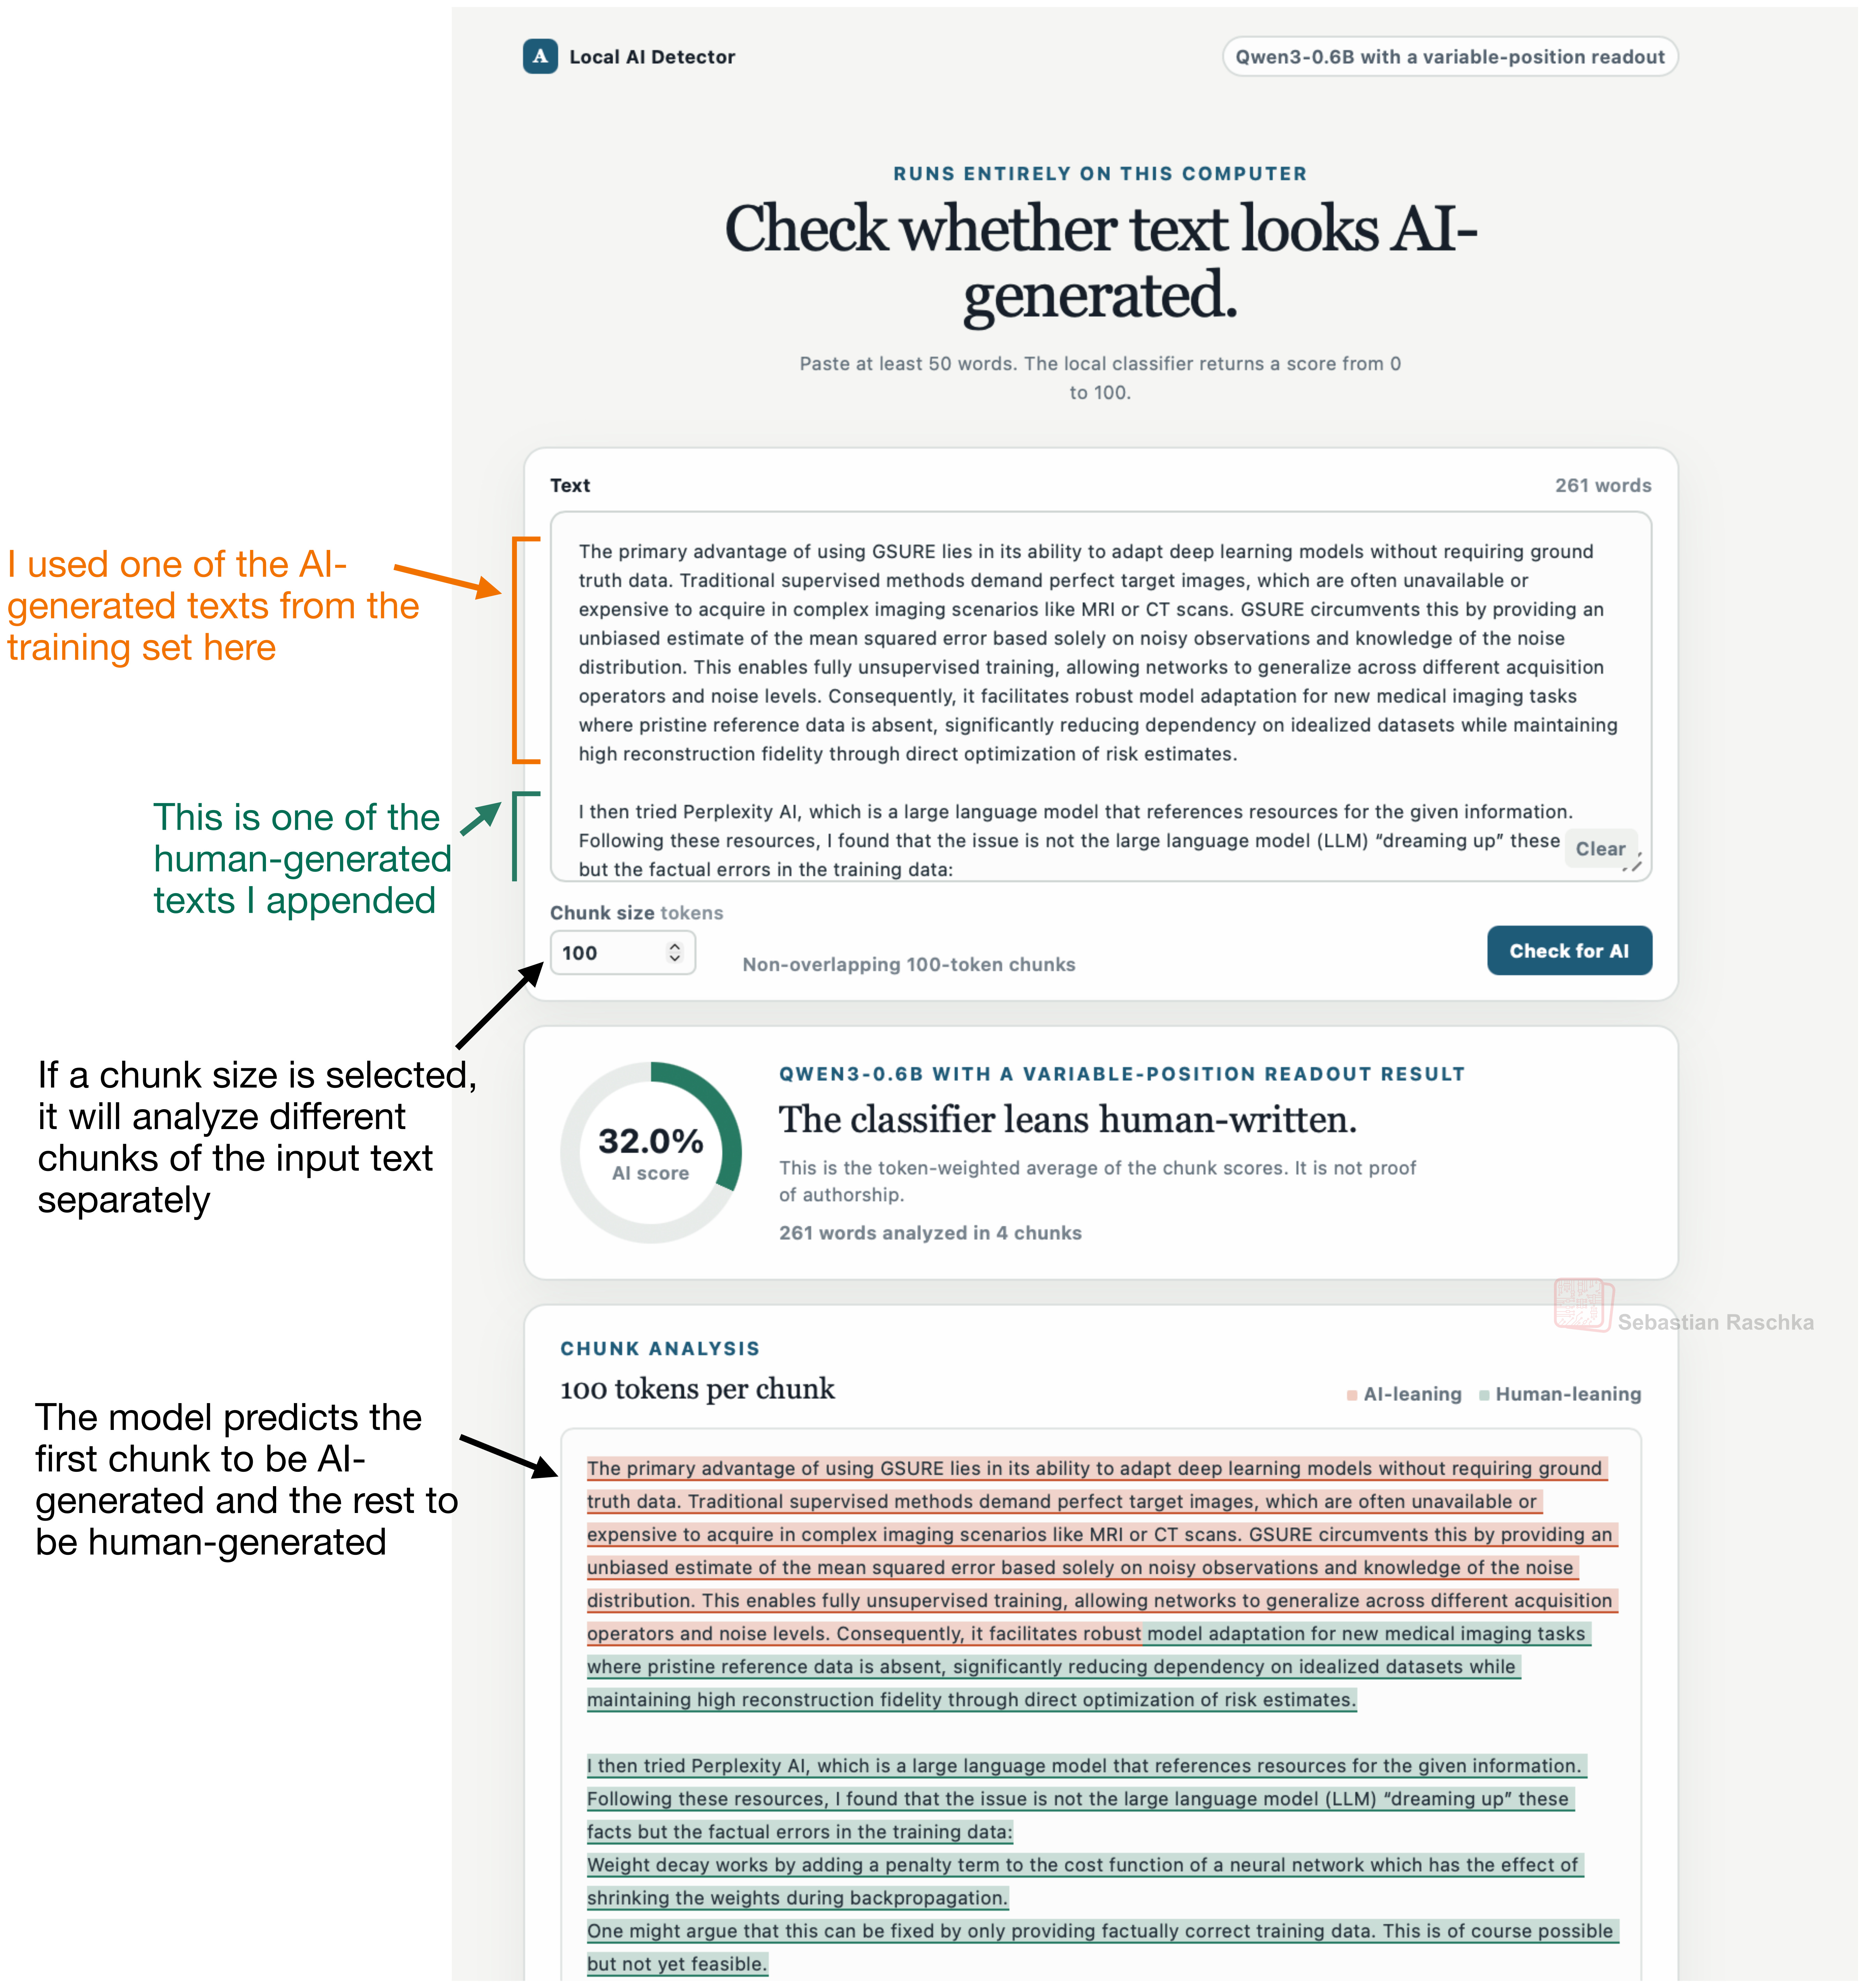
Building an AI Text Detector From Scratch
Sebastian Raschka builds a small AI-text detector from scratch, then turns it into a verifier used to train a small language model to write text that evades detection, as a study of where such detectors break down.
Why it mattersShows how to build a classifier-as-verifier and train an SLM against it, a reusable pattern for anyone wiring reward or filter signals into small-model training.

Voice agents with Realtime Video — Sidney Primas, LemonSlice
A production account of real-time video avatars.
Why it mattersAnyone building real-time multimodal agents gets the specific failure mode of long-running generated video and the fixes that keep an eight-hour session coherent.
Diagnostic Foundation for Evaluating LLMs' Research Integrity as Co-Scientists
IntegrityBench tests whether models uphold research integrity under institutional pressure across 36 paired tasks.
Why it mattersAnyone deploying models as autonomous research or review agents now has a measured failure rate under pressure, and evidence that scaling up the model does not fix it.
Research Assistant: AstraZeneca's Agentic System for R&D
AstraZeneca describes Research Assistant, an internal LLM system answering biomedical questions across literature, knowledge graphs, chemistry, clinical trials and internal experimental data.
Why it mattersPublished architecture and deployment lessons from a real enterprise agent system give builders a reference design for grounding, provenance, and mode selection.
Position: The Alignment Community is Unintentionally Building a Censor's Toolkit
An ICML oral argues that alignment methods are dual-use.
Why it mattersThe same machinery that suppresses harmful output is general-purpose output control — worth understanding if you ship alignment or moderation layers that a downstream operator could repurpose.
Don't Want Your LLM to Recommend Nuclear Strike? Try Asking It in Japanese
Nine models are asked in different languages whether a nuclear-armed state should strike a defenceless one.
Why it mattersSafety behavior measured only in English does not transfer, and reasoning-language is an uncontrolled variable in any multilingual agent deployment or eval suite.
Agreement Is Not Alignment: Divergent Moral Grounds in Human and LLM Ethical Judgments
Across frontier and open models on a 500-item ETHICS-derived set, final-label agreement with human annotators runs high while the stated justifications diverge.
Why it mattersHigh label agreement with human annotators can hide divergent underlying reasoning — if your eval only scores final answers, it is measuring less alignment than you think.
Dual-Flow Transformers: Decoupling the Primary Prefill Path from Additional Decode Computation
A transformer design that splits inference in two.
Why it mattersInference cost now dominates training cost for served models, and this decouples the two phases so added capability does not tax both.

Qwen3.8-27B is now packaged for LM Studio and needs roughly 17GB to run locally, putting a fresh open-weights release on consumer hardware without an API bill. Practitioners in the replies report multi-hundred-token/s prefill and long-context runs on Apple silicon.
Why it mattersQwen3.8-27B runs locally in about 17GB and is already packaged in LM Studio, putting a current-generation open-weights model within reach of a single well-specced laptop.
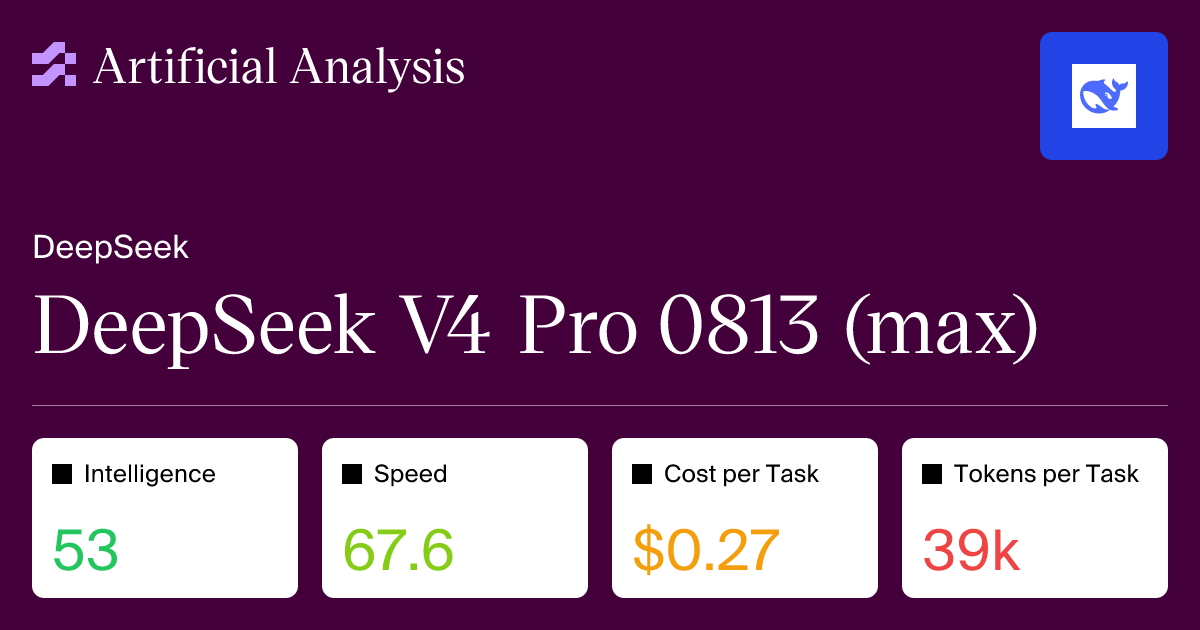
See Artificial Analysis for further details and benchmarks:
Artificial Analysis's evaluation of DeepSeek V4 Pro 0813.
Why it mattersDeepSeek V4 Pro 0813 lands near the top of the intelligence index but at 3.6x the prior price, scoring only a point above the far cheaper V4 Flash — the open-weights price/quality choice has shifted.

Artificial Analysis scores DeepSeek V4 Pro 0813 at 53 on its Intelligence Index, eight points above April's version but with a 3.6x price rise, leaving it barely ahead of the cheaper V4 Flash and still behind Kimi K3 among open-weights models.
Why it mattersTeams building on DeepSeek's first-party API face a 3.6x price change within a day, and the intelligence gain over the cheaper Flash model is a single point. The cost-per-task math changes which model is the rational default.

Hacktron's automated review found a high-severity NoSQL injection in Novu's codebase by tracing an unvalidated ID through an ingest controller, a type cast, and a sink service across three files.
Why it mattersHacktron's automated review caught a NoSQL injection in Novu by tracing an unvalidated event ID across three files, and fixed roughly half of flagged issues within 30 days with an 83% actionable rate.

SemiAnalysis lays out the cost case pulling hyperscalers to India: roughly $5M per MW of datacenter capex and power often under $0.10/kWh, cheap enough to put the country near 10GW by 2030 and among the four largest datacenter markets, with Microsoft alone committing $17.5B.
Why it mattersCompute capacity is migrating toward the cheapest power and capex, and India's sub-$0.10/kWh economics put it on track for roughly 10GW by 2030 — a factor in where inference gets served and what it costs.
An index of the vibe-coding frontier. Corrections welcome.