Intel
Page 105
A critique of code retrieval benchmarks: noisy labels, tasks that are too simple, and contamination risk. Voyage proposes building evaluation sets by repurposing QA datasets and mining issue and ticket records, then scores OpenAI, CodeSage, CodeRankEmbed, Jina, and voyage-code-3 on them.
Why it mattersIf you choose a code embedding model from public benchmarks, this names the flaws in those datasets and gives two reproducible ways to build evaluation sets from your own QA data and issue history.
Creativity As Search Mapping Latent Space
Runway prototypes video keyframing as graph navigation.
Why it mattersFraming generation as search over latent space and giving it a data structure, with nodes as waypoints, video transitions as edges.
Reward Hacking in Reinforcement Learning
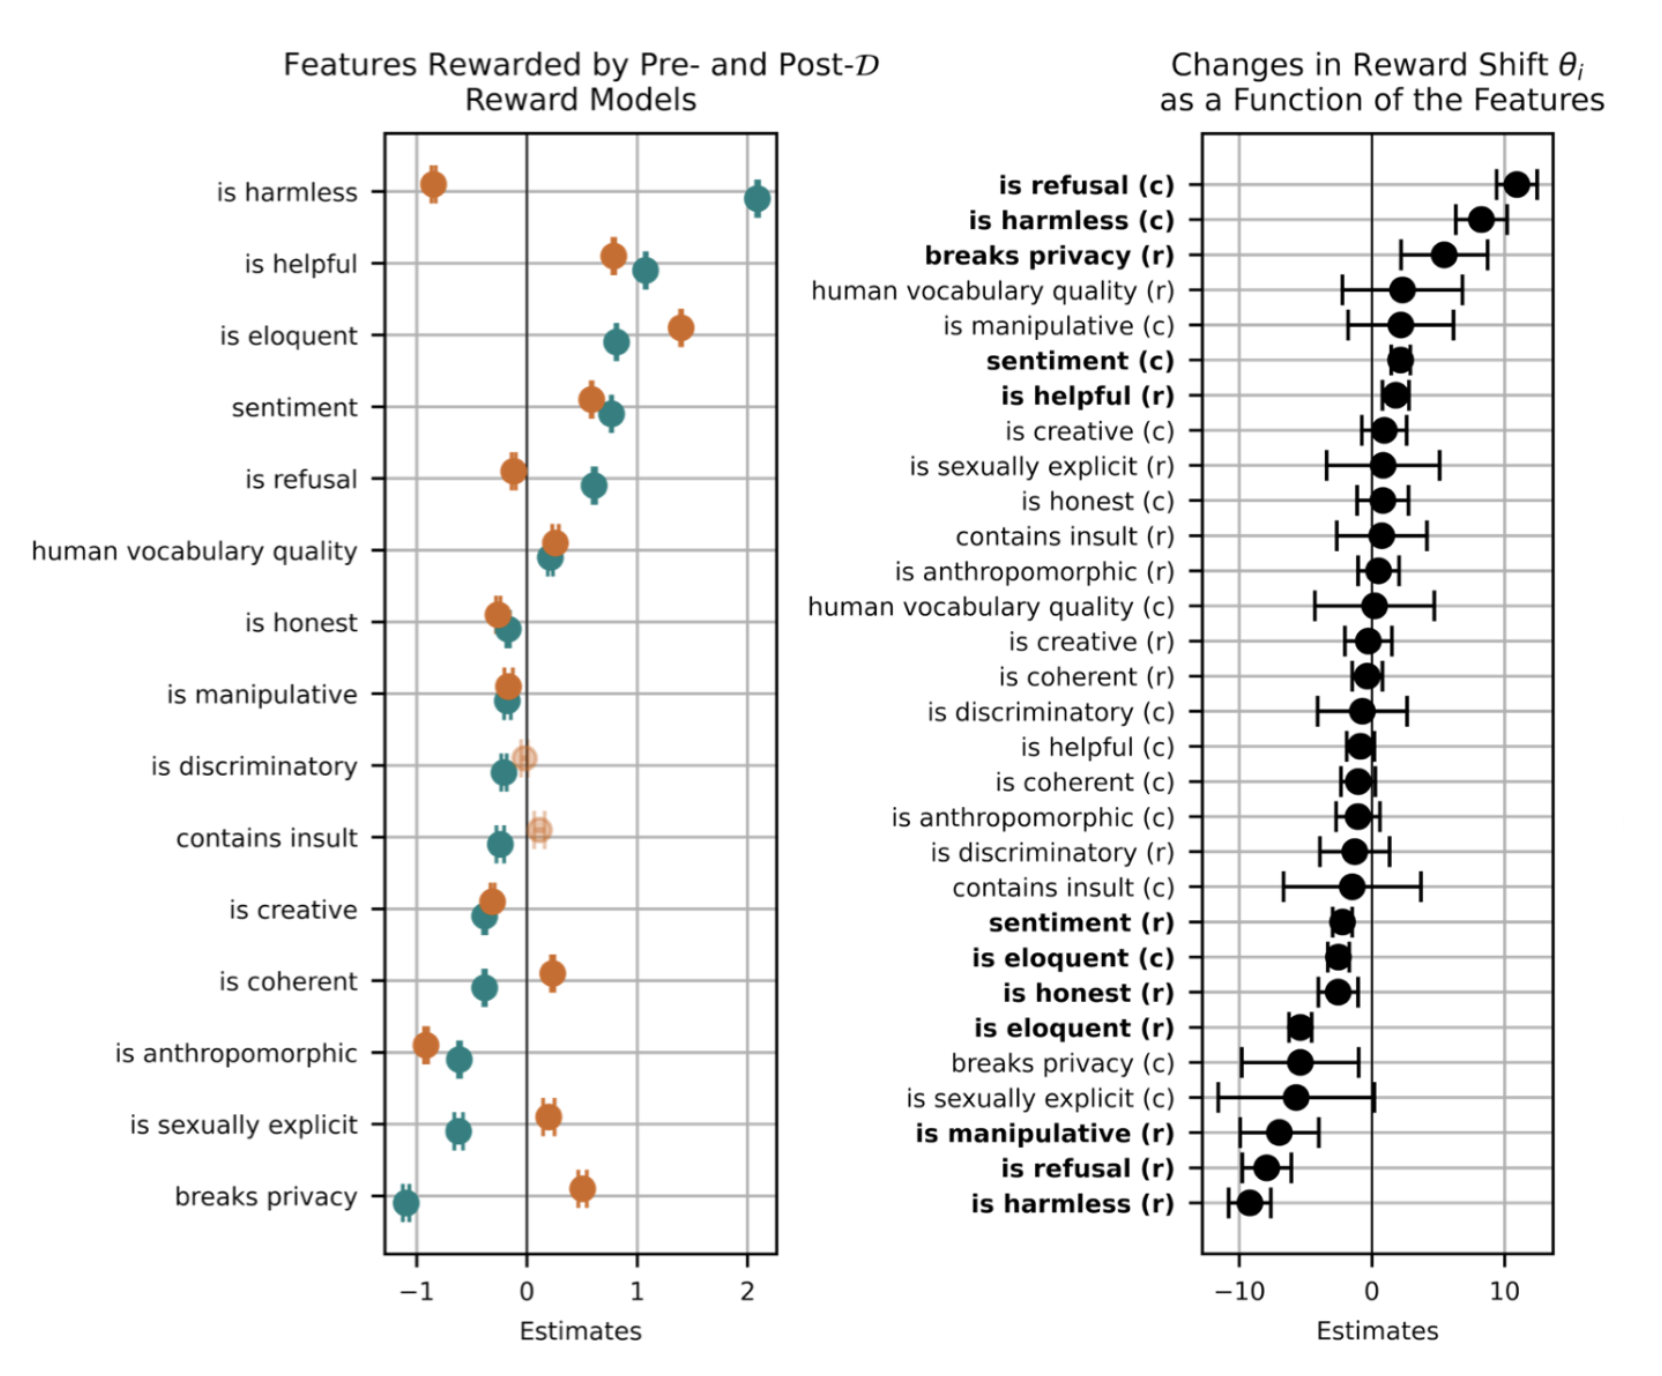
Reward hacking is an agent exploiting flaws in a reward function to score well without doing the task.
Why it mattersIf you're doing RLHF or RL fine-tuning of language models, this explains how agents exploit reward-function flaws — modifying unit tests to pass coding tasks, sycophantically mirroring user preferences.
QwQ: Reflect Deeply on the Boundaries of the Unknown
QwQ, Qwen with Questions, is a reasoning model that approaches maths, code and general knowledge by working through uncertainty rather than answering directly.
Why it mattersQwQ is an openly available reasoning model that surfaces its self-questioning chain-of-thought, giving engineers a locally-runnable alternative to closed reasoning models for math, code, and analytical tasks.
Consent In Crisis The Rapid Decline Of The Ai Data Commons 2024 07 19
An audit of web crawling permissions across C4, RefinedWeb and Dolma, tracking how quickly site owners have moved to restrict AI crawlers.
Why it mattersThe open web corpora underneath pretraining are being fenced off through robots.txt and terms changes. A shrinking permission surface constrains what future open datasets and models can legitimately be built on.
Understanding And Mitigating Language Confusion In Llms 2024 06 28
Cohere Labs builds the Language Confusion Benchmark around a failure that shows up in real multilingual deployments.
Why it mattersIf you serve non-English users, this quantifies how often models drift back to English or mix scripts, and which prompting and training choices cut it down.
Mteb Massive Text Embedding Benchmark 2023 03 19
The benchmark behind the embedding leaderboard most teams use when picking a model.
Why it mattersChoosing an embedding model on one retrieval score can mislead you. MTEB is the multi-task evaluation behind the public embedding leaderboard, letting you compare candidates on the task family your product actually runs.
Procedural Knowledge In Pretraining Drives Reasoning In Large Language Models 2024 11 20
Influence-function work from Cohere Labs on where reasoning ability comes from.
Why it mattersReasoning behavior traces back to documents that demonstrate a method, not documents holding the answer. That changes where to look when curating training data or explaining why a model generalizes on some tasks and memorizes others.
The Data Provenance Initiative A Large Scale Audit Of Dataset Licensing And Attribution In Ai 2023 10 25
A systematic audit of popular finetuning collections, tracing each dataset back to its original source, creator, and license.
Why it mattersLicense metadata on widely used finetuning datasets is often absent or incorrect, so a team that trusts the tag shown on a dataset hub can inherit commercial-use risk it never checked.
Language Models Don T Always Say What They Think Unfaithful Explanations In Chain Of Thought Prompting 2023 05 07
Step-by-step reasoning output can read as a plausible account while misstating what actually produced the answer.
Why it mattersIf you log agent reasoning traces to audit or debug decisions, treat them as generated text rather than ground truth. Stated steps can diverge from the factors actually driving the output.
Introducing Frames
Runway's image base model, since folded into Gen-4 Images, is pitched at stylistic lock-in.
Why it mattersFrames became Gen-4 Images and is reachable through the Runway API, targeting repeatable house style across a project rather than one-off prompt quality.
Extending the Context Length to 1M Tokens!
Qwen2.5-Turbo extends context to one million tokens, following community demand after Qwen2.5.
Why it mattersQwen2.5-Turbo pushes usable context to ~1M tokens (roughly a million English words), enabling whole-codebase or multi-document reasoning in a single call without chunking or RAG workarounds.
Voyage AI's first multimodal embedding model processes interleaved text and images inside a single transformer rather than through CLIP-style separate networks, reporting a 19.63% average gain across 20 datasets and steady accuracy as the share of screenshots in a corpus rises.
Why it mattersEmbedding a document screenshot directly removes layout analysis and text extraction from the pipeline, and the unified encoder avoids the accuracy drop dual-encoder models show on mixed text and image corpora.
#452 – Dario Amodei: Anthropic CEO on Claude, AGI & the Future of AI & Humanity
Qwen2.5-Coder Series: Powerful, Diverse, Practical.
The Qwen2.5-Coder series opens as powerful, diverse and practical, with the 32B instruct variant matching GPT-4o's coding ability as the strongest open code model at release.
Why it mattersQwen2.5-Coder-32B-Instruct is a SOTA open-weight code model that rivaled GPT-4o coding performance, with a diverse size range (0.5B to 32B) letting you run local coding assistants sized to your hardware.
How Recraft V3 learned to render longer text
In a Nov. 2024 engineering post, Recraft explains the OCR, layout-generation, and ControlNet-like conditioning pipeline it built to improve text rendering in V3.
Why it mattersRecraft’s post argues for explicit typography layout as a conditioning signal. It reported a first-place Elo score in Nov. 2024, but did not provide a text-specific benchmark or ablation.
Fine Tune Claude 3 Haiku
Fine-tuning came to Claude 3 Haiku in Amazon Bedrock.
Why it mattersClaude 3 Haiku can be fine-tuned on your own prompt and completion pairs inside Amazon Bedrock, which is the supported way to encode domain knowledge into the cheapest, fastest model instead of carrying it in every prompt.
Using LLM-as-a-Judge For Evaluation: A Complete Guide
A practical guide to using a model as a judge, drawn from setting up evaluation systems at more than 30 companies, and the mistakes teams repeat when they try it.
Why it mattersA step-by-step methodology for building trustworthy LLM-as-a-judge systems, replacing arbitrary 1-5 scoring with 'Critique Shadowing' that anchors evals to a single domain expert's judgment.
The Tech Behind The First Agent From Linkedin Hiring Assistant
LinkedIn describes the architecture behind Hiring Assistant, its first production agent.
Why it mattersA shipped agent design where per-user experiential memory, not a larger prompt, carries recruiter feedback across sessions in a multi-step sourcing workflow.
AlignEval: Building an App to Make Evals Easy, Fun, and Automated
Look at and label your data, build and evaluate your LLM-evaluator, and optimize it against your labels.
Why it mattersIf you're building LLM-as-judge evaluators, this walks through a practical loop for labeling data and optimizing your evaluator against those labels — grounding eval quality in human-aligned measurement rather than vibes.
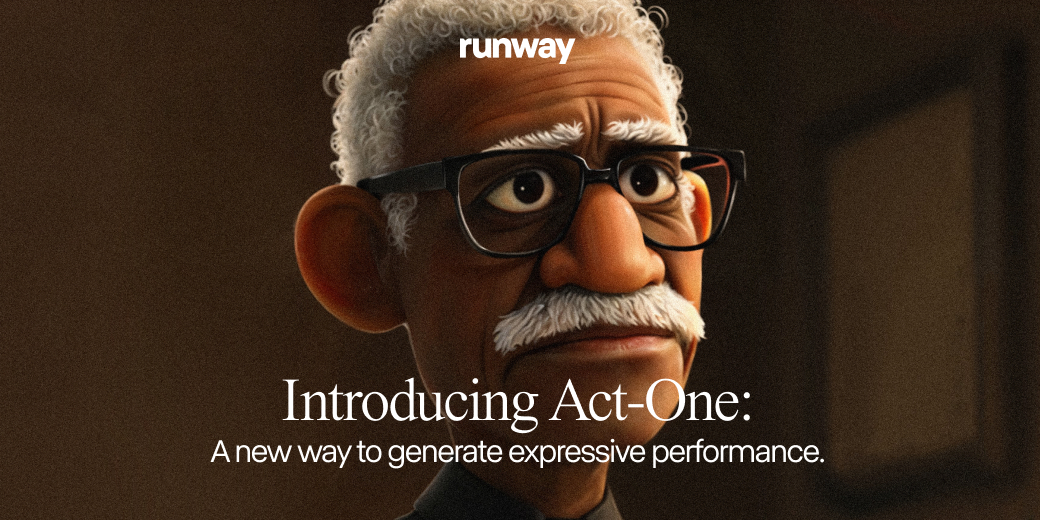
Introducing Act One
Act One animates generated characters directly from phone-grade video of a performance, preserving eye-lines, micro-expressions, and delivery.
Why it mattersFacial performance transfer from one camera and one actor collapses a mocap-and-rigging pipeline into a single model call, and holds up across characters with proportions unlike the source.
How Shopify Improved Consumer Search Intent With Real Time Ml
How Shopify runs semantic storefront search.
Why it mattersA concrete architecture for keeping embeddings fresh at scale — shared embedding primitives plus streaming inference — which is the hard part of shipping semantic search that batch reindexing quietly hides.

Announcing Our Updated Responsible Scaling Policy
Anthropic's revised risk framework sets capability thresholds that trigger stronger ASL safeguards, adopts safety case methodology for judging whether protections are adequate.
Why it mattersDefines the capability thresholds and matching safeguard standards that determine when Anthropic adds deployment restrictions to a model, which is the machinery behind access limits and safeguards on later frontier releases.
Machines of Loving Grace: How AI Could Transform the World for the Better
An essay by Anthropic CEO Dario Amodei arguing that despite his company's focus on AI risk, powerful AI could bring radical positive transformation across five domains.
Why it mattersOffers a rare detailed, domain-by-domain articulation of AI's upside from a leader whose company is otherwise known for risk-focused messaging, useful context for engineers navigating the discourse shaping frontier AI development priorities.
Foundations For Safe Generative Media
Runway publishes the measured performance of its own visual moderation model against third-party APIs, reporting better F1 and recall at half the false-positive rate, alongside the diversity fine-tuning it uses to keep profession prompts off default demographics.
Why it mattersGives real comparison numbers for in-house visual moderation versus third-party APIs, including the false-positive tradeoff anyone shipping a generative media product has to price in.
Reka Flash Updates
Reka Flash's update adds arbitrary-resolution image handling with stronger OCR and structured output, native audio understanding inside video, 3-5 minute clips instead of one.
Why it mattersInterleaved image, video and audio input in one 21B model at 128K context, with video length up from 1 minute to 3-5 and structured-output support, enough to build video retrieval and segment-summarisation flows on.
AI GPU Clusters, From Your Laptop, With Livebook
How three Elixir pieces — Livebook notebooks, FLAME's elastic executor pools, and the Nx/Axon tensor stack.
Why it mattersShows a concrete path to running GPU ML workloads from a local notebook by marking code with Flame.call and letting a pool of remote executors scale to zero — Elixir-native inference without splitting the app into serverless pieces.
Introducing Contextual Retrieval
Introducing Contextual Retrieval
Why it mattersIf you're building RAG pipelines, Contextual Retrieval shows how prepending chunk-specific context before embedding (and BM25 indexing) cuts retrieval failures substantially over naive chunking.
Qwen2.5: A Party of Foundation Models!
Qwen2.5 arrives as what the team calls possibly the largest open-source release in history, a family of foundation models built on three months of developer feedback since Qwen2.
Why it mattersQwen2.5 is one of the largest open-weight model releases available, spanning many parameter sizes with strong coding and reasoning gains — useful when you need capable, self-hostable alternatives to closed frontier APIs.
Qwen2.5-LLM: Extending the boundary of LLMs
Qwen details the Qwen2.5 language model series.
Why it mattersQwen2.5 gives you a full ladder of open-weight models (0.5B to 72B) with sizes deliberately tuned for production (10-30B) and mobile (3B) deployment.
Qwen2.5-Coder: Code More, Learn More!
Qwen2.5-Coder is the next generation of Qwen's open code models, renaming CodeQwen to Qwen-Coder and building on the CodeQwen1.5 release from earlier that year.
Why it mattersQwen2.5-Coder is a strong open-weight coding model family that can power self-hosted coding agents and IDE tooling without relying on closed APIs, giving engineers a competitive local alternative to GPT/Claude for code generation.
Qwen2.5-Math: The world's leading open-sourced mathematical LLMs
Qwen2.5-Math open-sources 1.5B, 7B and 72B base and instruct models for mathematical reasoning in English and Chinese through chain-of-thought and tool-integrated reasoning.
Why it mattersQwen2.5-Math offers open-weight math-specialized models (1.5B/7B/72B) that combine chain-of-thought and tool-integrated reasoning plus a dedicated reward model.
Introducing The Runway Api
Runway shipped its first public API, exposing the Gen-3 Alpha Turbo video model for integration into third-party products.
Why it mattersGen-3 Alpha Turbo became reachable programmatically rather than only through Runway's own editor, opening generative video as a backend call inside another product. Initial access was partner-gated with a broader opening promised.
Multimodal With Reka Mongodb
A walkthrough of why text-first RAG stalls on charts, tables and PDFs, and why CLIP-style embeddings do not rescue it.
Why it mattersGeneric image embeddings can separate a cat from a dog but not two tables in a financial report; converting charts and tables to markdown before indexing is a workable route to retrieval over multimodal documents.
A New Initiative For Developing Third Party Model Evaluations
Anthropic opened funding for third-party evaluations and, in doing so, mapped where it thinks the eval landscape falls short.
Why it mattersNames the eval categories a frontier lab considers undersupplied, including CTF-style cyber tasks without published solutions and autonomy benchmarks tied to junior through expert research engineer levels, with funding attached.
Projects
Claude Pro and Team gained Projects.
Why it mattersProjects attach a persistent 200K token corpus and custom instructions to a set of conversations, so grounding documents and role framing no longer get re-pasted into every chat.
Updating Our Usage Policy
Anthropic's Acceptable Use Policy became the Usage Policy effective June 6, 2024.
Why it mattersChanges what you may build on the API: high-risk healthcare and legal integrations take on extra safety requirements, products serving minors need disclosure and safeguards, and political campaigning uses are spelled out as prohibited.
Model Safety Bug Bounty
An invite-only HackerOne program aimed at universal jailbreaks, paying up to $15,000, tested against a next-generation safeguard system that has not shipped publicly.
Why it mattersPays up to $15,000 for universal jailbreaks and gives selected researchers access to an unreleased safety mitigation system before public deployment.
Expanding Access To Claude For Government
Anthropic placed Claude 3 Haiku and Sonnet in AWS GovCloud and the AWS Marketplace for the US Intelligence Community, paired with contractual Usage Policy exceptions for legally authorized foreign intelligence analysis.
Why it mattersClaude became deployable in AWS GovCloud and the Intelligence Community marketplace.
Qwen2-VL: To See the World More Clearly
Qwen2-VL is the vision-language release in the Qwen2 family.
Why it mattersQwen2-VL delivers state-of-the-art visual understanding across variable image resolutions and can reason over 20+ minute videos, making it a strong open option for document parsing, visual QA.
Evaluating the Effectiveness of LLM-Evaluators (aka LLM-as-Judge)
Use cases, techniques, alignment, finetuning, and critiques against LLM-evaluators.
Why it mattersIf you're building LLM-as-Judge evaluators, this breaks down alignment techniques, finetuning approaches, and the concrete failure modes of using LLMs to grade LLMs.
We're Cutting L40S Prices In Half
Fly halves L40S GPU pricing to $1.25/hour and explains the demand picture behind it.
Why it mattersL40S GPU hours drop to $1.25, and the provider's own demand data shows cheaper A10s dominate because they handle mid-sized generative workloads like Mistral Nemo and Stable Diffusion well enough.
Qwen2-Audio: Chat with Your Voice!
Qwen2-Audio extends the Qwen family to audio.
Why it mattersQwen2-Audio is an open multimodal model that natively accepts audio and text and returns text, enabling voice chat and audio analysis without stitching together a separate speech-to-text pipeline.
Scaling LLM Test-Time Compute Optimally can be More Effective than Scaling Model Parameters
Showed compute spent at inference can outperform compute spent on a larger model, and that how best to spend it shifts with the difficulty of the prompt.
Why it mattersThe result behind reasoning models: for many problems letting a smaller model think longer beats training a larger one, and the optimal strategy shifts with prompt difficulty.
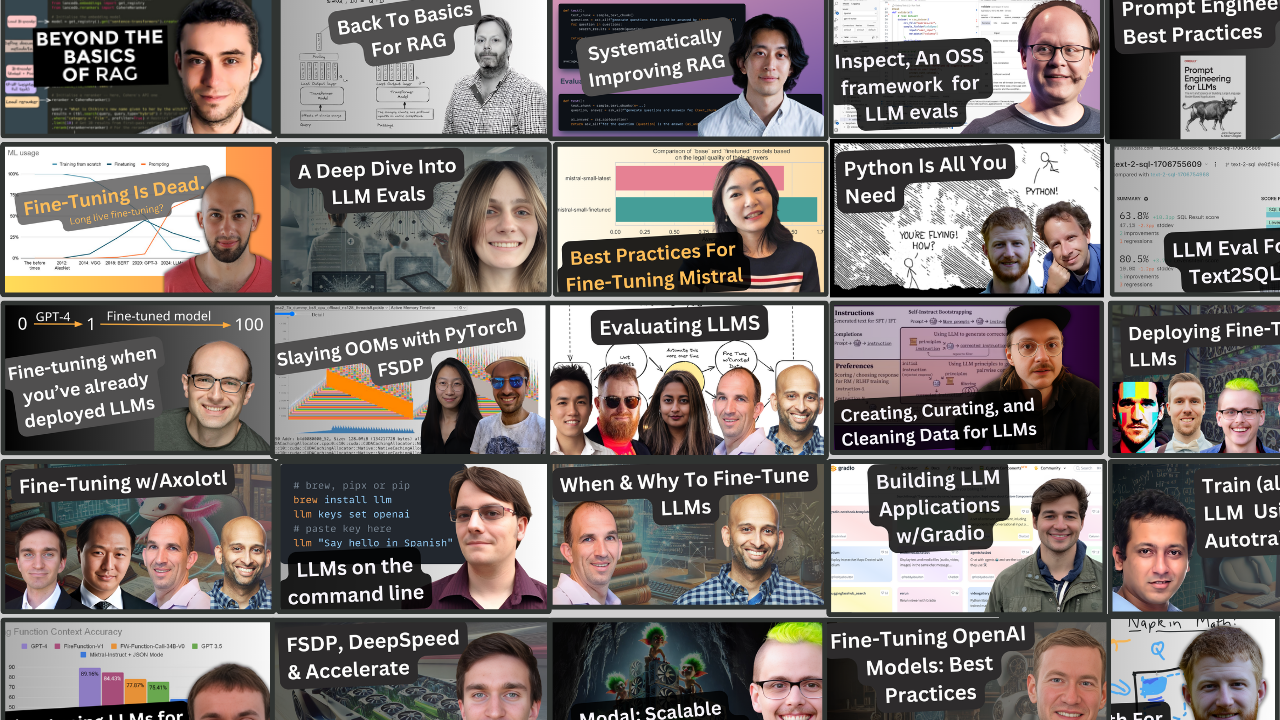
An Open Course on LLMs, Led by Practitioners
Mastering LLMs, an open course of workshops and talks from 25-plus practitioners covering evals, retrieval-augmented generation and fine-tuning.
Why it mattersA free, well-organized 40+ hour course distilled from a popular paid program, with annotated talks and notes from practitioners across evals, RAG, and fine-tuning — a fast way to level up on shipping real LLM products rather than toy demos.
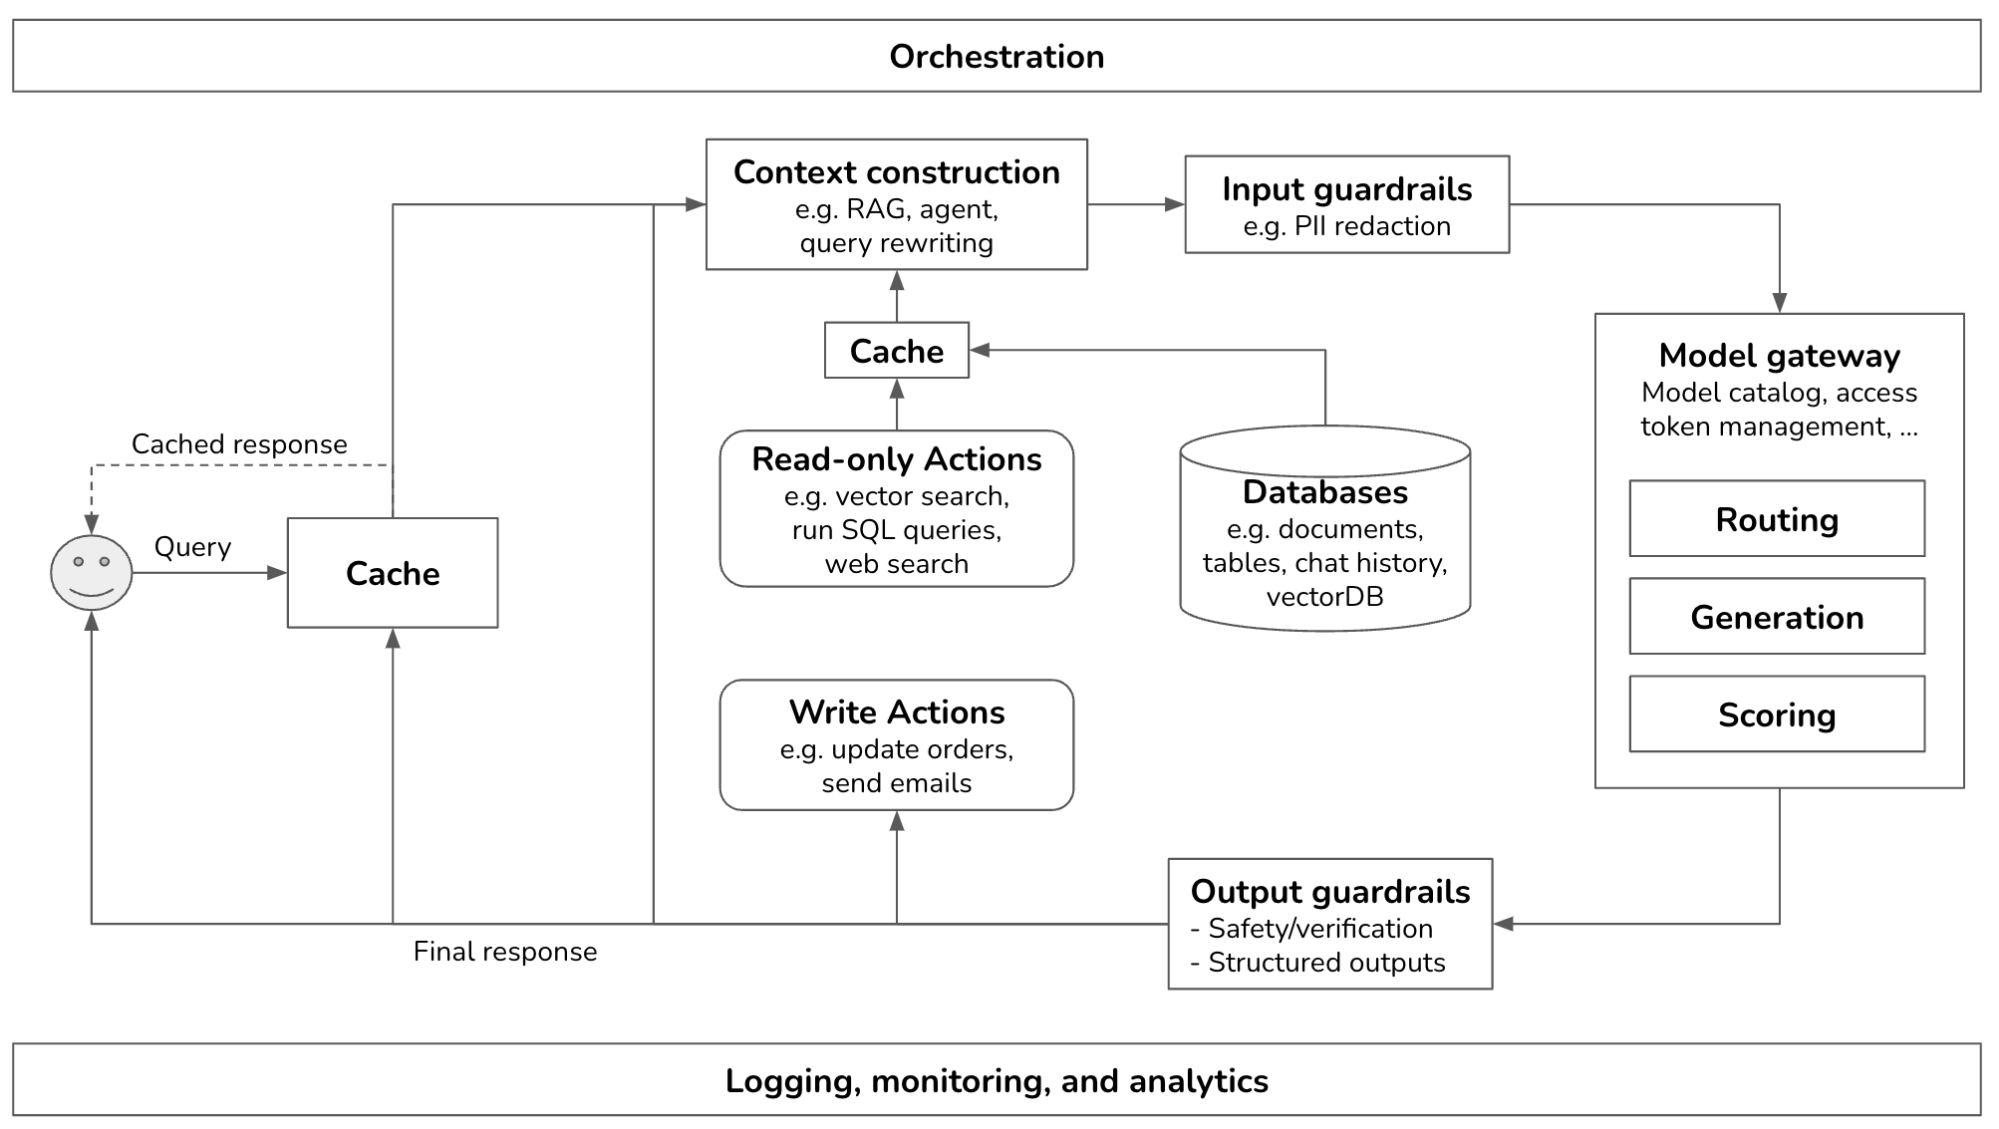
Building A Generative AI Platform
The components that recur across generative AI platforms once you look at how companies actually deploy them, built up from the simplest possible architecture rather than presented as a finished diagram.
Why it mattersA clear, incrementally-built reference architecture for production genAI systems — showing when and why to add RAG, guardrails, model gateways, caching, and orchestration.
Extrinsic Hallucinations in LLMs
Narrowing hallucination to its useful meaning: output that is fabricated and grounded in neither the provided context nor world knowledge, rather than any mistake a model makes.
Why it mattersIt gives a precise taxonomy of hallucination (in-context vs. extrinsic) and surveys the actual detection and mitigation methods.
AI Engineer 2024 Keynote - What We Learned from a Year of LLMs
Special double-feature closing keynote from the 6 authors of the hit O'Reilly article on Applied LLMs.
Why it mattersA concentrated set of production LLM lessons from six practitioners covering evals, prompting, RAG vs. fine-tuning tradeoffs, and operational pitfalls—useful if you're moving an LLM feature from demo to reliable product.
Introducing Gen 3 Alpha
Runway's Gen-3 Alpha, the first model on their new multimodal training infrastructure, improves fidelity, motion and photorealistic human generation over Gen-2 and powers text-to-video, image-to-video and control modes including motion brush and camera direction.
Why it mattersTraining on temporally dense captions gives fine-grained control over when things happen in a shot, enabling keyframed transitions and expressive human performance the prior generation could not sustain.
Voyage AI released a multilingual embedding model reporting an average 5.6% gain across evaluated languages including French, German, Japanese, Spanish and Korean, with a 32K context window and availability through the AWS Marketplace.
Why it mattersA multilingual retrieval option with a 32K context, useful when your corpus is not English and current embeddings degrade on it.
An index of the vibe-coding frontier. Corrections welcome.