Intel
Page 130Evaluating Success Of Consumer Generative Ai Products
LinkedIn lays out how it measures whether shipped generative AI features are working.
Why it mattersGives a concrete three-layer scheme for judging an LLM feature in production, separating output quality, perceived quality, and whether the feature actually gets used, so launch decisions do not rest on a single ambiguous metric.
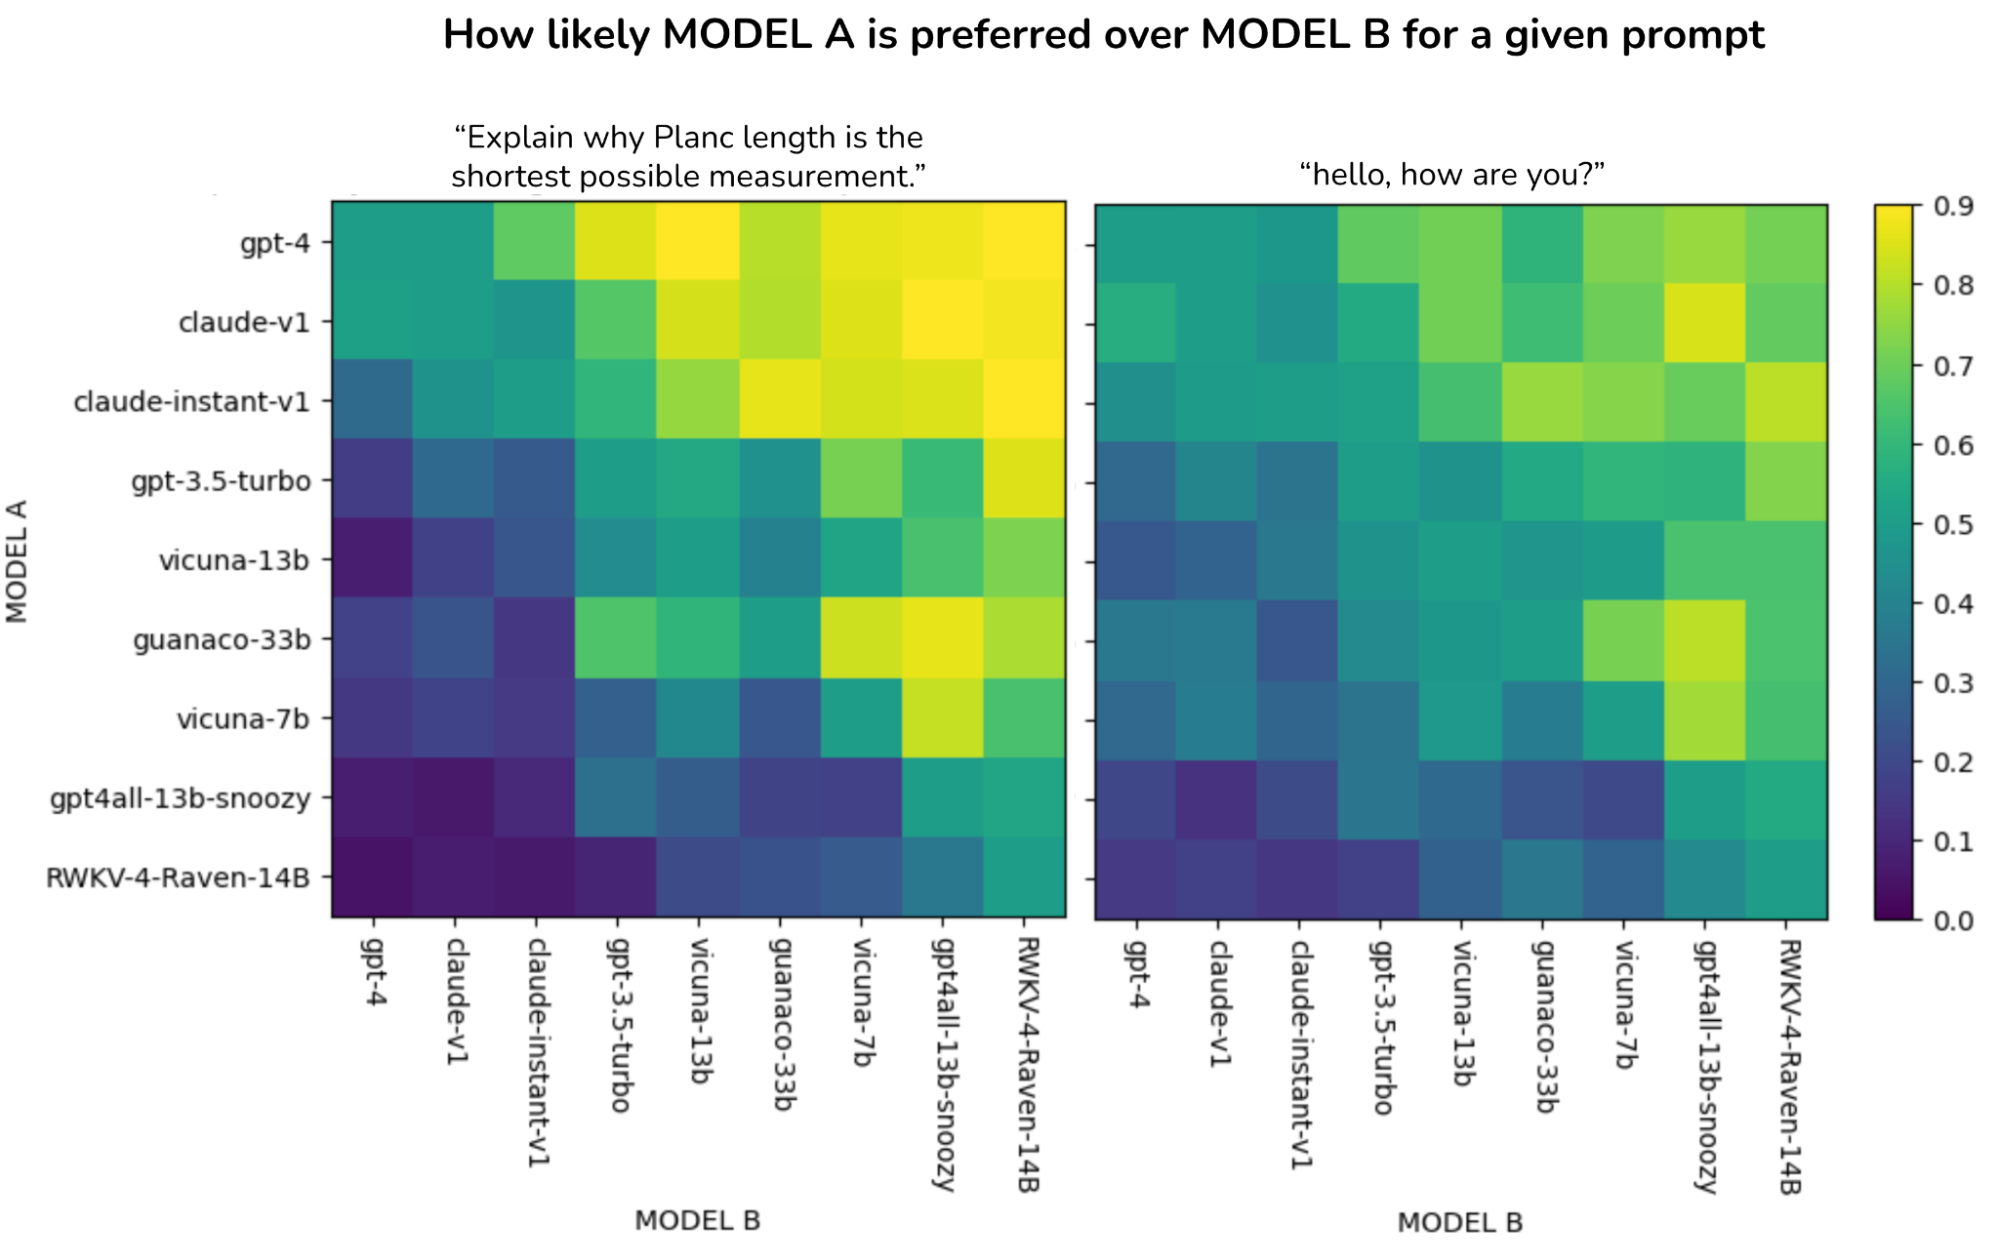
Predictive Human Preference: From Model Ranking to Model Routing
Instead of ranking models and picking one, predict which model a user would prefer for a specific prompt, turning human preference data from a leaderboard into a routing signal.
Why it mattersIf you're deciding which LLM to call for each prompt, this lays out how to predict which model a user will prefer per-query and route accordingly.
Don't Mock Machine Learning Models In Unit Tests
How unit testing machine learning code differs from typical software practices
Why it mattersIf you write tests for ML pipelines, this explains why mocking models hides real failures and what to validate instead — practical guidance for keeping AI code reliable as it evolves.
Open Sourcing Flyteinteractive
LinkedIn open-sourced FlyteInteractive, a layer over Flyte that gives engineers a live environment inside the Kubernetes pod running their training job.
Why it mattersDebugging ML jobs against small mock datasets hides failures that only appear on real data at scale. Attaching an interactive session to the production-like pod closes that gap and shortens the debug loop sharply.
Reka Flash Efficient And Capable Multimodal Language Models
Reka Flash is a 21B multimodal model trained from scratch, benchmarked against Gemini Pro and GPT-3.5 on MMLU, GPQA, HumanEval and vision/video suites.
Why it mattersA 21B model competitive with Gemini Pro and GPT-3.5 across language and vision benchmarks, plus a 7B variant for on-device use, offering a size/quality point worth considering when picking a multimodal backbone.
How to Generate and Use Synthetic Data for Finetuning
Overcoming the bottleneck of human annotations in instruction-tuning, preference-tuning, and pretraining.
Why it mattersIf you're finetuning models and blocked by the cost of human annotation, this walks through concrete synthetic data generation strategies for instruction-tuning, preference-tuning, and pretraining.
Building A Large Scale Recommendation System People You May Know
LinkedIn walks through the multi-stage funnel behind People You May Know, scoring hundreds of billions of candidate pairs daily under latency budgets.
Why it mattersA working blueprint for serving retrieval over billion-item inventories: cheap candidate generation first, expensive models only on a narrowed funnel, and scoring rather than training treated as the real scaling limit.
Thinking about High-Quality Human Data
Most task-specific labelled data comes from human annotation, which makes annotator disagreement, expertise and incentives a modelling problem rather than an operational detail.
Why it mattersA deep dive into the mechanics of high-quality human annotation and RLHF labeling — covering rater agreement, aggregation, and quality-control techniques that directly affect the data your alignment and fine-tuning pipelines depend on.
Pensieve
LinkedIn's Pensieve platform pre-computes entity embeddings offline and nearline, then publishes them as features for ranking models that cannot afford forward-pass latency.
Why it mattersShows how to keep embedding-based ranking inside tight latency budgets by moving inference to nearline pre-computation and publishing embeddings as features, instead of running the model on the request path.
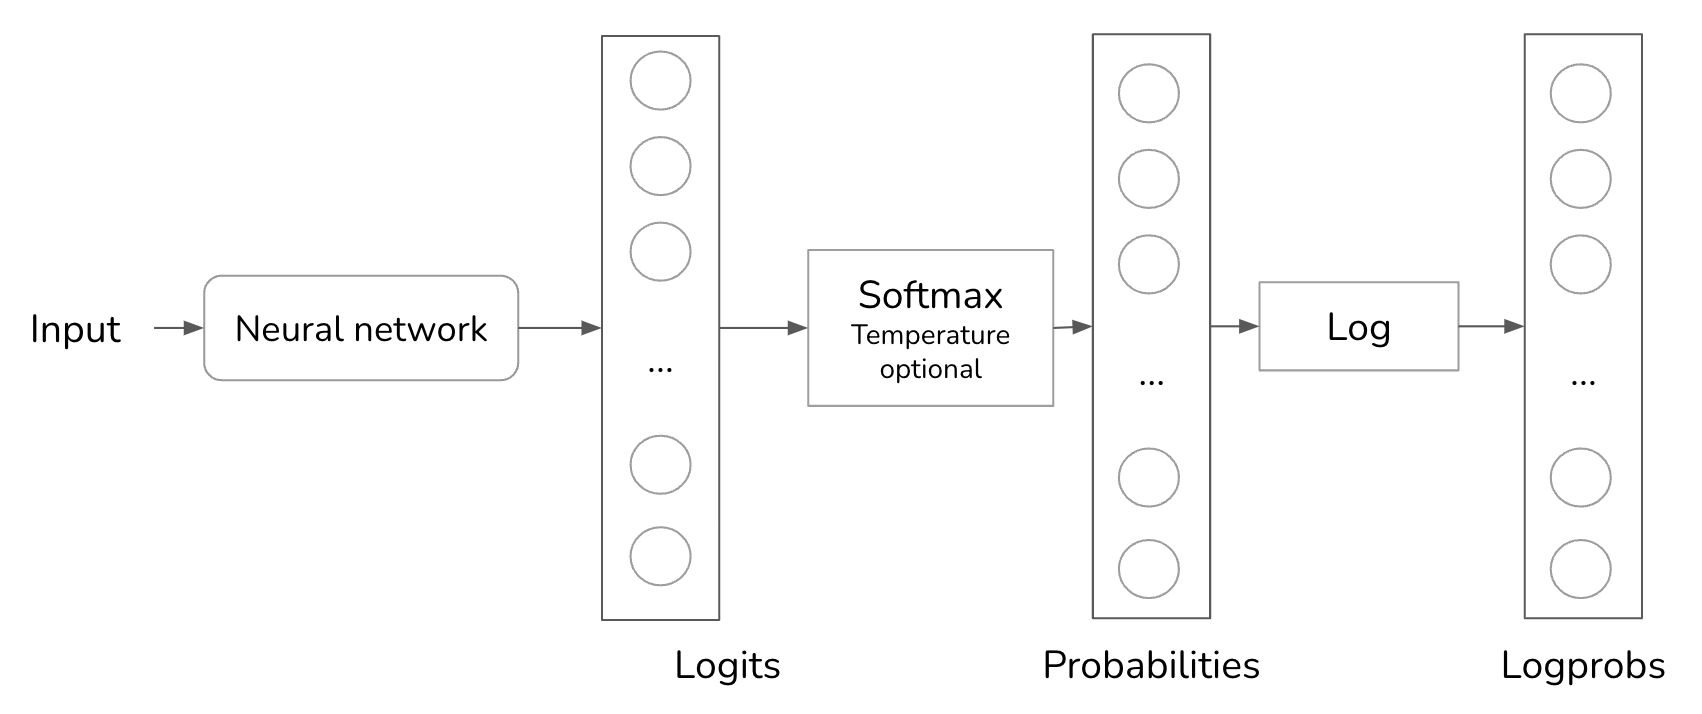
Generation configurations: temperature, top-k, top-p, and test time compute
How generation is actually configured.
Why it mattersIt demystifies why LLM outputs are inconsistent and how sampling knobs (temperature, top-k, top-p) plus test-time compute actually shape responses.
Out-of-Domain Finetuning to Bootstrap Hallucination Detection
How to use open-source, permissive-use data and collect less labeled samples for our tasks.
Why it mattersIf you're building hallucination detection or other classifiers with limited labeled data, this shows how to bootstrap from out-of-domain, permissively-licensed datasets to cut annotation costs while still hitting task performance.
Adversarial Attacks on LLMs
A survey of adversarial attacks and jailbreak prompts against language models.
Why it mattersA rigorous, research-grounded map of how jailbreaks and adversarial prompts actually work against aligned LLMs, giving engineers the vocabulary and threat models needed to red-team and harden their own AI products.
Mitigating Stereotypical Biases In Text To Image Generative Systems
Runway's diversity fine-tuning approach attacks text-to-image skew at the data level.
Why it mattersThe approach offers a concrete recipe for debiasing text-to-image models using synthetic data built from combinatorial prompt attributes, with released prompts and code and measured group fairness gains on both SD1.5 and SDXL.
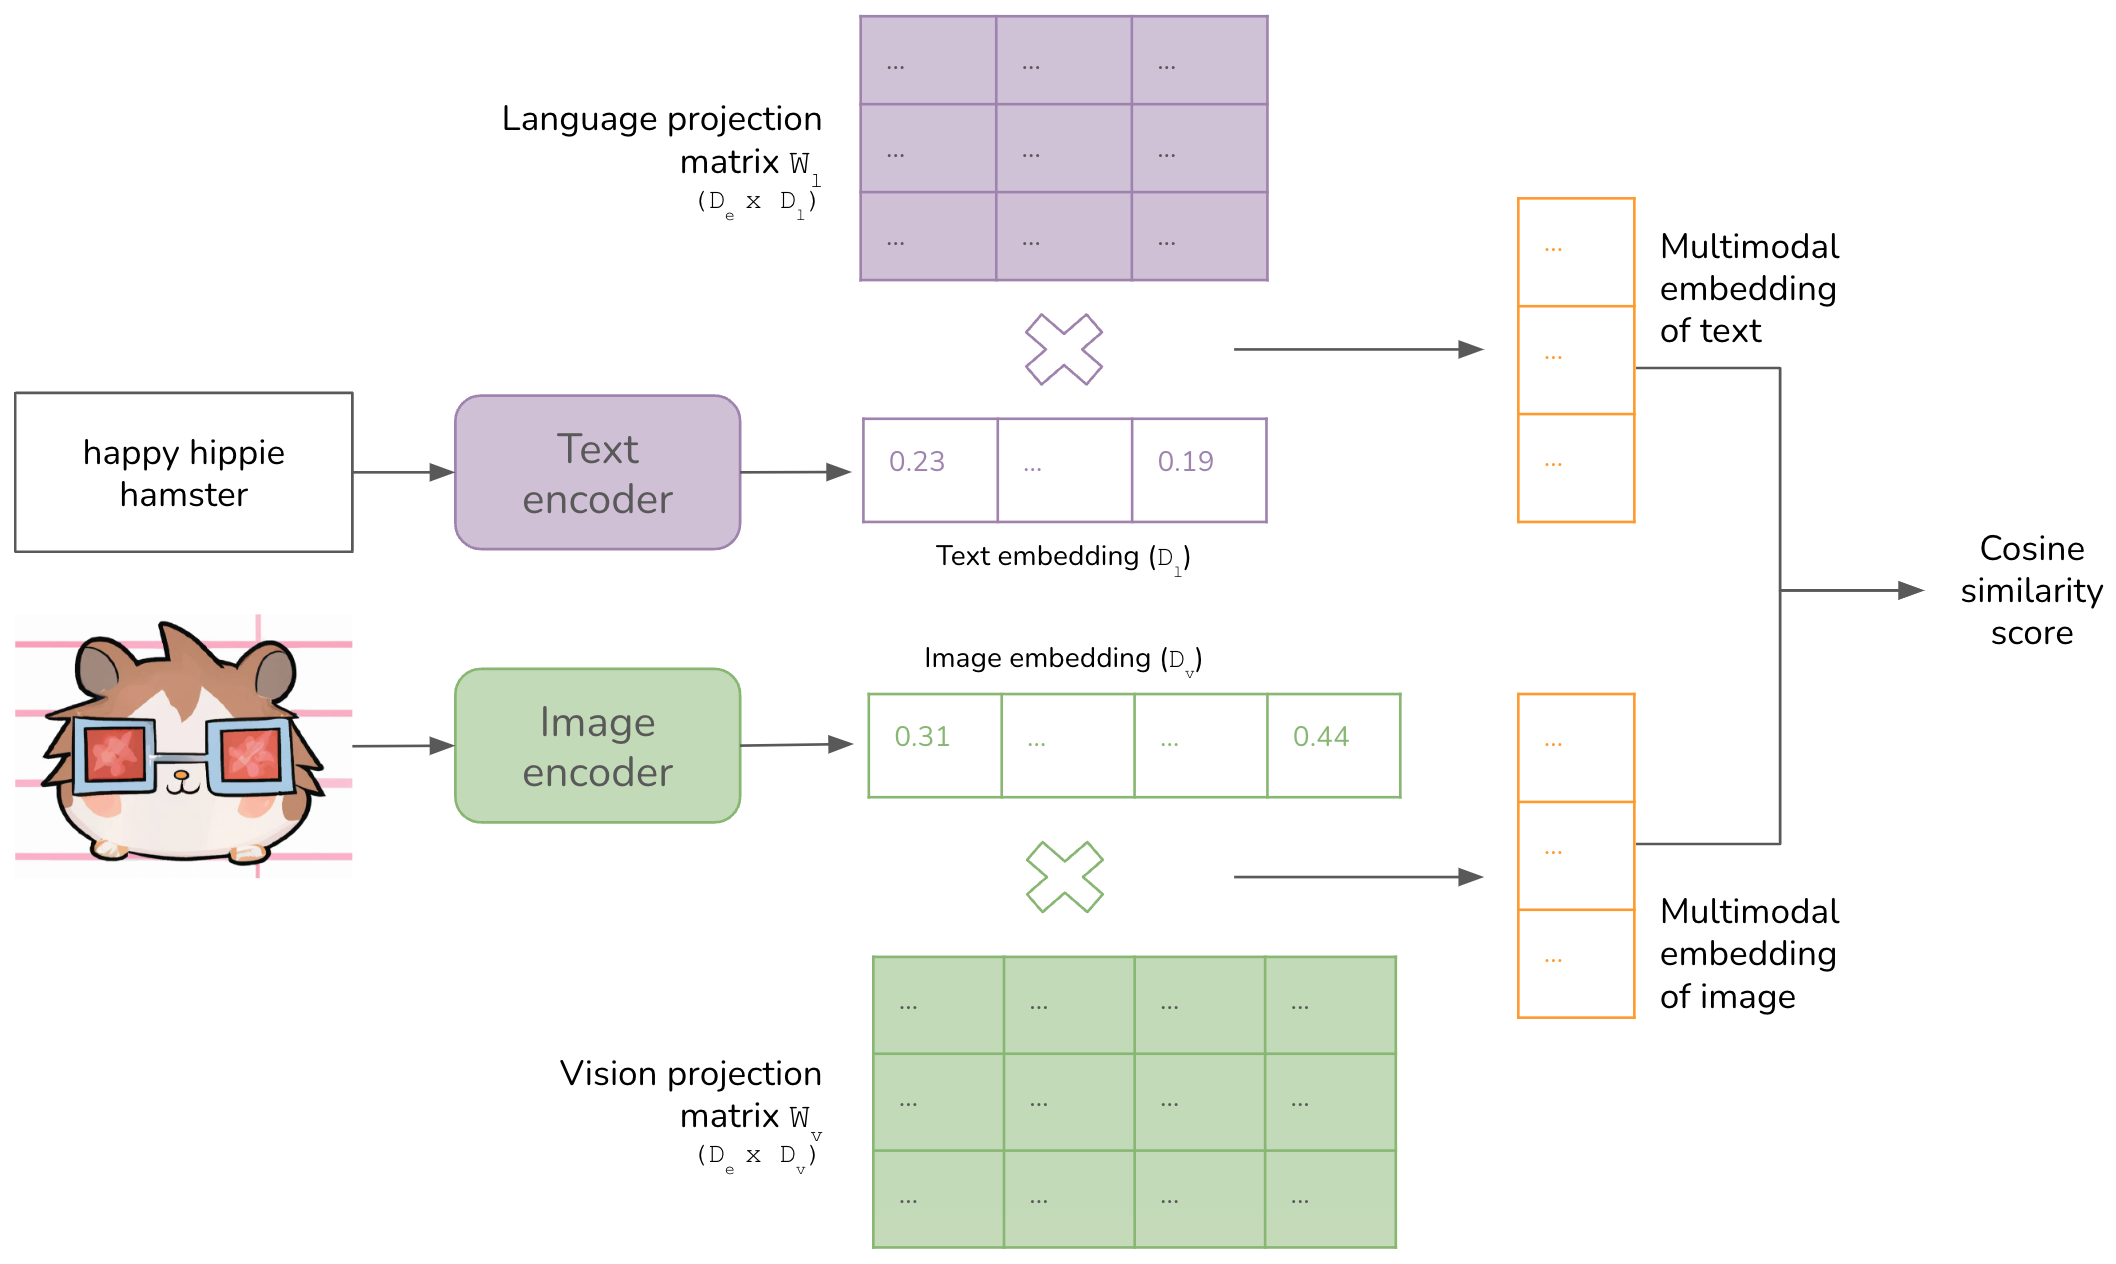
Multimodality and Large Multimodal Models (LMMs)
A primer on multimodality and large multimodal models.
Why it mattersA clear, foundational-to-frontier walkthrough of how multimodal models actually work — from CLIP and Flamingo to modern adapter-based LMMs — giving engineers the conceptual grounding to reason about and build with vision-language systems.
Scale Speed And Stepping Stones The Path To Gen 2
Runway's CTO walks through the sequencing behind the Gen models.
Why it mattersThis explains why video generation was staged, with structure-conditioned Gen-1 coming before open text-to-video, and frames next-frame prediction as the video analogue of next-token prediction for learning world structure.
Efficient Memory Management for Large Language Model Serving with PagedAttention
Applies operating-system paging to the KV cache so serving stops wasting most of its memory on fragmentation, raising throughput several-fold.
Why it mattersThe reason an inference server can hold many concurrent requests: treating the KV cache like virtual memory pages instead of one contiguous block removes the fragmentation that was wasting most of the GPU.
Evaluation & Hallucination Detection for Abstractive Summaries
Reference, context, and preference-based metrics, self-consistency, and catching hallucinations.
Why it mattersIf you're shipping summarization features, this lays out concrete metrics — reference-based, context-based, preference-based, and self-consistency checks.
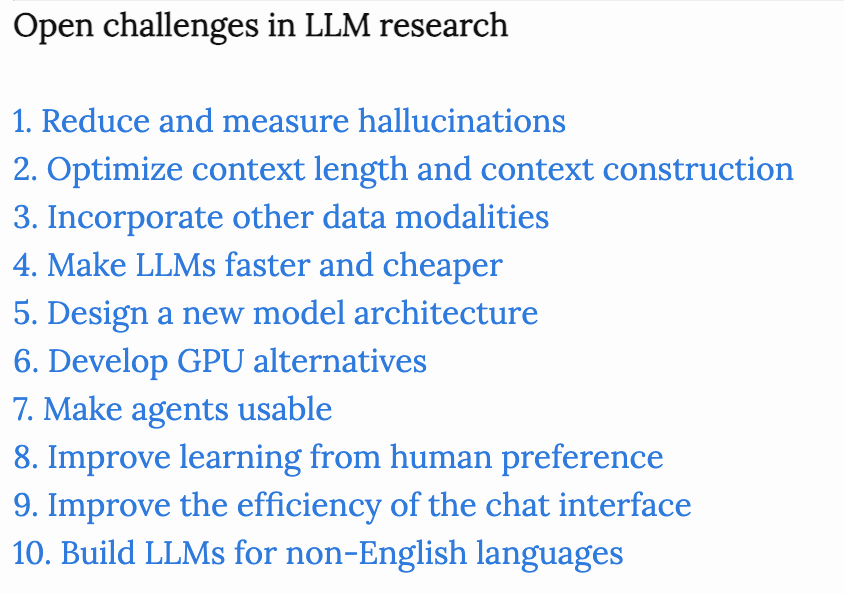
Open challenges in LLM research
Ten major open research directions in language models, drawn from conversations across industry and academia.
Why it mattersA structured tour of the 10 hardest open problems in LLM research — from measuring hallucination to non-GPU compute — with curated primary papers for each, giving engineers a map of where the field is heading and what to watch.
Sidekicks Improved Streaming
Shopify's Sidekick team details two fixes for streaming chat UX.
Why it mattersStreaming LLM output re-renders half-formed Markdown as raw text and stalls behind multi-hop tool calls; selective buffering plus a multiplexed event stream fixes both without waiting for the full response.

Patterns for Building LLM-based Systems & Products
Evals, RAG, fine-tuning, caching, guardrails, defensive UX, and collecting user feedback.
Why it mattersA comprehensive field guide to the seven practical patterns behind production LLM systems—covering how to structure evals, RAG, caching, and guardrails—so you can build reliable AI products instead of stitching together demos.
LLM Powered Autonomous Agents
A survey of LLM-powered autonomous agents built around planning, memory and tool use, drawing on AutoGPT, GPT-Engineer and BabyAGI as early proofs of concept.
Why it mattersA clear, canonical breakdown of the core components of LLM agents — planning with subgoal decomposition and reflection, short/long-term memory via vector stores, and tool use.
Direct Preference Optimization: Your Language Model is Secretly a Reward Model
Derives preference training as a simple classification loss on the policy itself, removing the reward model and the reinforcement-learning loop from RLHF.
Why it mattersIt stripped most of the machinery out of preference training: no separate reward model, no RL loop, just a classification loss that reaches comparable quality and is stable enough to run without a research team.
QLoRA: Efficient Finetuning of Quantized LLMs
Backpropagates through a frozen 4-bit quantized model into LoRA adapters, putting 65B-parameter finetuning on a single GPU without measurable quality loss.
Why it mattersIt collapsed the hardware bar for fine-tuning a large model from a cluster to one GPU, by backpropagating through 4-bit frozen weights into low-rank adapters.
GQA: Training Generalized Multi-Query Transformer Models from Multi-Head Checkpoints
Interpolates between multi-head and multi-query attention using grouped key-value heads, recovering multi-query speed while keeping most of multi-head quality.
Why it mattersThe compromise nearly every current model ships: grouped key-value heads give you multi-query's small cache without the quality drop, and the paper shows you can convert an existing multi-head checkpoint rather than retrain from scratch.
Some Intuition on Attention and the Transformer
What's the big deal, intuition on query-key-value vectors, multiple heads, multiple layers, and more.
Why it mattersA clear, intuition-first walkthrough of query-key-value attention, multi-head, and multi-layer mechanics — useful if you want to actually understand why the Transformer works rather than just memorize the diagram.
Minimal Chat
An argument that chat became the default LLM interface by inertia rather than fit.
Why it mattersChallenges the reflexive choice of a chat box as the LLM interface, arguing better interaction patterns exist — a design decision that shapes every AI product before a single model call is made.
More Design Patterns For Machine Learning Systems
9 patterns including HITL, hard mining, reframing, cascade, data flywheel, business rules layer, and more.
Why it mattersA compact catalog of production ML design patterns — like cascade models, hard negative mining, data flywheels, and business-rules layers.
Prompt Engineering
A survey of prompt engineering as in-context steering of an autoregressive model without touching its weights, treated as an empirical science whose methods vary sharply between models.
Why it mattersA rigorous, practitioner-oriented survey of in-context prompting methods — few-shot, chain-of-thought, self-consistency, and more.
Gen 2
Runway's second-generation video model dropped the requirement for structure conditioning: text alone, or a single driving image, produces a clip.
Why it mattersGen-2 was the point at which text-to-video became usable without a driving video, establishing the mode vocabulary covering text, image, stylization, mask, and render that later video models inherited.
Shopifys Machine Learning Platform Real Time Predictions
How Shopify extended its Ray-based ML platform from batch to real-time prediction.
Why it mattersShows how a general-purpose model-serving layer is built on Ray with a Feast-backed offline/online feature store, and where the latency and generalization tradeoffs land when many teams deploy to one platform.
The Transformer Family Version 2.0
A rewritten and roughly doubled survey of transformer architecture variants, restructured and brought up to date with the improvements proposed since the original 2020 version.
Why it mattersA thorough, notation-consistent reference on transformer architecture variants — from attention mechanisms to positional encodings and efficiency tricks.
Large Transformer Model Inference Optimization
Why inference on large transformers is hard and what actually helps.
Why it mattersA rigorous survey of how to cut transformer inference cost in time and memory — quantization, pruning, sparsity, and distillation — giving engineers a practical map for deploying large models affordably at scale.
OFASys: Enabling Multitask Learning with One Line of Code!
Qwen's OFASys tackles the practical pain of multimodal multitask learning, the batching and stability problems the team hit building OFA, aiming to make multitask setups a one-line affair.
Why it mattersIf you're wrangling multitask, multimodal training pipelines, OFASys reduces the boilerplate of setting up heterogeneous tasks and modalities into a declarative interface, tackling the batchification and training-stability headaches that usually derail generalist-model experiments.
Chinese CLIP: Contrastive Vision-Language Pretraining in Chinese
CLIP became both a foundation model and a bridge between vision and language, but cross-modal retrieval needs language-specific versions. This is an open-sourced Chinese CLIP.
Why it mattersIf you're building cross-modal retrieval or text-to-image pipelines for Chinese content, this gives you a purpose-trained Chinese CLIP rather than forcing English-centric embeddings onto Chinese text and image data.
Constitutional AI: Harmlessness from AI Feedback
Anthropic's method for training a harmless assistant from AI feedback against a written set of principles, replacing most human harm labels with model self-critique.
Why it mattersIt is how you train a model to refuse well without a human labelling every bad output: the model critiques and revises its own responses against an explicit written constitution.
Gen 1
Runway's first video model generates new footage from existing footage, transferring style from an image or prompt while the source clip supplies structure.
Why it mattersGen-1 solved temporal consistency by conditioning on a source video's structure, which was the intermediate step that made open text-to-video tractable a few months later.
Fast Inference from Transformers via Speculative Decoding
Runs a small draft model ahead of the large one and verifies its guesses in parallel, producing identical output several times faster.
Why it mattersIt makes generation faster without changing what the model outputs — a small model drafts, the large one verifies in parallel, rejected tokens fall back.
ReAct: Synergizing Reasoning and Acting in Language Models
Interleaves reasoning traces with tool actions in a single loop, so a model can plan, act against an external source, and revise from what it observes.
Why it mattersThis is the loop nearly every agent framework implements: think, act, observe, repeat.
Shopify Inbox Message Classification Model
Shopify classified millions of buyer chat messages by fixing the data instead of the model.
Why it mattersAccuracy came from taxonomy design and annotator agreement, not model choice. The same discipline decides whether an eval set or a classifier inside an agent pipeline measures what you think it measures.
Generalized Visual Language Models
Vision-language systems traditionally bolt an object detector onto a text decoder.
Why it mattersA structured survey of how to graft visual understanding onto pre-trained language models, covering the design choices behind modern VLMs — useful grounding for anyone building or fine-tuning multimodal AI systems.
FlashAttention: Fast and Memory-Efficient Exact Attention with IO-Awareness
Makes exact attention fast by minimising reads and writes between GPU memory levels rather than approximating it — an IO-aware algorithm, not a cheaper estimate.
Why it mattersThe insight that attention was memory-bound rather than compute-bound, and that tiling it to avoid round-trips to slow GPU memory makes it several times faster while staying exact.
Learning with not Enough Data Part 3: Data Generation
Approaches to generating synthetic training data when real data is scarce, covering augmentation of existing samples and outright generation of new ones.
Why it mattersIf you're training or fine-tuning models with limited labeled data, this breaks down practical approaches to synthesizing training examples — augmentation techniques and few-shot LM-based generation.
High Resolution Image Synthesis With Latent Diffusion Models
The paper that made diffusion affordable.
Why it mattersLatent diffusion is why high-resolution image generation became trainable outside big labs: compress away imperceptible detail first, run the diffusion model in latent space, and condition with cross-attention on text or boxes.
Training Compute-Optimal Large Language Models
Showed the large models of the era were badly undertrained: for a fixed compute budget, model size and training tokens should scale roughly in step, not size alone.
Why it mattersIt reset how everyone spends a training budget.
Training language models to follow instructions with human feedback
Fine-tuning with human feedback made a 1.3B model preferred over 175B GPT-3, establishing RLHF as the step that turns a language model into something that follows instructions.
Why it mattersThe gap between a raw language model and an assistant is this paper: alignment to human preference beat raw scale for usefulness, with a 1.3B InstructGPT preferred to 175B GPT-3.
Learning with not Enough Data Part 2: Active Learning
This is part 2 of what to do when facing a limited amount of labeled data for supervised learning tasks.
Why it mattersIf you're training models with scarce labels and a tight annotation budget, this walks through active learning methods for choosing which samples are worth labeling.
Chain-of-Thought Prompting Elicits Reasoning in Large Language Models
Showed that prompting a model to produce intermediate reasoning steps unlocks arithmetic and symbolic reasoning that appears only above a certain model scale.
Why it mattersThe finding that asking for the working, not just the answer, changes what a model can solve — and that the effect only emerges above a certain scale.
Learning with not Enough Data Part 1: Semi-Supervised Learning
When facing a limited amount of labeled data for supervised learning tasks, four approaches are commonly discussed.
Why it mattersA clear walkthrough of the main approaches for training when labeled data is scarce, giving practitioners concrete semi-supervised learning strategies to squeeze more value from unlabeled datasets.
How to Train Really Large Models on Many GPUs?
[Updated on 2022-03-13: add expert choice routing .] [Updated on 2022-06-10]: Greg and I wrote a shorted and upgraded version of this post, published on OpenAI Blog.
Why it mattersA rigorous, well-organized reference on the parallelism strategies (data, tensor, pipeline, MoE, expert-choice routing) and memory-saving techniques that make large-scale model training feasible.
What are Diffusion Models?
[Updated on 2021-09-19: Highly recommend this blog post on score-based generative modeling by Yang Song (author of several key papers in the references)]. [Updated on 2022-08-27.
Why it mattersA rigorous, continuously-updated technical walkthrough of diffusion models — from the DDPM math to consistency models and latent diffusion.
An index of the vibe-coding frontier. Corrections welcome.