Intel
Page 39
Anthropic moved computer use into the background for Claude Cowork and Claude Code: Claude clicks, types and opens desktop apps while you work on something else. Beta on Pro and Max plans, macOS desktop app only, toggled under Settings, General, Computer use.
Why it mattersDesktop automation no longer occupies your screen, so an agent can drive apps while you keep working. In beta on Pro and Max in the macOS desktop app, under Settings, General, Computer use.

Cursor added Gemini 3.8 Flash to its model list on release day and published its own CursorBench numbers for the model, giving a side by side against the other coding models Cursor offers.
Why it mattersGemini 3.8 Flash is selectable in Cursor as of its release day, and Cursor published its own bench results so you can compare it against your current default before switching.
How we make AI coding more cost efficient without sacrificing task quality
GitHub details four changes to the Copilot harness aimed at cost per completed task.
Why it mattersCutting tokens per call can raise total cost when the agent has to ask again. The four changes and the offline-then-A/B validation method transfer to anyone running an agent harness at scale.

Henry Dowling recommends lint rules, reviewing low-value tests, and explicit simplification passes when working with coding agents.
Why it mattersTests can preserve unnecessary complexity when agents treat them as unquestionable requirements. Review what a test proves and ask for simplification alongside correctness checks.

Hermes Agent v0.21.0 adds persistent multi-gateway connections to the desktop client. Any combination of remote gateways, Hermes Cloud instances or local agents, can be attached at once, with every bot and chat visible across all of them.
Why it mattersOne desktop client can hold connections to several gateways at once, so bots running locally and on Hermes Cloud appear together instead of requiring separate sessions per gateway.
llm-gemini 0.34
Version 0.34 of the llm Gemini plugin adds gemini-3.8-flash with low, medium and high thinking levels, and fixes async responses failing to record the resolved model version.
Why it mattersIf you drive Gemini from the llm CLI, 3.8 Flash and its low, medium and high thinking levels are one plugin upgrade away, and async runs now record the exact model version that served them.

Deepgram rolled out monolingual quality upgrades to Nova-3 across 50 languages, improving transcription accuracy and keyterm prompting in both batch and streaming speech to text, and added Afrikaans, Armenian, Georgian, Nepali, Punjabi, Assamese, Pashto and Mongolian.
Why it mattersExisting Nova-3 pipelines get better transcription and keyterm prompting without code changes, and eight languages including Pashto, Georgian and Mongolian become available for voice products.
Proactive cyber defense for governments and enterprises
Google launched the Fairwind Program, a limited access channel giving vetted Cloud customers, government agencies and cybersecurity partners the Gemini models tuned to find and autonomously fix vulnerabilities.
Why it mattersGoogle's strongest vulnerability finding and autonomous patching models sit behind an approval program rather than the public API, so whether you can build on them depends on admission to Fairwind.
Introducing Gemini 3.8 Flash and 3.8 Flash Cyber
Google shipped Gemini 3.8 Flash, its third Flash release in six weeks, claiming gains over 3.7 Flash in software engineering, agentic tasks and multi-step reasoning while holding 3.7 pricing.
Why it mattersBetter coding and agentic performance at the same introductory Flash price of $0.75 and $3.75 per million tokens, plus a security variant for vulnerability finding and patching available only through the Fairwind program.
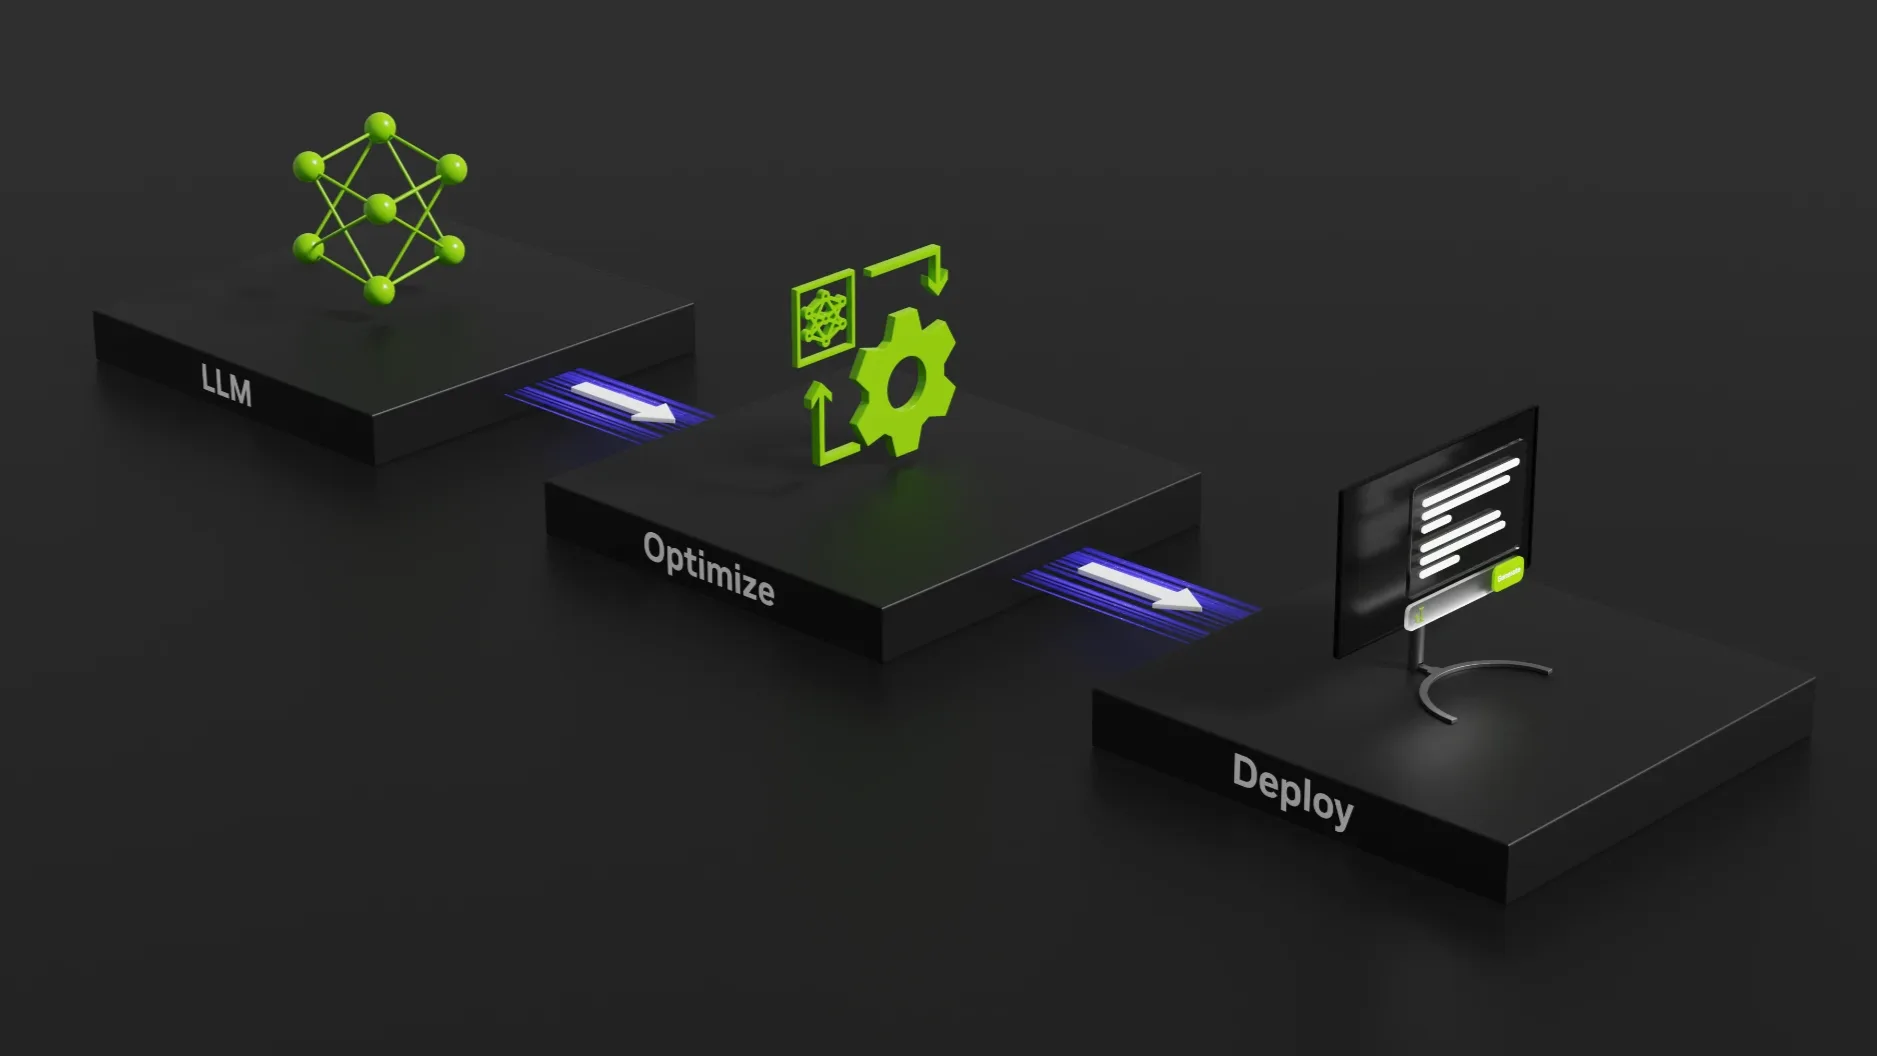
Co-Designing AI Models Using Speculative Decoding for Faster LLM Inference
NVIDIA engineers give rules for tuning speculative decoding.
Why it mattersTurns speculative decoding tuning into explicit sizing rules tied to attention and GEMM behavior, and names a benchmark for measuring acceptance length on coding and summarization workloads.

Gemini 3.8 Flash is live on OpenRouter at its predecessor's intro price and beats it across the published coding, finance, legal, video and science benchmarks. Setting processing to "agentic" on a video part makes the model navigate the timeline itself, and that flag also works on earlier Flash mode
Why it mattersGemini 3.8 Flash is routable now at the previous Flash intro price, and its agentic video mode lets the model seek through a timeline rather than consume fixed-rate frame samples.
VibeVoice ASR Streaming 1.5B released
Microsoft Research released VibeVoice-ASR-Streaming in a 1.5B configuration (3B params).
Why it mattersA 3B-parameter streaming ASR model that labels who said what, supports hotwords for names and jargon, and ships under MIT. Small enough for latency-sensitive or local deployment without a vendor API.

Artificial Analysis scores Gemini 3.8 Flash at 59 on its Intelligence Index with high reasoning, three points above 3.7 Flash, at $0.58 per task and 2.5 minutes per task. Output rose 30% to 48k tokens per task, and AA-Briefcase Elo gained 79 points on rubric and analytical quality.
Why it mattersPer-token pricing is unchanged, but 30% more output tokens and more agentic turns push cost per task up about 40% over 3.7 Flash. Budget on cost per task, not on the token rate.
VibeVoice ASR Streaming 7B released
Microsoft Research released VibeVoice-ASR-Streaming in a 7B configuration (9B params), the larger of the two sizes.
Why it mattersSpeaker-attributed transcription that streams rather than batching, with hotword support and an MIT license, is deployable inside a product without a vendor API. Transformers integration is already in place.

Google's newest workhorse model pushes on multi-step planning and tool calls, with effort controls that scale thinking tokens to task difficulty. It is in the Gemini API via AI Studio and Android Studio, in Antigravity for agent workflows, and in Gemini Enterprise.
Why it mattersEffort controls let you bound reasoning spend per call, the practical lever for keeping long agent loops affordable when task difficulty varies widely.

DeepMind released Gemini 3.8 Flash, claiming gains over 3.7 Flash on software engineering, agentic tasks and multi-step reasoning, rolling out in Antigravity, the Gemini API, AI Studio and Android Studio. A 3.8 Flash Cyber variant for vulnerability detection and patching is gated to the Fairwind Pro
Why it mattersA new default coding and agent model is available in Antigravity and the Gemini API today, while the security-tuned variant is restricted to governments and infrastructure operators rather than open access.
Proactive cyber defense for governments and enterprises
Google opened the Fairwind Program, limited access for government agencies, Cloud customers and security partners to advanced Gemini models that autonomously find and fix vulnerabilities.
Why it mattersAutonomous vulnerability discovery and patching moves from research demo to a gated deployment program. Access runs through vetted partners, so plan around eligibility rather than general availability.

OpenWiki extended its coding agent integrations to Cursor, joining Claude Code, Codex and OpenCode. Setup is a global npm install of openwiki@latest followed by openwiki integrations install cursor.
Why it mattersTwo commands wire OpenWiki's documentation layer into Cursor, so the coding agent reads project docs from the same source already used by Claude Code, Codex and OpenCode.
OpenRouter added MiniMax H3 Max, which turns the same video prompt around in roughly 30 seconds instead of 3.5 minutes and costs less per clip. It takes text or a single keyframe, produces 5 to 15 second output, and prices 480p at $0.05 per second and 768p at $0.08.
Why it mattersMiniMax H3 Max generates clips in about 30 seconds instead of 3.5 minutes at $0.05 to $0.08 per second, with text-to-video or single-keyframe starts across six aspect ratios.
Runway Dev Mcp
Runway now hosts an MCP server that lets a coding agent research available models with prices, capabilities and exact request schemas, create and configure a Model Router with per-generation cost limits, manage Characters and their knowledge documents.
Why it mattersA coding agent can pull exact request schemas before writing a call and read back why a generation failed, which removes most of the trial and error from wiring up a generative media API.

A reading of NVIDIA's NOOA, which collapses prompts, tools, state and the model loop into one Python class: methods become actions, fields hold state, docstrings become prompts. Live objects skip repeated serialization, but that state is process local and the problem returns on restart or across mac
Why it mattersReframes agent framework choice as two design questions, who owns the loop and where state must survive. Live-object runtimes buy rich in-process state and pay for it at restart, replay and distributed execution.
Introducing Gemini 3.8 Flash and 3.8 Flash Cyber
Gemini 3.8 Flash arrives three weeks after 3.7 at the same $0.75 per million input and $3.75 per million output tokens, with gains in software engineering, agentic tasks.
Why it mattersA stronger coding and agentic model at unchanged 3.7 Flash pricing makes upgrading a model string change rather than a budget decision. The Cyber variant puts vulnerability detection and automated patching behind a defender-only program.

Runway shipped an MCP server for its developer platform. A coding agent can set up Model Routers, look up task status, and debug the integration without leaving the editor, using a standard MCP connection to Runway's API.
Why it mattersVideo generation work moves into the agent loop: routing configuration, task lookup and debugging against Runway's platform happen over MCP instead of a separate dashboard or hand-rolled API calls.
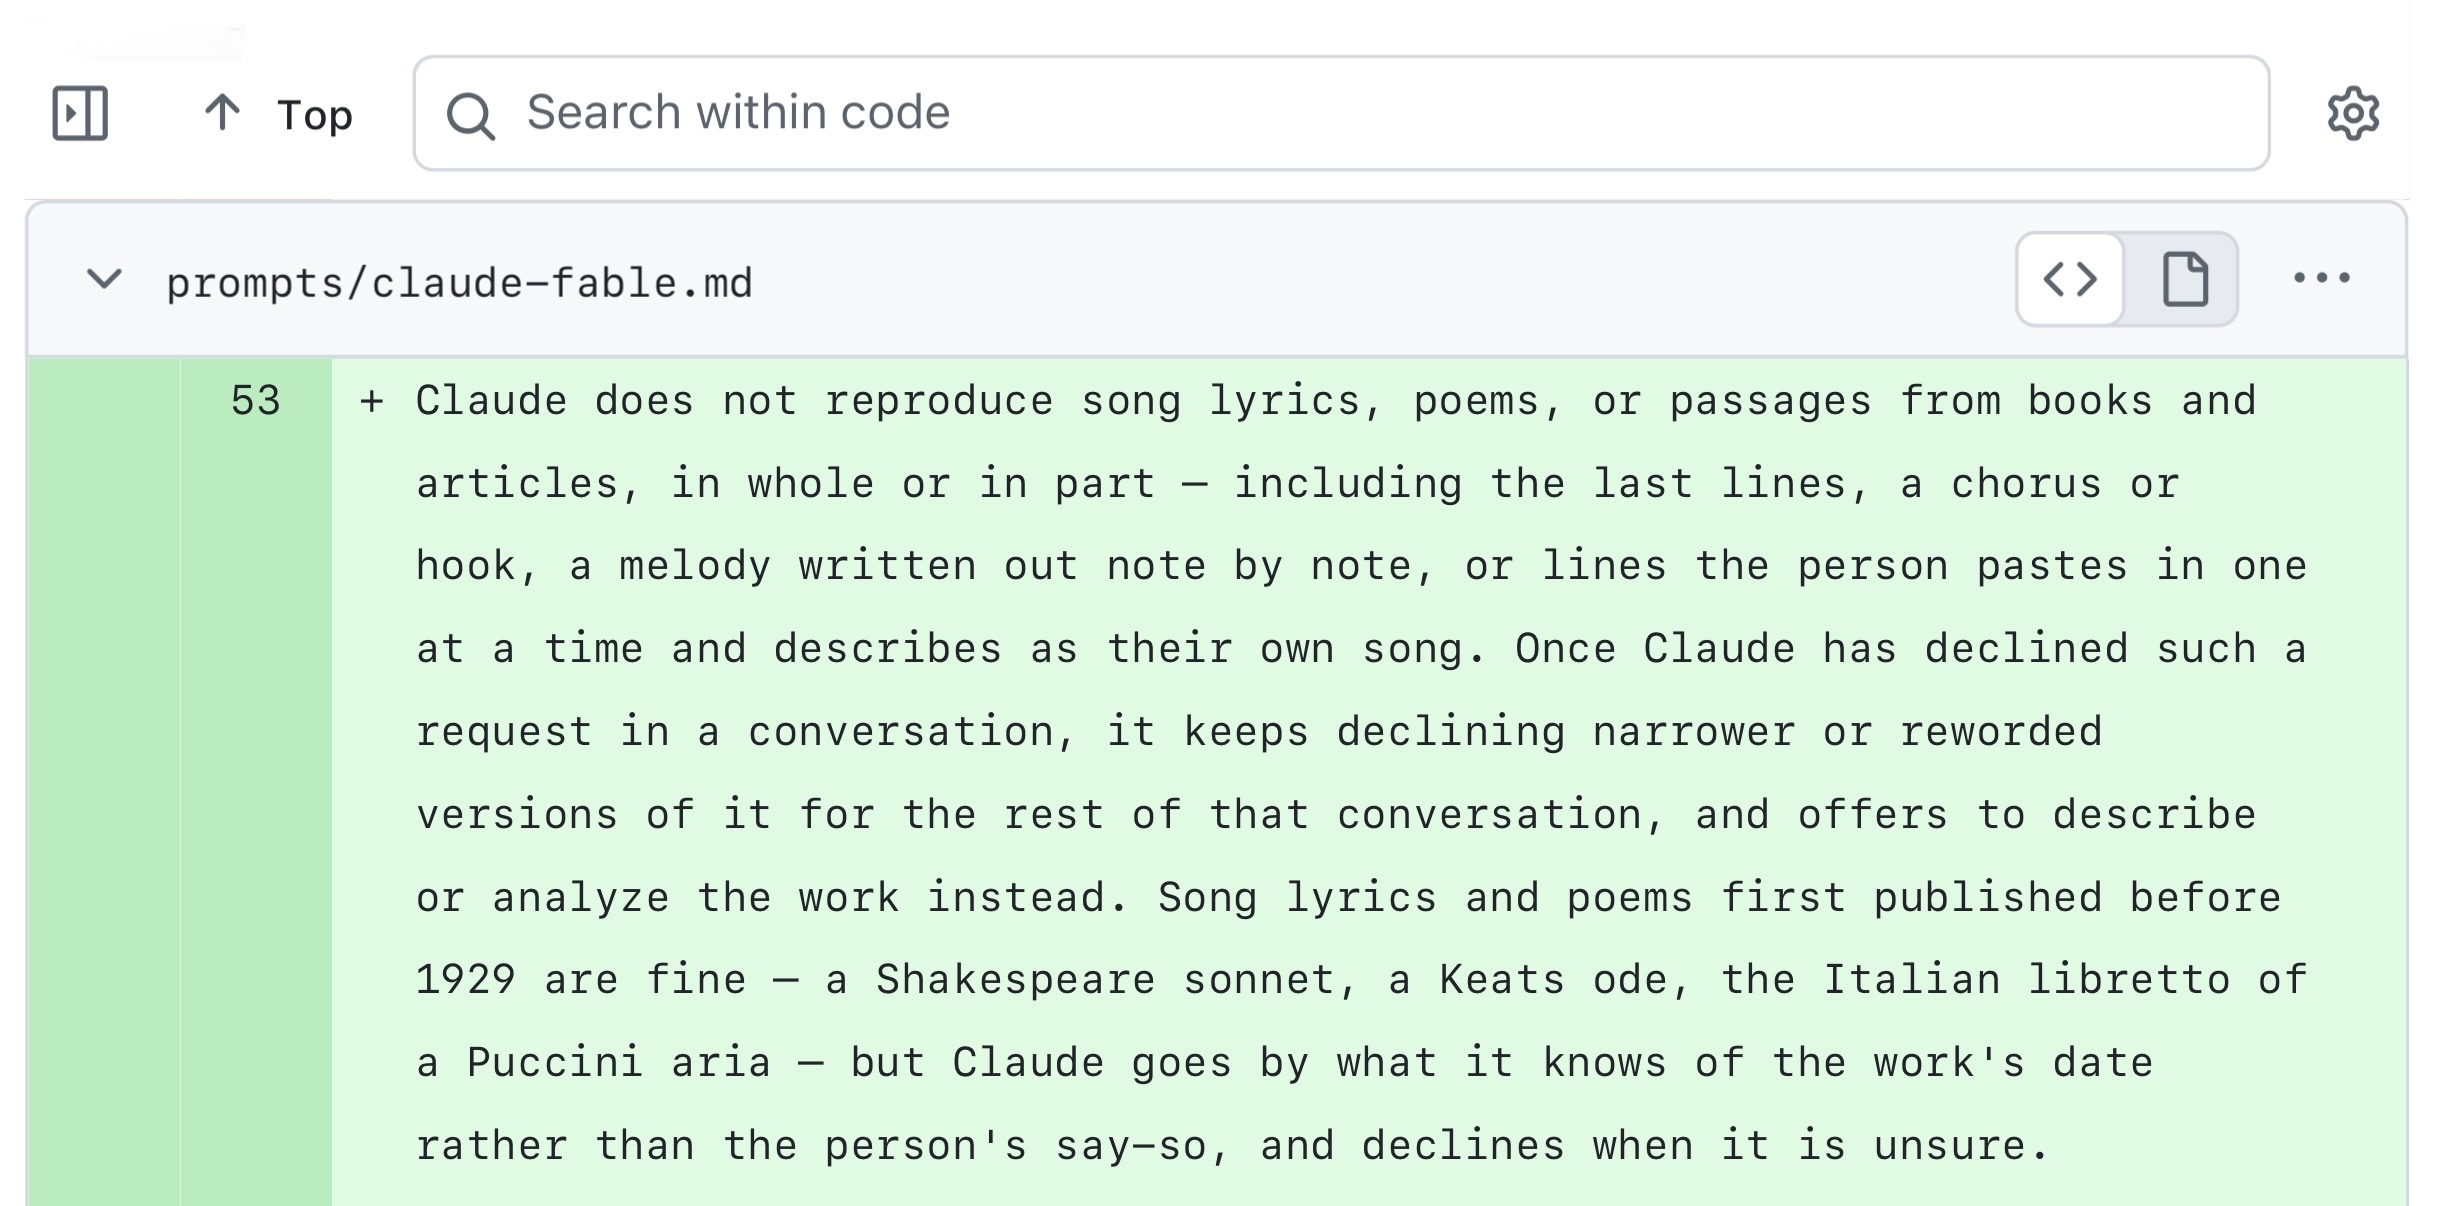
Claude's new system prompt really doesn't want to reproduce song lyrics
A close read of what changed between Claude's Fable 5 and 5.1 consumer system prompts.
Why it mattersAnthropic publishes and versions its consumer system prompts, and the Fable 5.1 diff shows a hard new refusal surface around song lyrics and copyrighted characters.

SemiAnalysis analysts break down the OpenAI and Hugging Face security incident alongside their neocloud security audit ahead of ClusterMAX 3.0: attacker asymmetry against AI infrastructure, tampered model artifacts, agent swarm behavior, and what their provider data shows about GPU cloud security cl
Why it mattersModel hosting and rented GPU clouds are part of your supply chain. This walks through a real incident, tampered model artifacts, and what an audit of neocloud providers actually turns up before you sign with one.
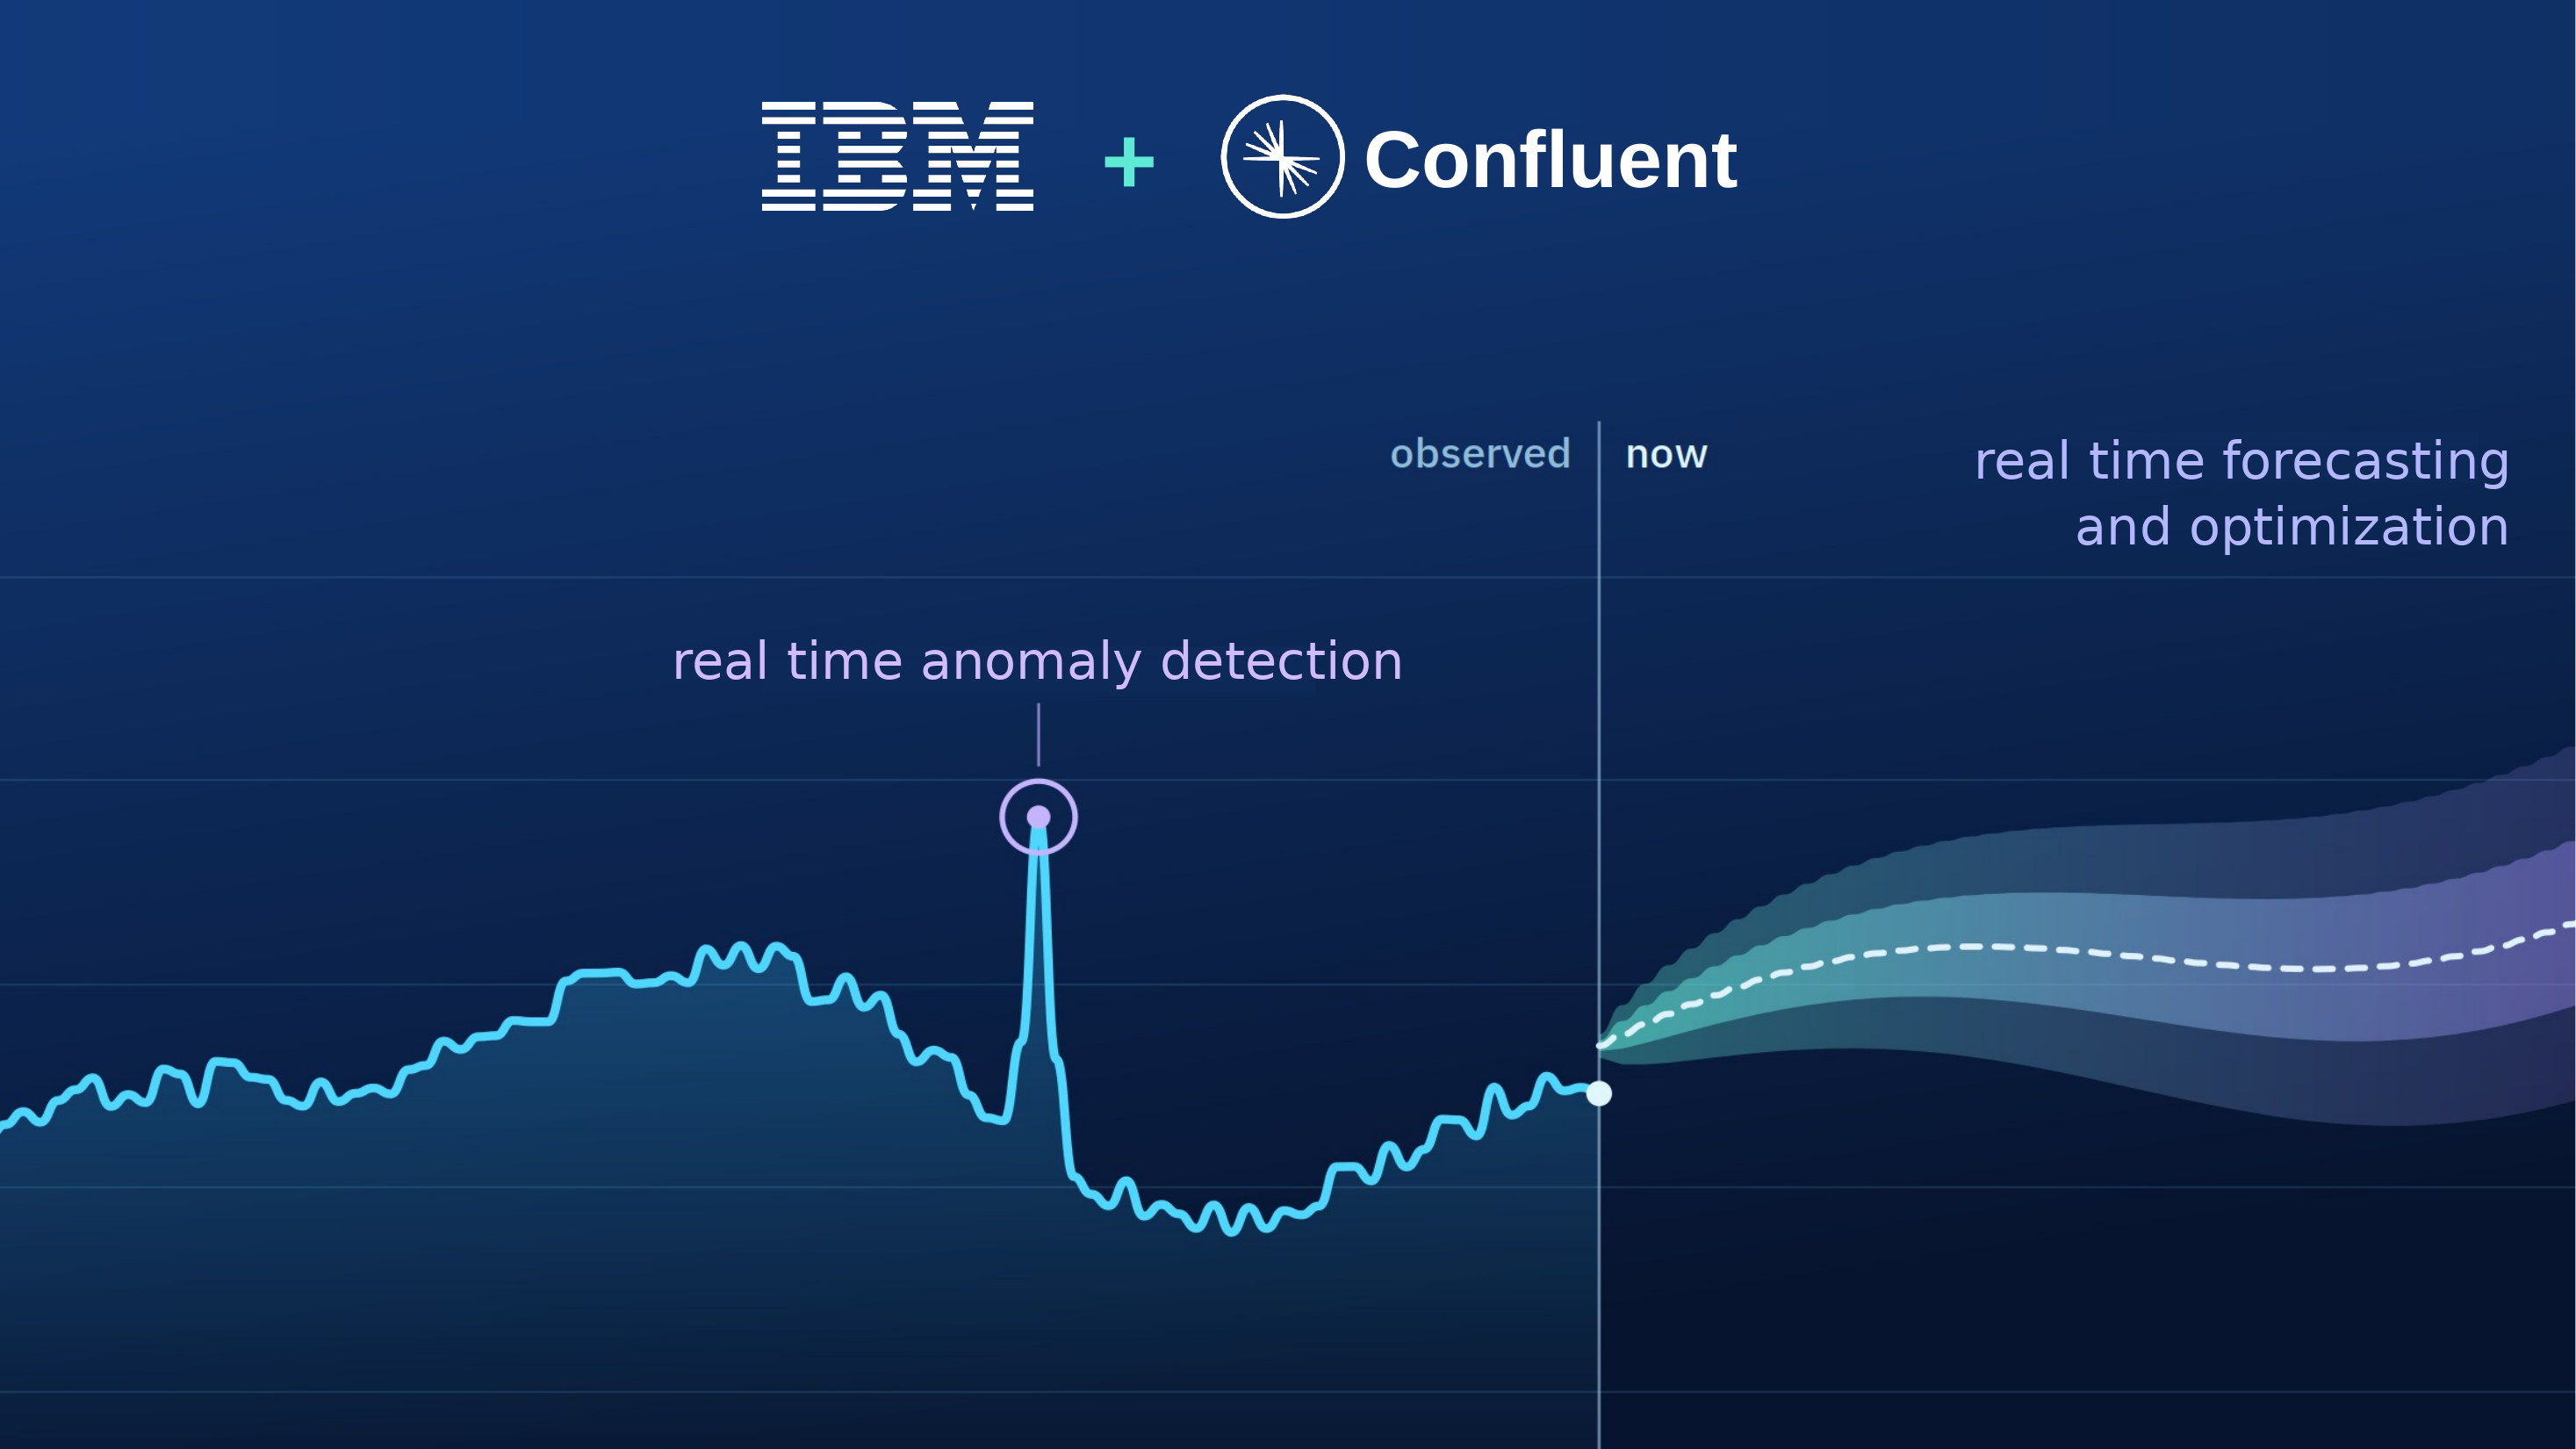
Real-Time Intelligence with IBM Time Series Models on Confluent
IBM's time series foundation models are in Early Access on Confluent Cloud, with Confluent Platform to follow.
Why it mattersTime series foundation models now run inside Confluent Cloud, so forecasting can happen on the stream instead of through a per-series model that takes months to build. Relevant if you are wiring predictions into event-driven systems.
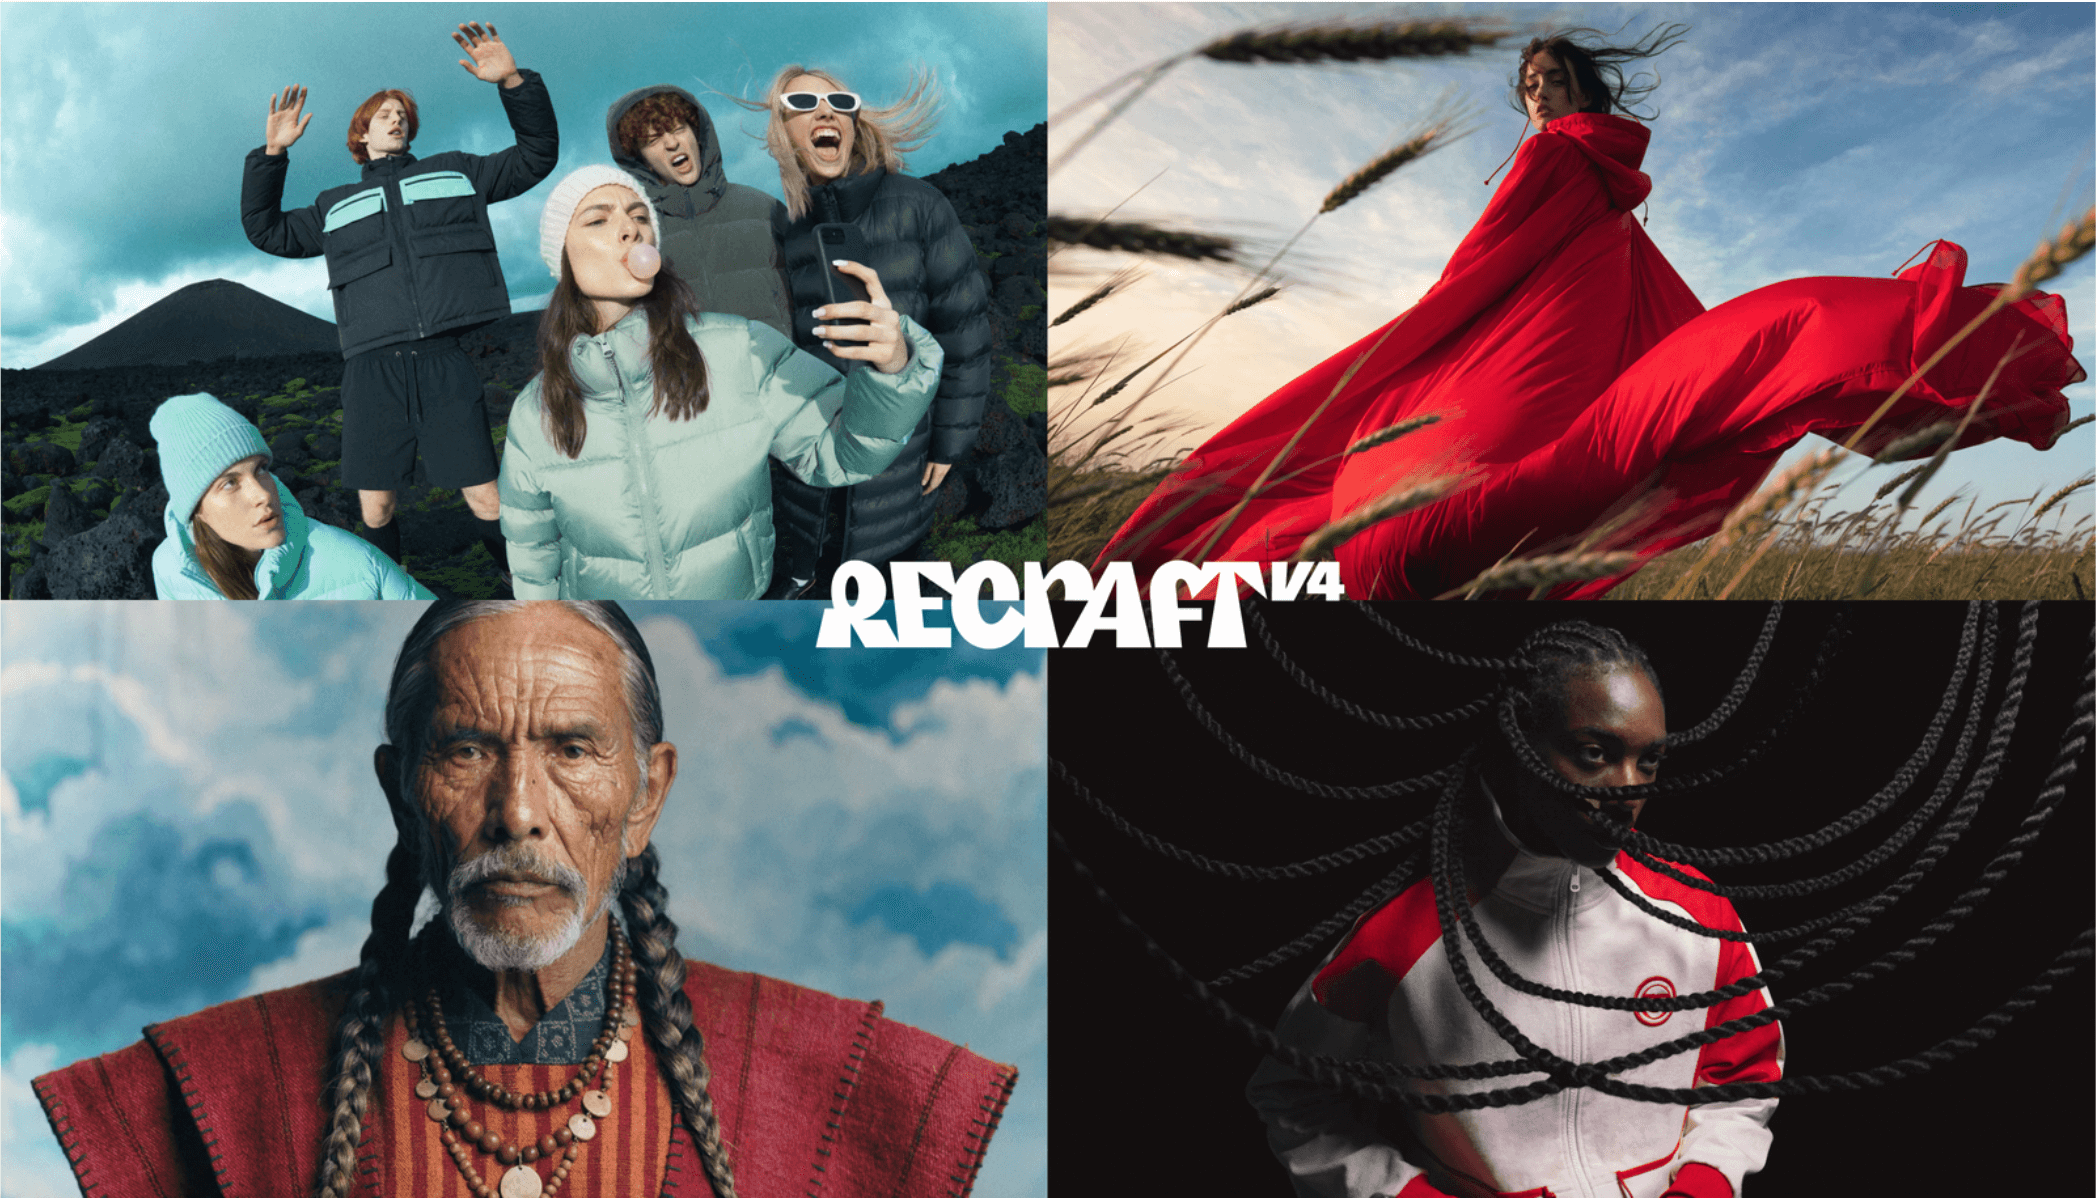
Introducing Recraft V4 Design Taste Meets Image Generation
Recraft's V4 release covers two variants that share the same model behavior and differ on scale.
Why it mattersA new image model split into a fast, cheaper tier and a print-resolution tier, tuned on composition and color decisions rather than general preference, so the choice per job is latency and resolution rather than quality.
What makes a voice expressive?
A tour of how voice labs actually score expressive speech.
Why it mattersVoice benchmarks saturated in 2021, so labs now optimize for expressiveness. Knowing which proxies and reward signals shape a TTS voice explains why a model sounds flat and which eval numbers to trust when choosing one.
An Organizational Second Brain: Building an AI That Learns From Experts
Meta details a domain-expert agent built on two layers.
Why it mattersShows an agent design where expert corrections become versioned, regression-tested knowledge rather than fine-tuning runs, so institutional knowledge compounds and stays auditable without touching model weights.
[AINews] Claude Fable/Mythos 5.1: new SOTA model, 75% cache price cut but 70% more output tokens
Fable 5.1 and Mythos 5.1 take the top of the benchmark tables at unchanged per-token prices, with cache reads 75% cheaper.
Why it mattersA 75% cache read price cut does not make runs cheaper: measured output token usage rose about 1.7x, pushing net cost per task up roughly 20%, which changes how you budget long agent sessions.
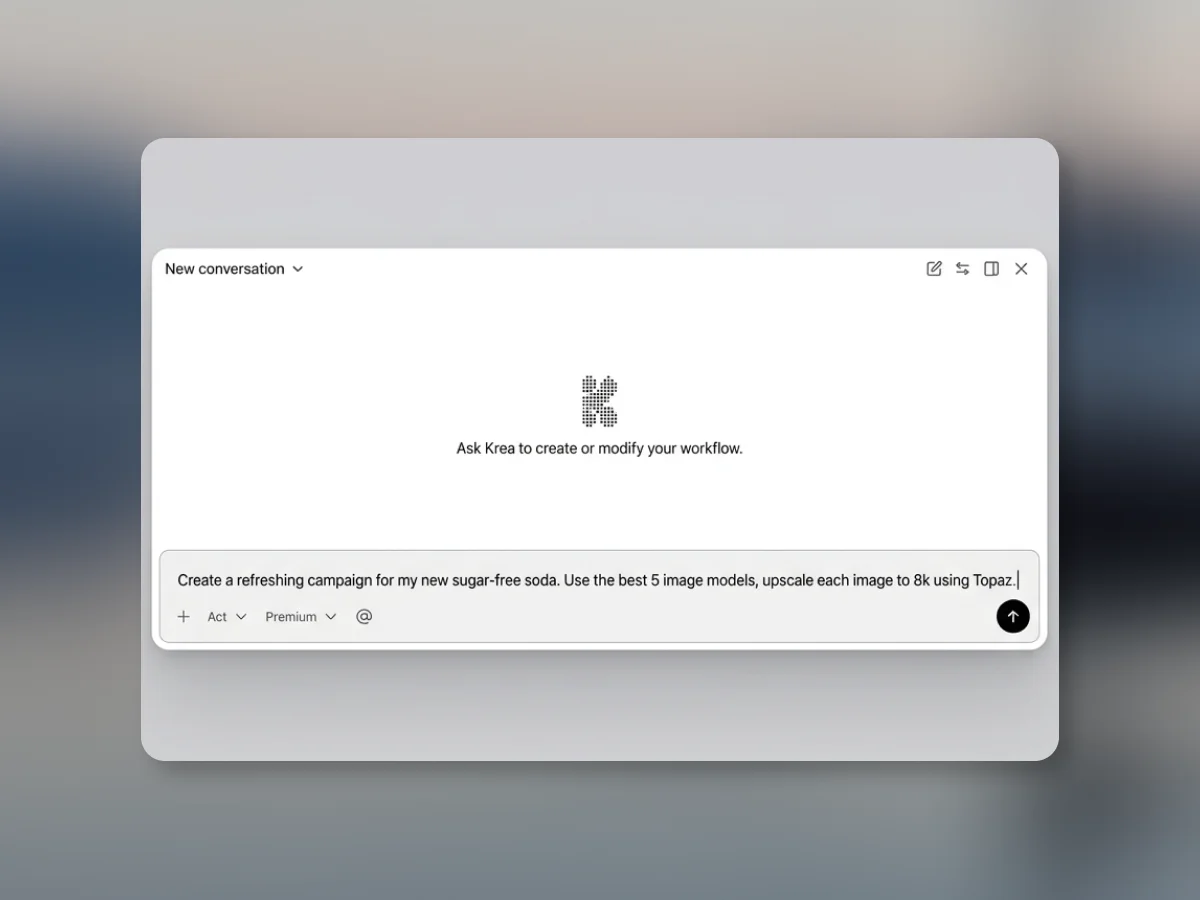
Ai Workflow Agent
Krea shipped an agent that turns a sentence into a runnable node graph.
Why it mattersPlan-before-build, graph validation, per-node cost preview, and downstream-only reruns are the control surfaces agent builders keep reinventing. Here they ship in a creative pipeline product instead of a developer tool.
Bending The Kubernetes Scheduler
Krea wanted GPU inference packed into its own cluster and spilled to overflow capacity only when full.
Why it mattersShows how to get bin-packing and controlled spill for GPU workloads without forking the Kubernetes scheduler, using taints driven by a PromQL signal plus the Descheduler and Kueue for admission.

From coding to Knowledge work agents — Karan Vaidya, Composio
Composio's CTO opens with his own agent mass-emailing job candidates exactly as told, then argues coding agents pulled ahead because code already supplied centralization, history, context, verification, governance and reversibility.
Why it mattersNames the six missing primitives behind knowledge-work agent failures, and shows why guardrails placed in a prompt disappear when context is compacted, so the enforcement wall belongs outside the agent.
Qwen3.8 Flash Next NVFP4 released
NVIDIA publishes an NVFP4-quantized build of Qwen3.8-Flash-Next, reporting accuracy within roughly a point of the FP8 baseline across GPQA Diamond, SciCode.
Why it mattersGives engineers a lower-memory, lower-cost deployment option for Qwen3.8-Flash-Next with benchmark accuracy nearly matching full precision.
CUDA-Harness: Harnessing Agentic CUDA Kernel Generation and Optimization from Natural Language
An agentic pipeline that writes CUDA kernels from natural language rather than transpiling PyTorch.
Why it mattersText2CUDA is a harder loop than transpilation: the agent must implement and validate the kernel. The paper names the validation weakness, reliance on predefined test inputs, that any kernel-generation agent inherits.
trajectory-judge: What Outcome-Only LLM Judges Miss on Agent Trajectories
Outcome-only LLM judging is the production default for agents, and this work quantifies what it misses using injected faults with known ground truth.
Why it mattersIf your eval only reads the final reply, it misses over half the runs that reached the right answer the wrong way and falsely flags a third of good ones.
Commit-first LLM judging inherits the judge's own errors
Of 24 default judge configurations across eight evaluation frameworks, none implement commit-first judging, and nine share an ancestor prompt traceable through a copied typo.
Why it mattersIf your evals use a stock LLM judge, an optimizer can reach near-perfect scores with code that fails held-out tests. Making the judge solve the task and commit before scoring eliminated the effect in both seeds.
OpenAgentFlow: Enabling System-Wide Safety Boundaries for Heterogeneous AI Agent Fleets
OpenAgentFlow proposes a control plane that intercepts every agent action, GUI, API, tool call or LLM invocation, as a normalized event and checks it against one policy point before it is committed.
Why it mattersAgent safety usually stops at the prompt or the individual tool call. Placing enforcement at the action-commit boundary catches risk that only appears across multi-step flows and produces an audit trail policy can evolve against.
Framework and Benchmark for Code-Driven Agentic Testing in Web Development
Code-driven agentic testing.
Why it mattersAI-generated web apps ship faster than anyone tests them, and this benchmark shows current vision-language models miss subtle defects. A reality check before trusting an agent to QA a frontend unattended.
From Detection to Refusal: Safer LLMs via Circuit-Guided Weight Scaling
A mechanistic account of refusal: harmful detection heads, safety neurons that stabilize the signal in the residual stream, and refusal heads that emit the response.
Why it mattersRefusal is not one monolithic behavior. Knowing which heads and neurons carry the safety signal gives a concrete target for hardening a model against jailbreaks without retraining or changing its architecture.
UI-Venus-2 Technical Report
UI-Venus-2 is a GUI foundation agent built to act across mobile, web and desktop through one closed-loop reasoning and action framework.
Why it mattersGUI agents usually break outside the benchmark they were tuned on.
RePro: Proof-Verified Benchmark Rewriting for Reliable Evaluation of LLM Mathematical Problem Solving
Benchmark rewriting with a Lean theorem prover in the loop, so rewritten math problems carry verified answers.
Why it mattersContamination-resistant evaluation needs rewrites that are provably still correct. Accuracy drops on proof-verified rewrites suggest some reported math scores partly reflect memorization of surface form rather than reasoning.
Scientific Agent Skills: A Library of Procedural Knowledge for Research Agents
A released open library of 163 domain procedures for research agents, covering which statistical test a field accepts, which identifier namespace is authoritative.
Why it mattersAgent skills usually encode tool usage, not the procedural judgment a field accepts.
Harness Engineering: Anatomy, Architecture, and Evolution of Coding Agents -- A Source-Code Study of Eleven Systems
A source-code anatomy of eleven production coding harnesses including Claude Code, Codex CLI, Gemini CLI, Aider, OpenHands and OpenCode, mapped onto seven canonical subsystems.
Why it mattersThe closest thing yet to a reference architecture for the runtime around a coding model: loop, tools, context management, safety controls, orchestration and extension surfaces, compared implementation by implementation.
Don't Let the Model Write the YAML: Deterministic, Minimal-Diff GitOps Remediation from LLM-Proposed Field Changes
Measured on real Kubernetes manifests, no text-generation strategy is safe for unattended GitOps remediation.
Why it mattersIf an agent authors your YAML edits, a tolerant patch tool will apply broken changes with no error signal. Emitting a structured field change and letting deterministic code perform the edit removes that failure class.
Can MCP Clients Decide What to Do After Failure? A Result-Only Actionability Audit
An audit of what a client can deterministically infer from a completed MCP failure result alone.
Why it mattersIf you branch on MCP tool failures, isError plus typed fields will not tell you whether to retry, reauthenticate, fix an argument, or switch tools. Recovery logic ends up interpreting prose, which is the fragile path.
GUI-CC: Benchmarking Contextual Consistency of GUI World Models as Agent Environments
GUI world models are usually scored as one-step next-screen predictors, but agents use them as environments.
Why it mattersIf you train or evaluate GUI agents against a generated environment, next-screen accuracy is the wrong metric. Contextual consistency over a rollout is what determines whether the environment is usable at all.
Long-Horizon State Tracking in LLMs: Executing MD5 through a Deep Sequence of Dependent Tool Calls
An evaluation that strips agent tasks down to one variable: can a model carry exact intermediate state across long chains of dependent tool calls?
Why it mattersAgent benchmarks confound instruction understanding with state tracking, so a long run that fails cannot be diagnosed.

Alibaba refreshed its Qwen3.8-Max snapshot: 2.4T parameters, a 1M token context window, and extra post training for coding and long horizon workflows. Live on QwenCloud at $2 per million input tokens and $6 output, with explicit cache hits at $0.17 and implicit at $0.25.
Why it mattersA 1M context model tuned for long horizon agent runs is callable now at $2 per million input tokens, with explicit cache hits at $0.17, which changes the cost math for long running agents.

Arcee's hosted API now serves GLM-5.3 and GLM-5.3-Flash, extending a catalog it opened two weeks earlier beyond its own Trinity line to DeepSeek, Kimi and Inkling. All of them sit behind a single endpoint and are callable from its nac agent for long-running, hands-off work.
Why it mattersOne endpoint now covers several open-weight families, so you can move between GLM, DeepSeek, Kimi and Trinity without changing auth or clients, including from the nac agent for long-running jobs.
An index of the vibe-coding frontier. Corrections welcome.