Intel
Page 72
Agreement Is Not Alignment: Divergent Moral Grounds in Human and LLM Ethical Judgments
Across frontier and open models on a 500-item ETHICS-derived set, final-label agreement with human annotators runs high while the stated justifications diverge.
Why it mattersHigh label agreement with human annotators can hide divergent underlying reasoning — if your eval only scores final answers, it is measuring less alignment than you think.
Dual-Flow Transformers: Decoupling the Primary Prefill Path from Additional Decode Computation
A transformer design that splits inference in two.
Why it mattersInference cost now dominates training cost for served models, and this decouples the two phases so added capability does not tax both.

Qwen3.8-27B is now packaged for LM Studio and needs roughly 17GB to run locally, putting a fresh open-weights release on consumer hardware without an API bill. Practitioners in the replies report multi-hundred-token/s prefill and long-context runs on Apple silicon.
Why it mattersQwen3.8-27B runs locally in about 17GB and is already packaged in LM Studio, putting a current-generation open-weights model within reach of a single well-specced laptop.
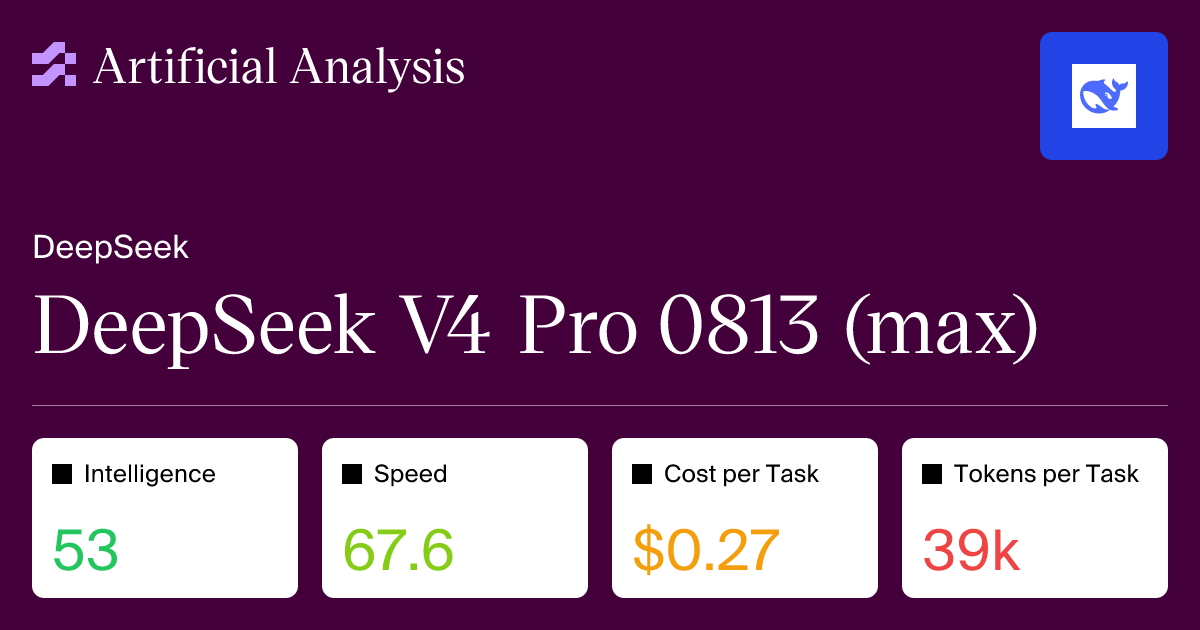
See Artificial Analysis for further details and benchmarks:
Artificial Analysis's evaluation of DeepSeek V4 Pro 0813.
Why it mattersDeepSeek V4 Pro 0813 lands near the top of the intelligence index but at 3.6x the prior price, scoring only a point above the far cheaper V4 Flash — the open-weights price/quality choice has shifted.

Artificial Analysis scores DeepSeek V4 Pro 0813 at 53 on its Intelligence Index, eight points above April's version but with a 3.6x price rise, leaving it barely ahead of the cheaper V4 Flash and still behind Kimi K3 among open-weights models.
Why it mattersTeams building on DeepSeek's first-party API face a 3.6x price change within a day, and the intelligence gain over the cheaper Flash model is a single point. The cost-per-task math changes which model is the rational default.

Hacktron's automated review found a high-severity NoSQL injection in Novu's codebase by tracing an unvalidated ID through an ingest controller, a type cast, and a sink service across three files.
Why it mattersHacktron's automated review caught a NoSQL injection in Novu by tracing an unvalidated event ID across three files, and fixed roughly half of flagged issues within 30 days with an 83% actionable rate.

SemiAnalysis lays out the cost case pulling hyperscalers to India: roughly $5M per MW of datacenter capex and power often under $0.10/kWh, cheap enough to put the country near 10GW by 2030 and among the four largest datacenter markets, with Microsoft alone committing $17.5B.
Why it mattersCompute capacity is migrating toward the cheapest power and capex, and India's sub-$0.10/kWh economics put it on track for roughly 10GW by 2030 — a factor in where inference gets served and what it costs.
Did you know Hermes Desktop can run against a Hermes Cloud agent? Point Hermes D
Nous Research details how Hermes Desktop connects to a Hermes Cloud gateway.
Why it mattersHermes agents can now run as always-on cloud workers reachable from Telegram, Discord, Slack, or CLI, with memory that persists across devices — relevant if you are deciding where long-running agent state should live.

Qwen3.8 27B Is INSANE – This Is the BEST Local AI Model Yet!
A hands-on test of Qwen3.8 27B running locally, across browser workflows, C++ game creation, FPS development, 3D CAD modelling, multimodal coding and cinematic game generation.
Why it mattersTask-level results on a 27B model running locally give a practical read on where local inference is now good enough for coding work and where it still falls short.
Don't classify. Hallucinate!
Doug Turnbull's trick for tagging against a large vocabulary.
Why it mattersIt turns an oversized label set from a context problem into an embedding lookup, which is directly reusable by anyone classifying against a taxonomy too large to fit in a prompt.
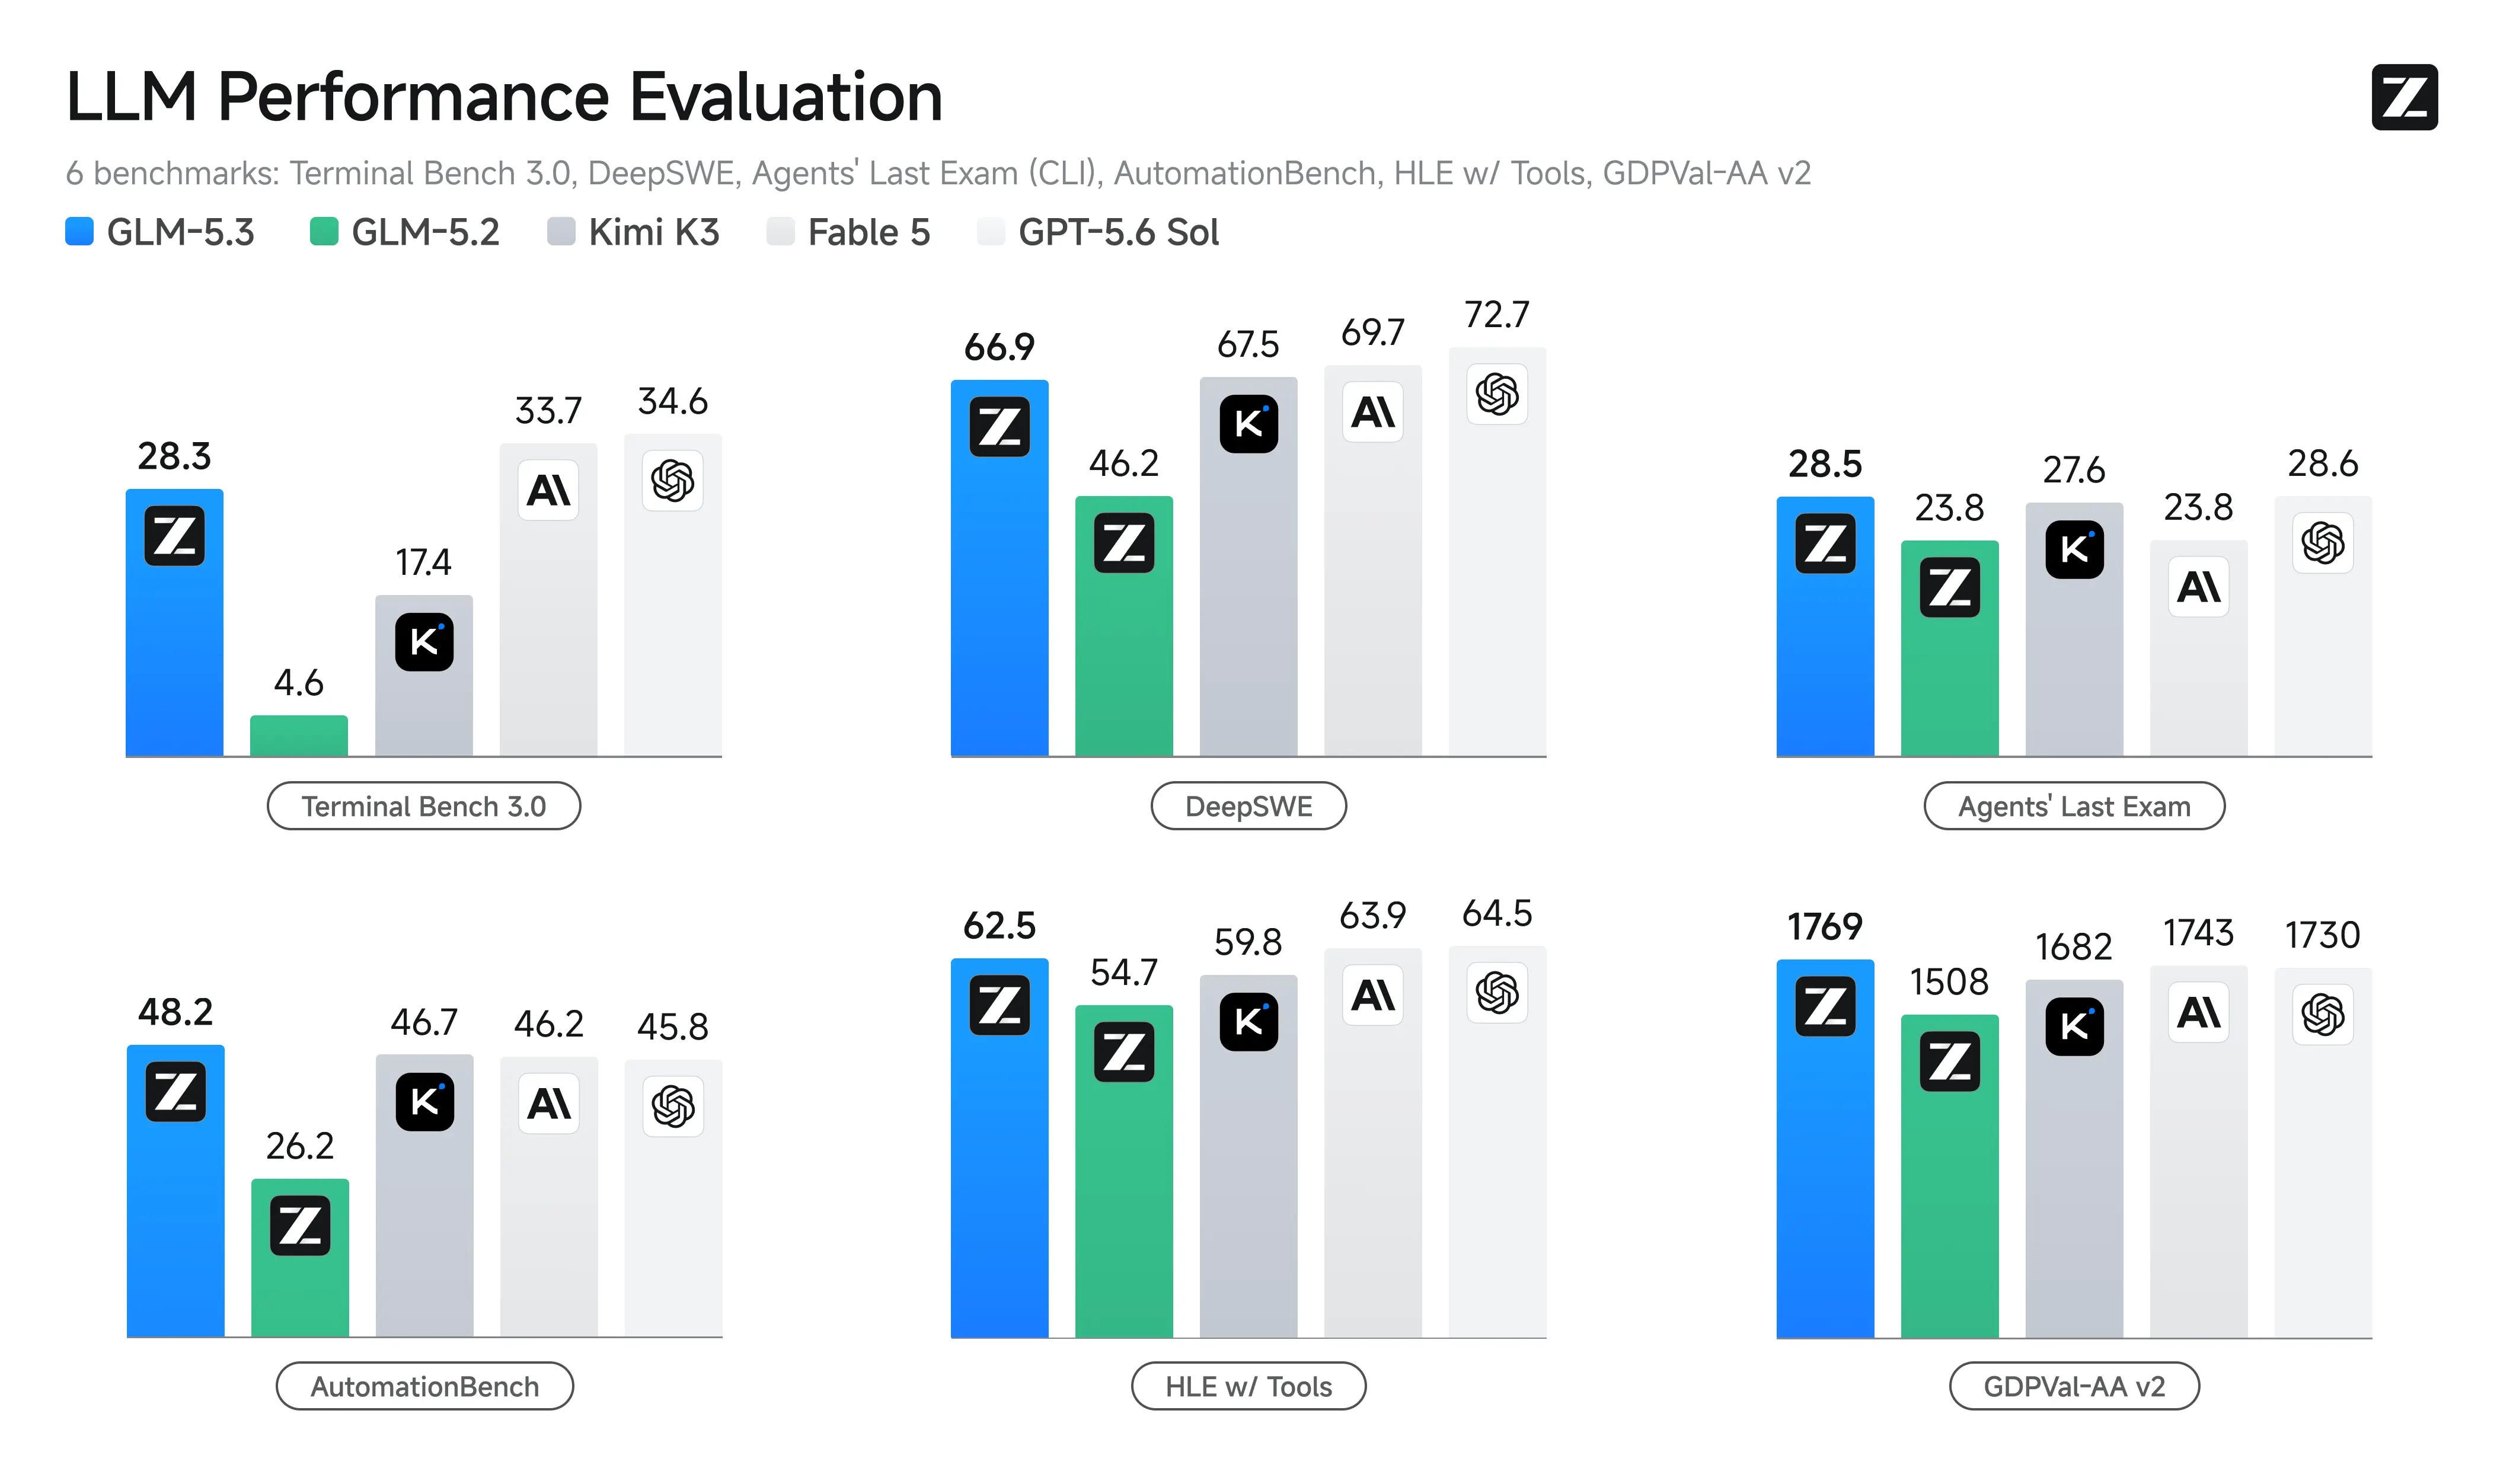
GLM-5.3: How Chinese labs keep stride with the frontier
Nathan Lambert on Z.ai's GLM-5.3.
Why it mattersA frontier-level agentic coding score reached purely through post-training on an existing base, at a third of a competitor's parameter count, resets what teams should assume about the cost of catching up.

Hermes adds /loop, which re-runs a prompt on an interval in the same session; leave the interval off and it paces itself, checking often at first and backing off while nothing changes.
Why it mattersRecurring self-paced agent runs are a scheduling primitive most harnesses lack, so builders comparing agent runtimes now have a concrete reference implementation of interval versus adaptive polling.
https://t.co/w4CBckqLpR
Hermes documents recurring in-session loops.
Why it mattersA concrete pattern for in-session recurring agent turns: back off while output is unchanged, snap back to the floor when it changes, and use cron instead when work must survive the terminal.
SemiAnalysis on GLM-5.3 beating every American open model with gains that came entirely from post-training on the same base as GLM-5.2, and what that says about the Nemotron committee path.
Why it mattersIt puts a concrete stake in the open-weights comparison: if post-training alone produced the jump, the gap between American and Chinese open models is a process gap rather than a compute gap.
We’ve written an FAQ to answer some of the questions we've received about waterm
Anthropic's FAQ on watermarking Claude's text.
Why it mattersAnyone shipping model output into their own product now knows what watermarking does and does not change about that text, including that it costs no extra tokens and carries no per-user attribution.

A 17-minute tour of OpenWiki, LangChain's open-source self-maintaining wiki: how it works, why documentation built for agents looks nothing like documentation for humans, and the lessons from building it.
Why it mattersAgent-readable documentation is becoming a design surface of its own, and this gives builders a working open source reference for how those docs should be structured and kept current.
To configure auto mode for your environment, run /auto-mode-setup. Claude looks
Claude Code's /auto-mode-setup scans your repo and proposes trusted repositories and domains for review, sharpening the auto-mode classifier's line on what is safe to run in your environment.
Why it mattersPermission configuration is the main safety lever on an autonomous coding agent, and this documents exactly how the trusted-surface list is built and reviewed.

Auto mode rolls out as Claude Code's default for Pro, Max and Team. Existing default-mode settings are respected, and modes still switch via Shift+Tab or a settings pin.
Why it mattersA shift in the default permission mode changes what a coding agent will do without asking, so anyone running Claude Code in a shared or automated setting needs to check their configuration.
WRITER Makes Agentic AI Economically Sustainable at Enterprise Scale With Palmyra X6 Release and Major Harness Upgrades
WRITER ships Palmyra X6 plus harness upgrades built around token economics rather than benchmarks.
Why it mattersAgent workflows push cost per task orders of magnitude above chat. This release pairs a cheaper flagship model with harness changes and spend controls aimed at that gap, reported as 52% lower cost at 48% higher speed.

ori grok starts xAI's Grok Build in custom-endpoint mode and hands it an OpenRouter key scoped to that run, so no browser login happens and your Grok config is unchanged. Model list becomes your OpenRouter catalog, private endpoints included, with telemetry and trace upload pinned off.
Why it mattersYou can run Grok Build against any OpenRouter model without a Grok login, with stray provider keys neutralized and xAI telemetry and trace upload disabled for the run.
Ori DeepSeek wires DeepSeek Harness to OpenRouter in one command: it installs the harness if missing, stores the key in the harness credential store, refreshes the model catalog on every boot, and adds /fast routing plus /zdr zero-retention sessions.
Why it mattersOne command swaps a single-vendor harness onto the full OpenRouter catalog, with a session flag that restricts a run to zero-retention providers when the code cannot be logged.
As part of our Responsible Scaling Policy, we publish regular Risk Reports. Thes
Anthropic has published the second of its recurring Responsible Scaling Policy Risk Reports, its disclosure of assessed risks across its systems and its readiness to mitigate them.
Why it mattersAnthropic's periodic RSP risk reports are the primary public record of how the lab assesses its models' dangerous-capability thresholds and what safeguards gate them.
ori prime runs Prime Intellect's Agent against 500+ OpenRouter models without writing auth.json or models.json; the key arrives via a bundled extension scoped to the run. Ori strips leftover ANTHROPIC_API_KEY and OPENAI_API_KEY values, and /speed and /zdr persist with the session.
Why it mattersAnother agent harness runs on a single OpenRouter account without editing its config, with stray provider keys stripped and zero-retention routing toggleable for the session.
Qwen3.8-27B lands on Ollama, pitched as delivering consistently across whatever harness you run it in.
Why it mattersA 27B frontier-adjacent model landing on Ollama puts it within reach of a single workstation, which changes the local-inference options for anyone building agents that cannot call a hosted API.
Learn how to turn one giant AI-generated pull request into a clean, reviewable s
GitHub on turning one giant AI-generated pull request into a clean, reviewable stack of changes, and keeping every layer in sync as review feedback lands.
Why it mattersReview throughput is the bottleneck once coding agents can produce thousand-line diffs, and stacking gives teams a repeatable way to keep each layer small enough to actually verify.

GitHub's prescription for the giant agent-authored pull request: break it into a stack of ordered PRs, one concern per layer, with CI validating each layer against the stack's base. The gh stack CLI creates, submits, rebases and syncs the stack; reviewers read top-down and validate bottom-up.
Why it mattersA concrete review workflow for AI-generated changes: layer the work into ordered PRs, run CI per layer against the stack base, read top-down and review bottom-up instead of facing one 1,700-line diff.
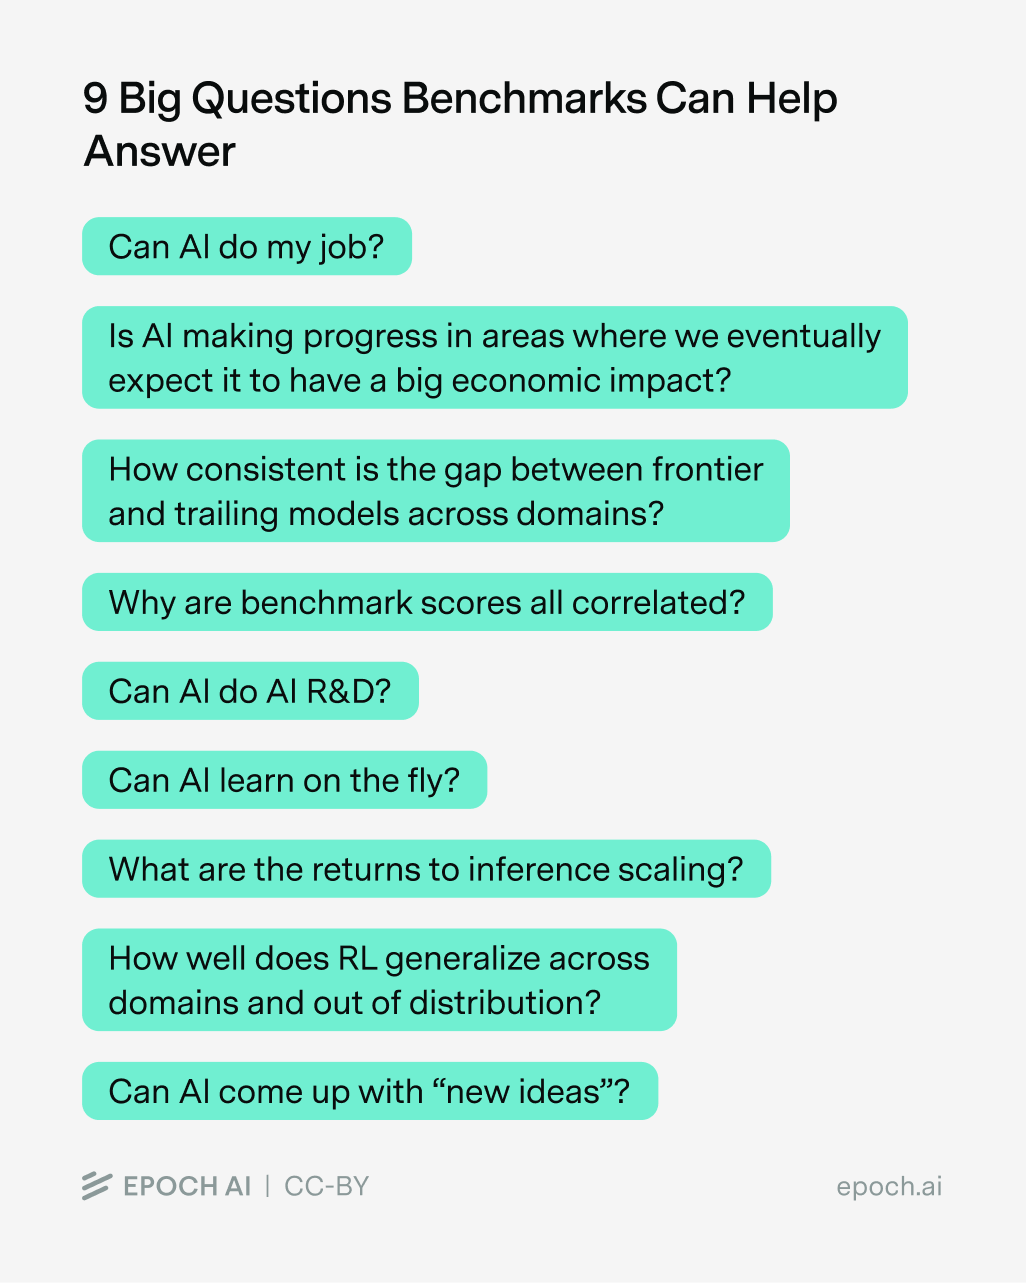
9 Big questions benchmarks can help answer
An Epoch researcher lists nine questions governing AI's impact, from narrow tasks versus messy jobs to learning from experience, and maps benchmark efforts to each.
Why it mattersNames which unresolved capability questions benchmarks should answer, helping engineers judge which evaluation results actually predict real-world agent usefulness.

How Web Data Infrastructure Powers the Next Generation of AI — Patricija Žemaitytė, Oxylabs
Oxylabs on rebuilding a search API from a four-second baseline to 550 milliseconds, and why something that works in development, something that passes tests.
Why it mattersThe load-testing observation, that instrumentation at high request volume distorts the measurement it is taking, is a failure mode teams hit when scaling any high-throughput data pipeline for AI.

The Rise of CaaS: Context-as-a-Service for Agentic AI — Omer Primor, Bright Data
Bright Data's Omer Primor puts the crossover at roughly 15,000 queries, past which building your own pipeline beats renting context.
Why it mattersIt gives a concrete break-even figure for the buy-versus-build decision on agent context data, which is otherwise argued on vibes.
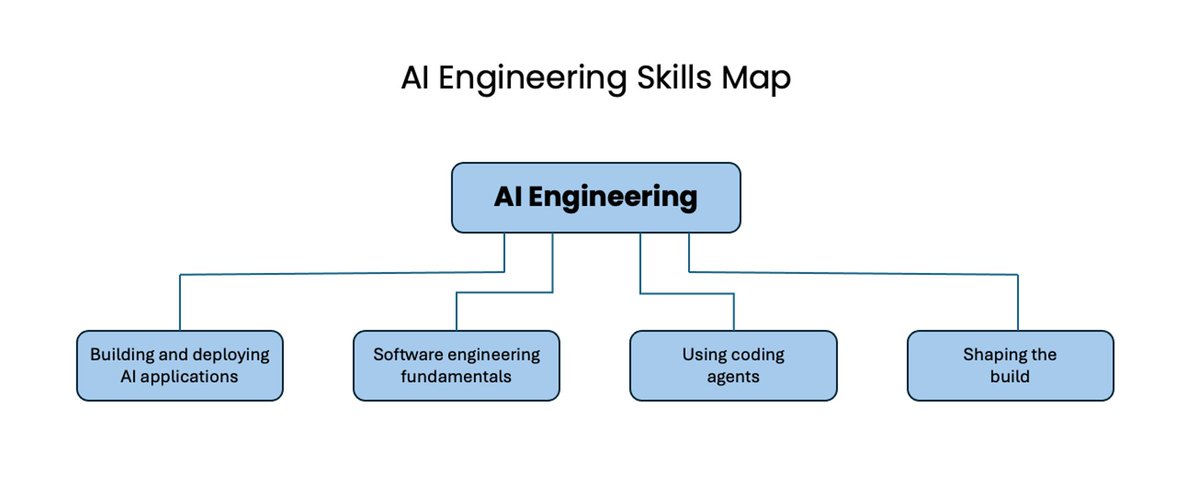
Four skills that define AI engineering, drawn from 10,000 job postings
Synthesized from job postings, expert interviews and surveys: four skills defining AI engineering.
Why it mattersA learning and hiring frame grounded in labor-market data, with "shaping the build" identified as the skill that shifts most as agents get better at delivering to a spec.
How to bring your software delivery workflow into GitHub with agent apps
GitHub agent apps let third-party services answer questions inside the pull request.
Why it mattersAnalytics, dependency risk, feature flags, and incident state can now be queried by agent from inside a pull request rather than four separate tools, using the same harness that backs the Copilot cloud agent.
Alibaba released Qwen3.8-27B as open weights with day-0 SGLang support: 206 tok/s decode on a single RTX 5090 using NVFP4 with DSpark, and 38 tok/s on a DGX Spark — a small dense model aimed squarely at running on hardware people already own.
Why it mattersA current-generation 27B dense model decoding at over 200 tokens per second on one consumer GPU puts local agent loops within reach without server hardware.
One GPU, 1M context, Day-0 ready. Big props to the vLLM team for the seamless in
The vLLM deployment recipe for Qwen3.8-27B.
Why it mattersVerified launch flags and measured KV-cache footprints per precision — including NVFP4 fitting a 27B model on a single Blackwell card — let you size hardware before committing to a deployment.

The Dark Arts of Web Automation: Teaching Agents to Use Websites Like Humans — Corey Gallon, Rexmore
Corey Gallon on driving a browser through the Chrome DevTools Protocol so an agent's clicks travel the same path as a human's, escalating from synthetic click to real CDP input event to a jittered mouse path only as far as the page forces.
Why it mattersIt explains why browser agents silently fail on real sites and gives a concrete escalation strategy and control split that anyone building web automation can apply directly.
Z.ai details GLM-5.3's leap in exploit analysis and staged release
GLM-5.3 posts large gains in cyber tasks (CyberGym 84.5%, ExploitBench 54.4%, more completed ExploitGym tasks than GLM-5.2) and will ship weights only after staged access to vetted security partners, backed by a public vulnerability disclosure ledger.
Why it mattersGLM-5.3 more than doubles GLM-5.2's score on exploit-analysis benchmarks and introduces a public disclosure ledger, changing what a security researcher can expect once the open weights ship.

Bringing agents onto the world wide web — Paul Klein IV, Browserbase
Browserbase's Paul Klein argues browser agents are limited by engineering rather than models.
Why it mattersIt reframes browser agent reliability as work any team can do now rather than a wait on the next model, and names the specific architecture choices that separate production systems from demos.
OpenRouter benchmarked Exa, Parallel, Perplexity and native search across four models and four search depths. Budget mattered most: 1 to 25 turns roughly doubled BrowseComp scores. Model choice moved results ~15 points, engine choice ~10. Incorrect runs averaged 19.7 searches against 10.3 for correc
Why it mattersConcrete numbers for tuning agent search: raising the turn budget helps most, expect failed queries to nearly double search spend, and do not assume a lab's native search beats a third-party engine.
Open Season

Liquid AI's LFM2.5 encoders detect and redact 40 PII types across 16 languages in a single pass, with the entity set selectable. They run inside your own pipeline, scrubbing text before it reaches a hosted model. Both 230M and 350M checkpoints are on Hugging Face.
Why it mattersRedaction runs locally in one forward pass with no generated output to parse, so confidential fields never leave your environment on the way to a hosted model.

Computer Use at the Edge of the Statistical Precipice — Pierluca D'Oro, Programma Labs
A sub-megabyte script that never looks at the screen, built by replaying one recorded trajectory per task, tops deterministic benchmarks like OSWorld.
Why it mattersAnyone reading computer-use benchmark numbers is likely reading an artifact of deterministic environments and undersized confidence intervals, and this gives both the proof and the environment design that fixes it.

How Cloudflare detects MCP traffic and helps secure it
Cloudflare on why agent traffic breaks the two assumptions behind human permissions, judgment and human speed, and the new controls it is shipping to detect and secure MCP traffic.
Why it mattersTeams running MCP servers get a way to see shadow MCP traffic and force agents through an approved path, which is the first practical control over what an agent can reach at machine speed.

Cursor confirmed its acquisition by SpaceX has closed. The team joins SpaceXAI to work on Grok, Grok Build, Grok Bot and the Grok API alongside Cursor itself, putting a widely used AI editor under the same roof as the Grok model line.
Why it mattersThe editor a lot of teams standardized on now shares ownership and engineering direction with a frontier model lab, which bears on model routing, data handling, and where Cursor's development attention goes.

Secure all your internal vibe-coded applications — in one click
Cloudflare adds one-click Access policies for Workers.
Why it mattersAnyone shipping internal apps built with coding agents can now make every preview and production deployment private by default with an account-level policy instead of trusting each builder to wire up auth.

Claude watermarks your code now
Anthropic is watermarking output from Claude models launched on or after 2 August, and this walks through how the marks work and why removing them already looks straightforward.
Why it mattersEngineers shipping Claude-generated code now carry a provenance marker they did not opt into, and the countermeasures are already public.
Have We Seen an Acceleration in Discoveries?
METR plots public discovery data across cyber vulnerabilities, math results and optimizations, looking for slope changes after January 2026.
Why it mattersPublic data shows vulnerability discovery accelerating sharply while optimization discoveries are not, which tells engineers where AI-driven discovery is already changing the threat and capability landscape.

GLM-5.3 is coming. focusing on coding. https://t.co/g10V8eJIwq
Why it mattersGLM-5.3 launches with post-training on a 743B-parameter base focused on coding and agentic tasks, plus what Z.ai calls a major leap in defensive cybersecurity capability among open-weight models.

GLM-5.3 is post-trained on the same 743B base as GLM-5.2 and targets agentic coding plus cyber defense, reportedly improving while emitting fewer output tokens. It ships through GLM Coding Plan and ZCode first, with API access and open weights staged behind safety evaluations.
Why it mattersBetter results at fewer output tokens changes the cost math on long agent runs, and the staged rollout means Coding Plan and ZCode are the only ways in at launch.

Ant Ling post-trains Ling-3.0-tiny with GSPO on a single DGX Spark using the AReno framework. Over 400 steps on a tic-tac-toe environment, mean reward moved from about -0.5 to 0.4 and responses shortened to roughly 850 tokens, with more stable tool calls. Tutorial and code are published.
Why it mattersAgentic RL usually implies a cluster. This closes the baseline, feedback, post-train and retest loop on one desktop-class box with a 7.9B model, and both the tutorial and the framework are public.
Refine After Generation: Toward Correct and Concise Patches in LLM-based Program Repair
Automatic program repair is now good enough that agentic systems routinely close real repository-level issues, so this paper asks a question the field mostly skipped.
Why it mattersQuantifies that a passing test is not a proxy for a clean patch: agent diffs are consistently bloated, and minimality prompts do not fix it.
Memorization Diagnostics for Code LLMs Should be Scale-Aware
Researchers argue memorization probes for code LLMs are scale-dependent.
Why it mattersIf you use contamination probes to judge whether a code model memorized a benchmark, those probes likely fail on exactly the large models you ship — the methodology, not the model, is what breaks.
An index of the vibe-coding frontier. Corrections welcome.